Loading...
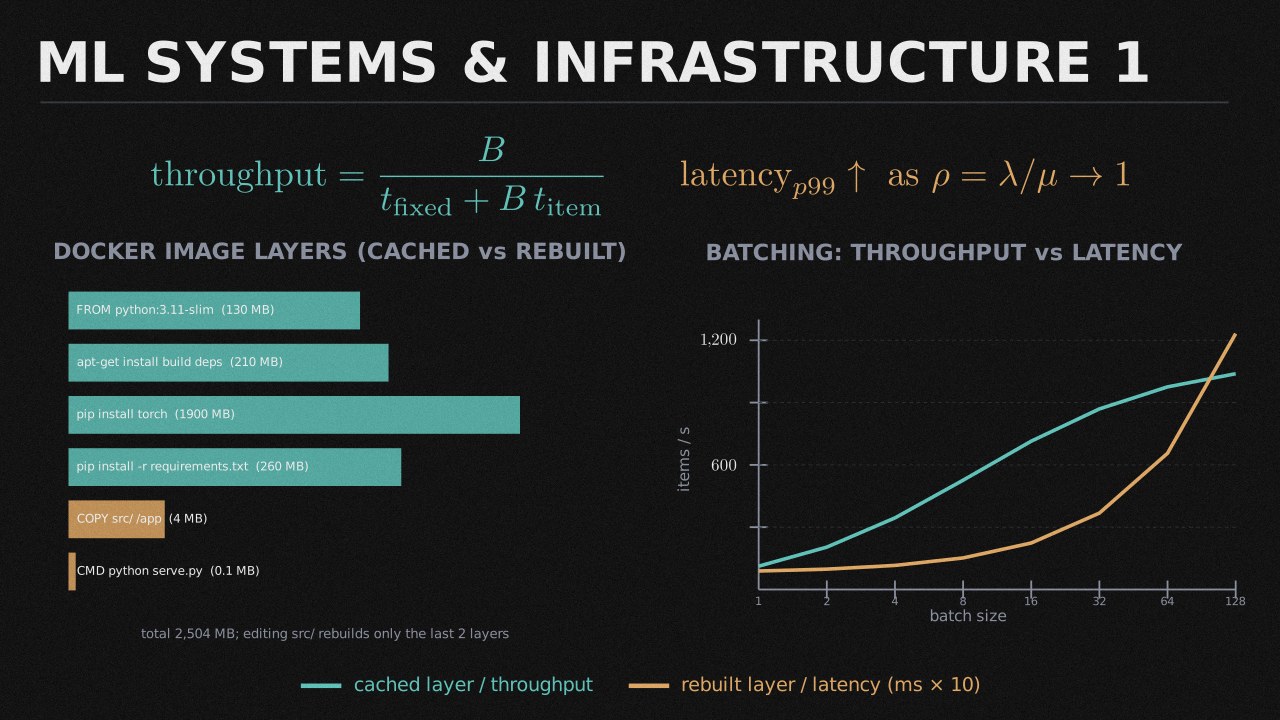
ML Systems & Infrastructure 1 — all 50 problems
Fifteen Python exercises that make you reason about the systems artefacts an ML platform runs on: Docker layer caches and image sizes, Kubernetes scheduling and rollouts, CIDR planning and firewall rules, SLO error budgets and tail latency, CI critical paths, retry backoff and spot-instance economics.
Container Images & Builds
- Multi-Stage Build Size ReductionEasy
- Effective Environment After Layered ENV InstructionsEasy
- Total Image Size from Unique LayersEasy
- Resolve an Image Tag from a Semver ConstraintMedium
- First Cache-Invalidated Build LayerMedium
- Highest Semver Matching a Caret RangeMedium
- Layer Reuse Ratio Across an Image SetMedium
- Order Build Stages by DependencyMedium
- Dockerfile Layer Cache InvalidationHard
- Minimum Rebuild Cost with Layer CachingHard
Kubernetes Scheduling & Rollouts
- Horizontal Pod Autoscaler Replica CountEasy
- Desired Replicas from CPU UtilizationEasy
- Does a Pod Fit on a NodeEasy
- Rolling Update Surge and Availability BoundsMedium
- Rolling Update Pod Availability BoundsMedium
- Bin-Pack Pods onto Nodes (First-Fit Decreasing)Medium
- Filter Nodes by Taints and TolerationsMedium
- Spread Pods Across Zones for Anti-AffinityMedium
- Bin-Pack Pods onto NodesHard
- Minimum Rollout Steps Under Surge and UnavailabilityHard
Networking & Addressing
- CIDR Subnet ReportEasy
- Usable Hosts in a SubnetEasy
- IPv4 Address to IntegerEasy
- Detect Overlapping VPC CIDR BlocksMedium
- Evaluate Security Group RulesMedium
- Is an IP Inside a CIDR BlockMedium
- Detect Overlapping CIDR BlocksMedium
- Aggregate Two Adjacent SubnetsMedium
- First Matching Security Group RuleMedium
- Longest-Prefix-Match Routing LookupHard
Observability & SLOs
- Tail Latency Percentiles (Nearest-Rank)Easy
- Aggregate Structured Log LinesEasy
- Error Rate from a Status-Code HistogramEasy
- Nearest-Rank Latency PercentileEasy
- Error Budget and Burn RateMedium
- Error Budget Remaining for an SLOMedium
- Multi-Window Burn Rate AlertMedium
- Merge Overlapping Incident Intervals for DowntimeMedium
- Aggregate Latency Histogram Buckets to a QuantileMedium
- Alert Deduplication with Flap SuppressionHard
Pipelines, Reliability & Cost
- Monthly Cost of a Running InstanceEasy
- Pipeline Stages Ready to RunEasy
- Capped Exponential Backoff ScheduleMedium
- Spot vs On-Demand Break-EvenMedium
- Critical Path Length of a Pipeline DAGMedium
- Retry with Capped Exponential Backoff and Jitter CapMedium
- Deduplicate Retried Pipeline Runs by Idempotency KeyMedium
- Spot vs On-Demand Expected-Cost DecisionMedium
- CI Pipeline Critical PathHard
- Minimum-Cost Job Scheduling Across Priced WindowsHard