Collections
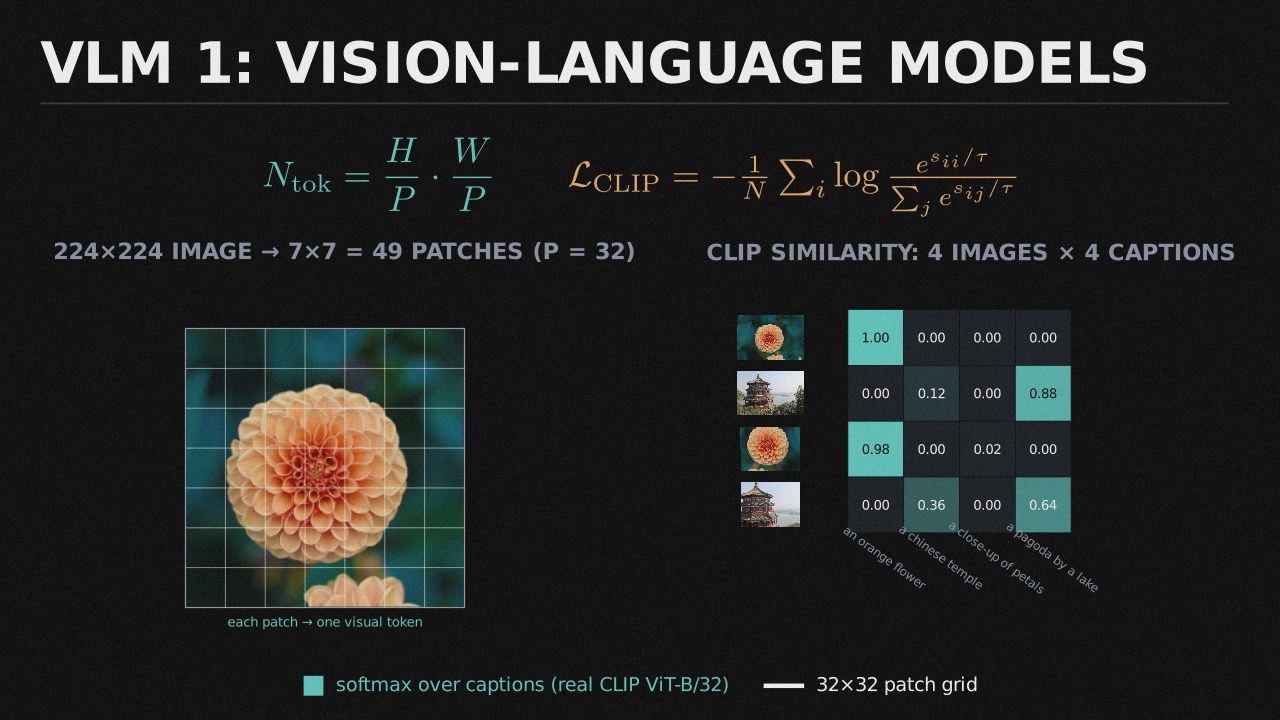
Multimodal architectures that ground language in vision — contrastive pretraining, cross-attention fusion, and instruction tuning.
1
collection
50
problems
5 topics · 50 problems
 FREE+FREE+FREE+