Vision-Language Models Projects
Zero-shot classification with CLIP, and image captioning and visual question answering with BLIP.
2 projects · GPU notebook · Premium only
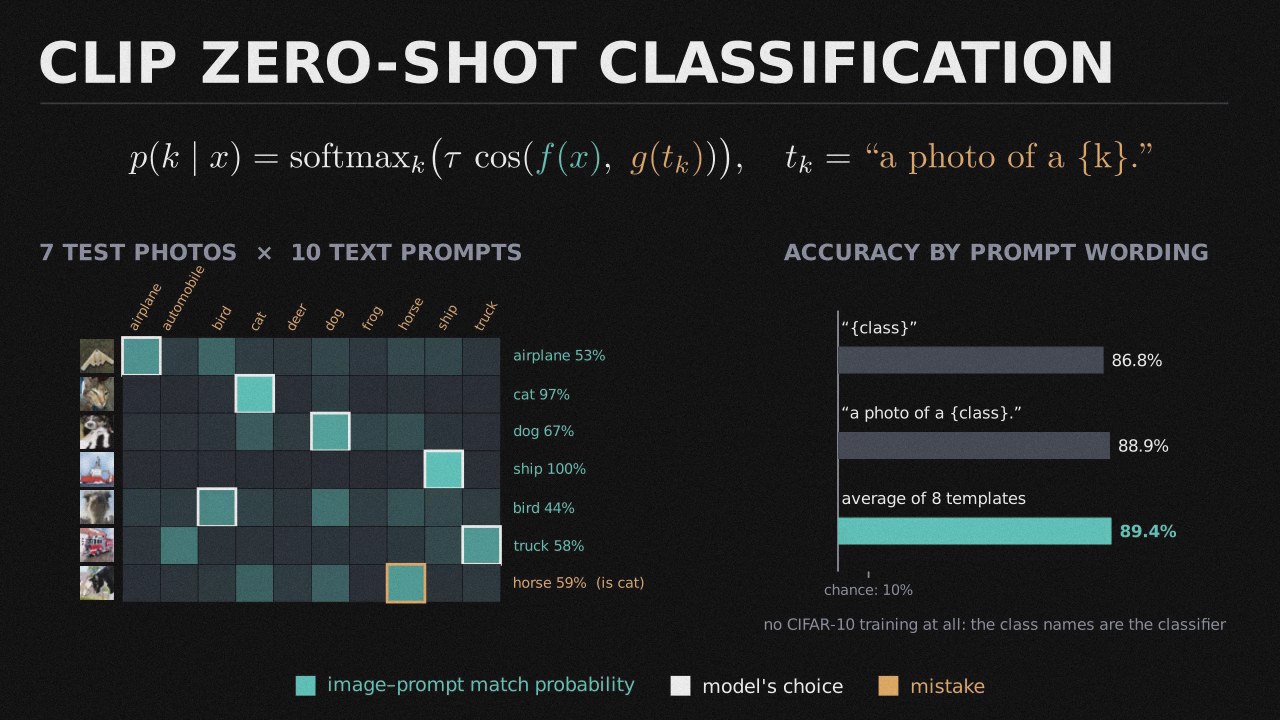
Zero-Shot Image Classification with CLIP
PROClassify CIFAR-10 images with no training at all: encode images and class-name prompts with OpenAI's CLIP ViT-B/32, normalise the embeddings and predict by cosine similarity. Compare prompt templates (bare label vs "a photo of a {}." vs a template ensemble), read a confusion matrix, then flip the model around for free-text image search. The first cell downloads the CIFAR-10 test split from the Hugging Face Hub (~24 MB) and the CLIP weights (~600 MB).
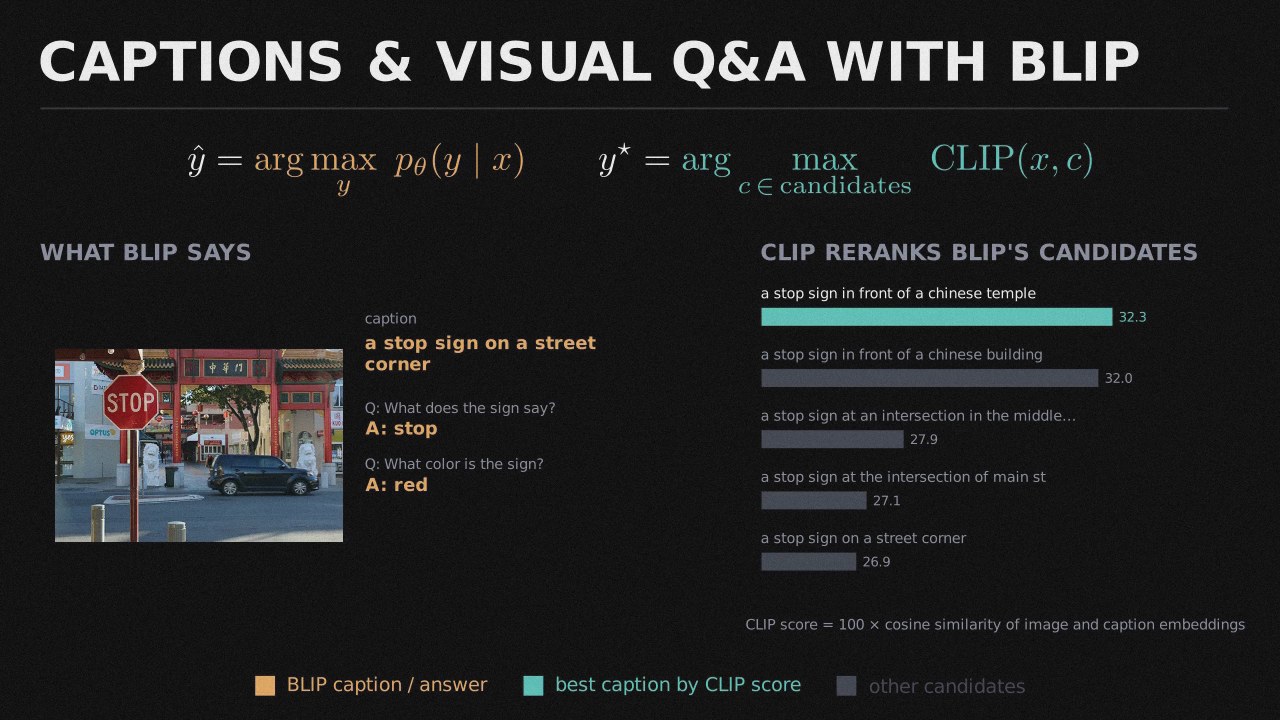
Image Captioning & Visual Q&A with BLIP
PROMake a model describe and answer questions about real photos. Caption images with BLIP and compare greedy, beam-search and nucleus-sampling decoding, ask BLIP-VQA questions about each photo, then generate a pool of candidate captions and rerank them with CLIP image-text similarity. Model weights download the first time each is loaded: BLIP captioning (~1 GB), BLIP-VQA (~1.5 GB) and CLIP (~600 MB).