Newest projectGPU ProgrammingPRO
Tiled Matrix Multiplication in Triton
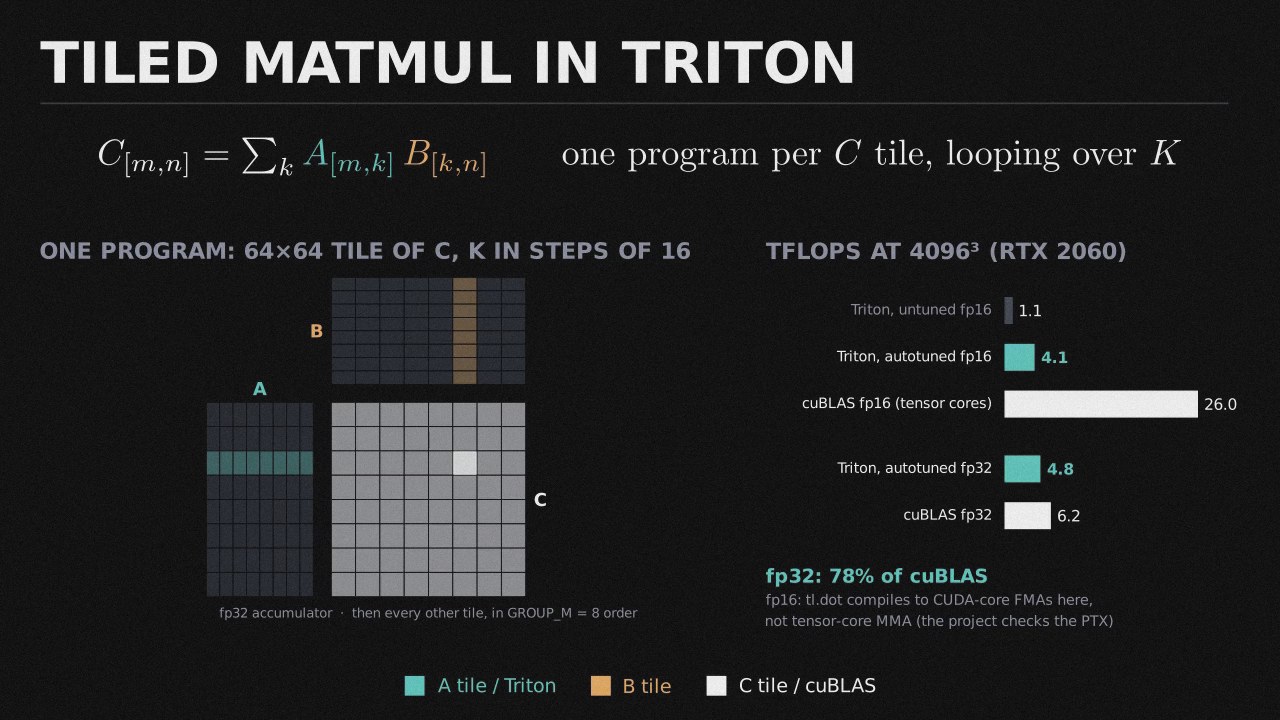
Build a matrix multiply in Triton from scratch. You'll write a blocked fp16 kernel that walks the K dimension in BLOCK_K steps with tl.dot and an fp32 accumulator, masking ragged edges, and check it against torch.matmul on shapes that aren't multiples of the tile. You'll read the compiled PTX to see what tl.dot became: on the T4 (Turing, sm_75) Triton 3 runs it as FMAs on the CUDA cores, not on the tensor cores. Then you'll add grouped tile ordering, @triton.autotune over a small set of tile configs and a fused leaky-ReLU epilogue, and benchmark TFLOPS against cuBLAS in fp16 and fp32. The goal is to learn the mechanics of tiling and autotuning, not to beat cuBLAS. Nothing to download.
Hard4 sections9 cellsSynthetic fp16 matrices
Open notebook