Reinforcement Learning
RL 1: Foundations
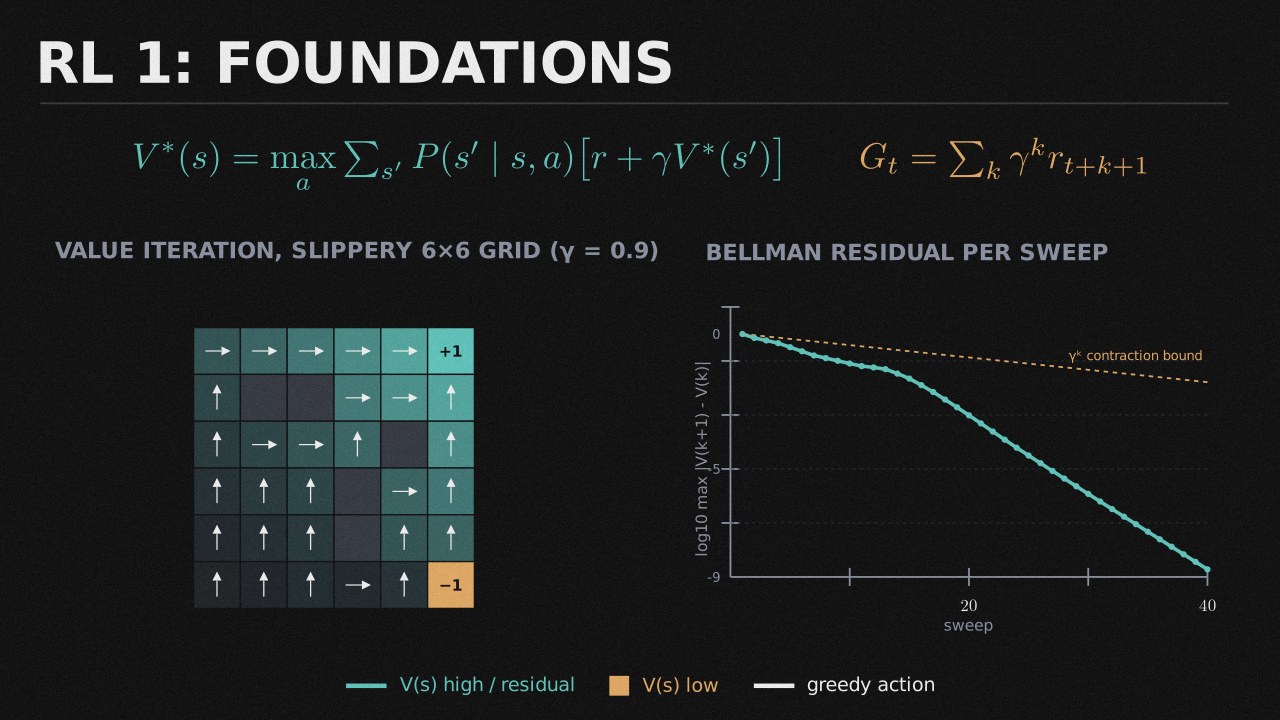
Fifteen implementation exercises covering the computational core of reinforcement learning: discounted returns, the Bellman expectation and optimality equations, dynamic programming, temporal-difference learning and control, and modern policy-gradient objectives including GAE and PPO's clipped surrogate.
50
problems
5
topics
15
free
01
Dynamic Programming
10 problems- 1Greedy Policy ImprovementFREEEasy
- 2Greedy Policy from Action ValuesPROEasy
- 3Policy Stability CheckPROEasy
- 4Iterative Policy EvaluationFREEMedium
- 5One Sweep of Iterative Policy EvaluationPROMedium
- 6Q-Values from State ValuesPROMedium
- 7Value Iteration Bellman ErrorPROMedium
- 8Async In-Place Value Iteration SweepPROMedium
- 9Value Iteration on a Small MDPFREEHard
- 10Full Value Iteration to ConvergencePROHard
02
Markov Decision Processes and Bellman Equations
10 problems- 11Marginalising the MDP Dynamics FunctionFREEEasy
- 12Expected Immediate Reward of a PolicyPROEasy
- 13Normalize a Transition RowPROEasy
- 14Solve the Bellman Expectation Equation ExactlyFREEMedium
- 15Bellman Optimality Backup on Action ValuesPROMedium
- 16One-Step Bellman Expectation BackupPROMedium
- 17Bellman Optimality BackupPROMedium
- 18Marginalize Next-State DistributionPROMedium
- 19Effective Horizon of a Discount FactorPROMedium
- 20Policy Evaluation by Linear SolveFREEHard
03
Policy Gradients and Advantage Estimation
10 problemsSign up free to see all 50 problems
Create a free account to see the full RL 1: Foundations list, track your progress, and save problems to lists.
Sign up free