Repo-To-Skill
Distilling GitHub Repositories Into AI4AI Skills
Jianlyu Chen, Yuyang Hu, Hongjin Qian, Jiawei Liu, Wenqing Wei, Xiaolong Chen,
7
Concepts
10
Formulas
5
Figures
5
Demos
Paper Overview
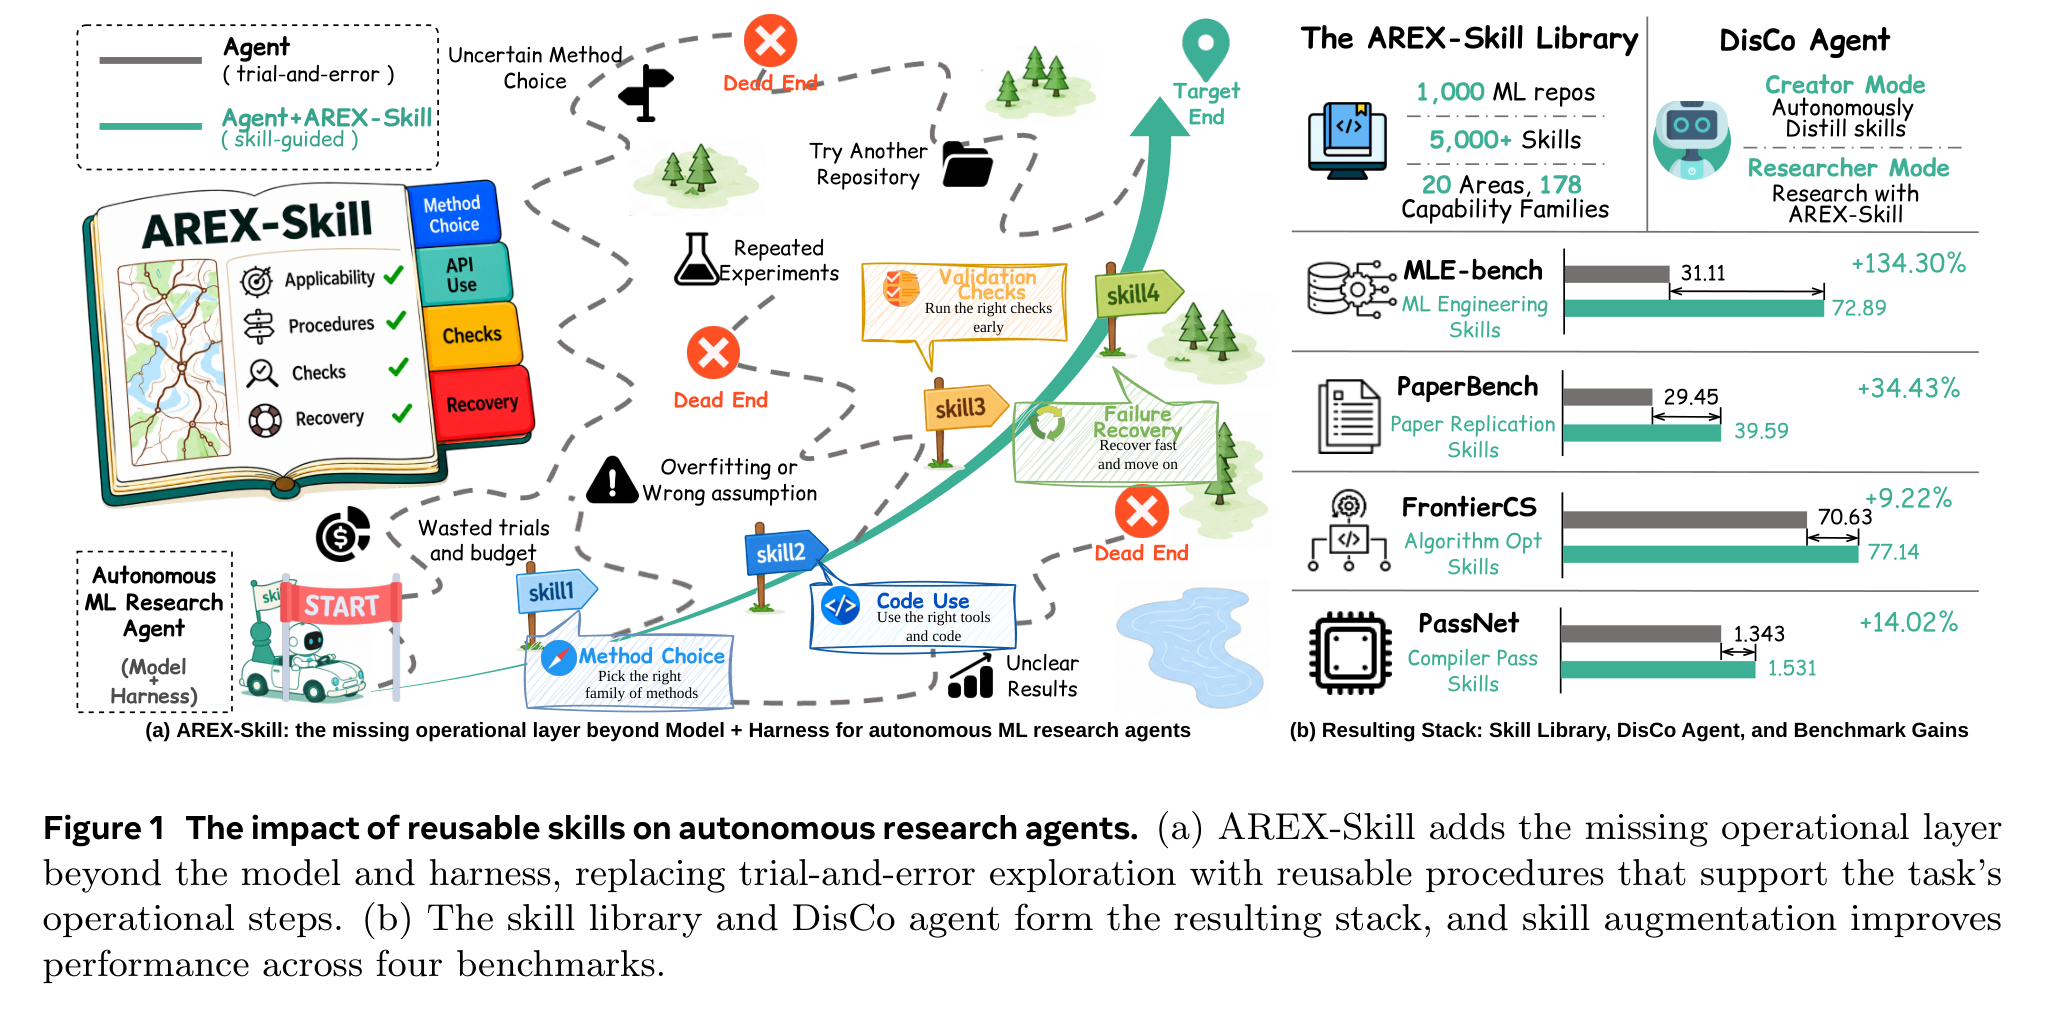
Repo-To-Skill (Chen, Hu, Qian et al. — Beijing Academy of Artificial Intelligence, USTC, Renmin University and Hong Kong Polytechnic, arXiv 2026) starts from an observation about where autonomous ML-research agents actually fail. These agents are built from two parts: a model that reasons and plans, and a harness that orchestrates, remembers, and verifies. Both keep improving — and yet the agent still stumbles on things a competent practitioner would never get wrong, because the domain-specific know-how that separates knowing a method from making it work lives in neither part.
The paper names this missing layer operational knowledge and argues it already exists — scattered across repositories, papers, and blog posts — but in forms written for humans and far too large to load during a task. The proposal is to distill that material into compact, verified Agent Skills: a SKILL.md entry point over reference documents and executable scripts, revealed to the agent only when a task calls for them.
The system that does this is DisCo, a single agent that both creates skills and researches with them. Run across the open ecosystem, its creator mode produces the AREX-Skill Library: 5,353 verified skills distilled from 1,000 widely used ML repositories, organized by a router over 20 areas and 178 capability families.
The evaluation is a clean ablation. Holding the GPT-5.5 backbone, the Codex research harness, and the downstream execution budget fixed, the only variable is whether the agent has the distilled skills. With them, it scores 134.3% higher on MLE-bench, 34.4% higher on PaperBench, 9.2% higher on FrontierCS, and 14.0% higher on PassNet — gains that come purely from adding operating context, not from a stronger model or a new control loop.
Chapter Roadmap
Click any topic to jump in
The Missing Layer
A research agent is a model plus a harness — and neither carries the domain know-how that turns knowing a method into making it work.
Skills and Skill Graphs
Package operational knowledge as agent-facing skills — a SKILL.md interface over references and scripts — linked into a graph the agent reads on demand.
Skill Distillation
Rework declarative sources into skills through one four-stage loop: scope, ground, construct, verify. No skill is admitted unverified.
Creator and Researcher Modes
DisCo both writes skills (creator, paid once per source) and researches with them (researcher, paid per task) over the same backbone and harness.
The AREX-Skill Library
5,353 verified skills from 1,000 ML repositories, routed over 20 areas and 178 capability families.
Evidence and caveats
Results
With backbone, harness and budget held fixed, skills lift MLE-bench 134.3%, PaperBench 34.4%, FrontierCS 9.2%, PassNet 14.0%.
When Skills Help
Gains concentrate on hard, low-baseline tasks and are uncorrelated with extra token spend — but two PaperBench tasks regress on retrieval-precision failures.
Concept by concept
7 sections, in reading order.
Ask an agent to improve a model on an unfamiliar dataset and it must decide which method suits the problem, which package implements it, how that package wants the data laid out, which configurations are appropriate, and which pitfalls silently invalidate an otherwise plausible run. It can infer all of this by trial and error — propose a plan, run it, inspect the failure, revise. The trouble is that those failures spend the same budget reserved for evaluation, and a single misconfigured run can burn a large share of it before producing any meaningful measurement.
The paper formalizes a research task as τ=(q,D,E,g) — a problem q, its data and material D, an environment E that exposes tools and bounds a budget, and a target g the result must meet — and the standard agentic system as A=(Mθ,H): an LLM backbone and a harness. The backbone supplies understanding, reasoning, planning, and execution; the harness supplies orchestration, memory, verification, and iterative refinement. Almost all recent progress has come from strengthening one or the other. But for research tasks, the two-component view leaves something unspecified: the backbone's prior is broad but fixed, and the harness controls procedure but supplies no domain content.
That gap is what the authors call operational knowledge — the expertise that binds the field's methods and tools to the task at hand by specifying what can solve it, when each candidate applies, and how it should be used. They write the research agent as Ares=(Mθ,H,K), adding an explicit operating context K. Operational knowledge has two constituents that must travel together: one turns knowledge into capability (methods, code, models, and APIs packaged into things the agent can actually invoke), and the other turns capability into usage policy (the conditions, reasons, and procedures that govern each unit's use). Capability without policy is a tool with no selection criteria; policy without capability is advice with no executable interface.
Crucially, this is not the harness in disguise. The harness specializes how an agent explores; K specializes what it knows to consider. And declarative sources — a paper reporting that a technique improves accuracy, a repo documenting what an API accepts — state what holds, never a course of action for a given problem. The central methodological problem is to derive operational knowledge from that declarative material automatically and at scale.
Key Points
- 1
A research task is formalized as τ=(q,D,E,g) and the conventional agent as A=(Mθ,H) — a backbone plus a harness
- 2
Neither component carries domain know-how: the backbone's prior is broad but fixed, the harness controls procedure but not content
- 3
Without it, an agent loses budget within a task (inferring package behavior by trial and error) and fails to reuse what it learns across tasks
- 4
Operational knowledge is what turns knowing about a domain into being able to act in it — binding methods and tools to the problem
- 5
It has two complementary constituents: capability (invocable methods, code, APIs) and usage policy (when, why, and how to use each unit)
- 6
The research agent becomes Ares=(Mθ,H,K), where K is the operating context; the step policy becomes at∼πθ(a∣τ,ht,H,K)
- 7
The methodological challenge: produce operational knowledge automatically and at scale from declarative sources that drift with every release
Mathematical Formulation
The Research Task and Agent
τ=(q,D,E,g),A=(Mθ,H)⟶Ares=(Mθ,H,K)
A task couples a problem q, its data D, an environment E (tools plus budget), and a target g. The standard agent is a backbone plus a harness; the research agent adds K, an explicit operating context carrying the operational knowledge the other two components never supply.
The Agent Loop with Operating Context
at∼πθ(a∣τ,ht,H,K),ot=E(at)
At step t the agent conditions on the task, the history h_t, the harness H, and now the operating context K, acts, and observes the environment's response. K enters the conditioning of every action rather than adding a new control loop.
If operational knowledge is the layer, a skill is its carrier. The paper instantiates K as a set of skills, K={S1,…,Sm}, so the problem of producing operational knowledge becomes the problem of producing skills. Skills are a practical choice: a skill is self-contained, agent-facing, and already supported by modern agentic systems like Claude Code and Codex, so making one available requires no change to the backbone or the harness. It simply becomes part of the operating context the agent may draw on — which lets operational knowledge move across compatible harnesses and accumulate across tasks.
Each skill is organized in three layers, S=(SKILL.md,references/,scripts/), and each layer does a different job. SKILL.md is the knowledge interface — the only layer read up front. It states what the agent must know to use the skill, carries the standard operating procedure, and routes onward, packing goals, key concepts, tool usage, worked examples, and known failure modes into a summary. references/ is the knowledge substrate: the deeper API docs, algorithmic detail, and parameter configurations that SKILL.md points to and that load only when needed — the principle of progressive disclosure. scripts/ is the execution interface: executable wrappers with defined inputs and outputs the agent invokes rather than reimplements. The mapping to the two constituents is exact: scripts/ and references/ turn knowledge into capability, while SKILL.md turns capability into usage policy — and keeps the cost of holding a skill low enough that an agent can carry thousands of them.
One source usually contains more knowledge than a single skill should hold, so the skills distilled from one source are organized as a skill graph G=(S,L). The graph has an entry skill that states the source's scope and routes to component skills for package functions, method stages, or protocol elements; each link encodes a routing, dependency, or composition relation. Progressive disclosure operates over this graph: the agent reads the entry point, follows the links its problem calls for, and leaves the rest unopened, so K at any moment holds only the part of the graph the task actually needs.
Key Points
- 1
K is instantiated as a set of skills K={S1,…,Sm} — so producing operational knowledge reduces to producing skills
- 2
Adding a skill requires no change to Mθ or H; it becomes operating context that ports across compatible harnesses and accumulates across tasks
- 3
Each skill has three layers: S=(SKILL.md,references/,scripts/) — knowledge interface, knowledge substrate, execution interface
- 4
SKILL.md is the only layer read up front: goals, key concepts, tool usage, worked examples, failure modes, and routes to deeper material
- 5
references/ (API docs, algorithmic detail, configs) and scripts/ (executable wrappers) load only on demand — the progressive disclosure principle
- 6
A source's skills form a graph G=(S,L) with an entry skill and links encoding routing, dependency, or composition relations
- 7
Progressive disclosure over the graph means K holds only the branch the task needs — an agent can carry thousands of skills yet read only a few
Mathematical Formulation
Operating Context as a Skill Set
K={S1,…,Sm}
The operating context is a set of skills held at a given moment. Producing operational knowledge becomes the concrete problem of producing and selecting the right skills.
The Three-Layer Skill
S=(SKILL.md,references/,scripts/)
SKILL.md is the knowledge interface read up front; references/ is the knowledge substrate loaded on demand; scripts/ is the execution interface. The first turns capability into usage policy; the latter two turn knowledge into capability.
The Skill Graph
G=(S,L),S={Si}i=1n,n≥1,L⊆{(Si,Sj)∈S×S∣i=j}
A source is distilled into a graph of skills S connected by links L. Each link is a routing, dependency, or composition relation; L may be empty when a source yields a single skill or several independent ones.
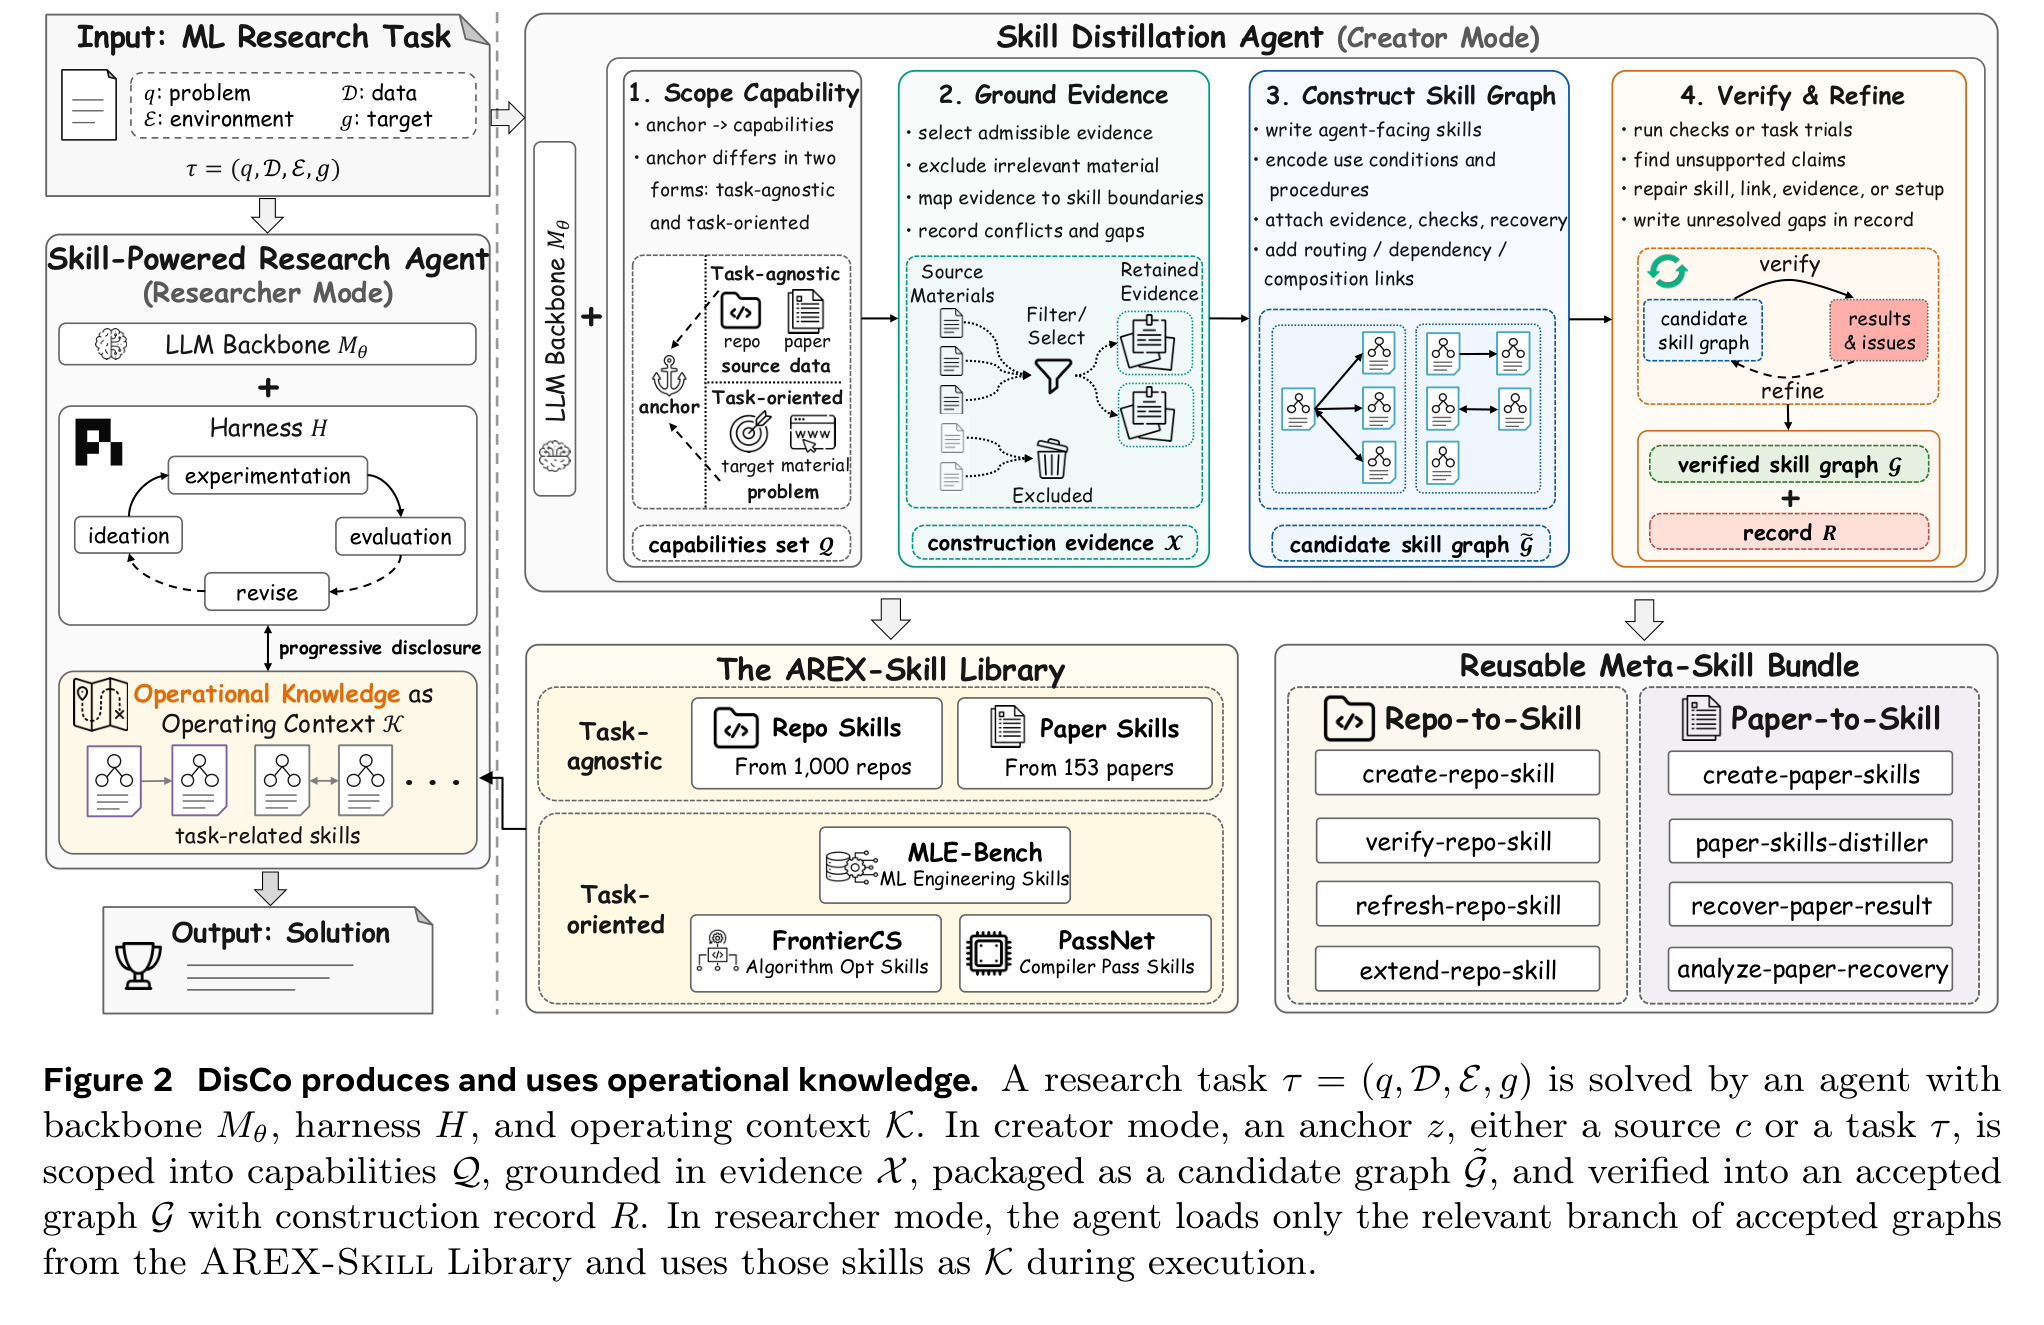
Producing those graphs automatically is what the paper calls skill distillation — reworking declarative source knowledge into operational knowledge that directly supports solving tasks. Every run, regardless of what triggers it, follows the same four stages. Writing z for the anchor that initiates the run, the process is z→Q→X→G~→(G,R): scope the capabilities Q worth covering, ground them in evidence X drawn from the source, construct a candidate graph G~ in the three skill layers, and verify it into an accepted graph G that ships with a construction record R retaining the evidence used, the checks performed, and any unresolved gaps. The four stages answer four questions in turn: which capabilities matter, what supports them, how they become skills, and whether those skills hold.
The two forms of distillation differ only in the anchor, and that choice determines source selection and the verification signal. Task-agnostic distillation takes a source as the anchor (z=c) — a repository, paper, or tutorial — and asks what the source makes possible, packaging the answer into long-lived skills built ahead of time for any task that later needs them. For a repository, scoping runs Source Understanding then Capability Identification; grounding is Knowledge Extraction from the source itself; construction wraps executable parts behind stable interfaces and assembles the three layers into a connected graph.
Task-oriented distillation takes a problem as the anchor (z=τ) and searches for material rather than being handed it. It asks what solving the task demands: scoping is Task Decomposition then Capability Gap Analysis (isolating what the agent cannot already supply), grounding is Source Discovery (so X is assembled, not selected), and construction is Skill Generation. Optimizing an open-ended algorithmic problem or entering a Kaggle competition are tasks of this kind — the skills are produced on demand yet remain reusable for the class of problems they address.
Whichever anchor initiates the run, verification is what separates distillation from summarization. No skill is admitted on the strength of its sources alone: each candidate is checked with assertion-backed cases and safe, repository-native examples, tests, CLI checks, tiny-fixture checks, or smoke scripts when available. A failure attributed to the graph triggers local repair and reruns of the relevant checks, and any gap that survives is recorded in R rather than hidden.
Key Points
- 1
Every distillation run — whatever triggers it — follows one four-stage loop: z→Q→X→G~→(G,R)
- 2
Scope picks capabilities Q; ground gathers evidence X; construct assembles a candidate graph G~; verify yields an accepted graph G with a construction record R
- 3
Task-agnostic distillation anchors on a source z=c (repo, paper, tutorial) and asks what it makes possible — long-lived skills built ahead of time
- 4
Task-oriented distillation anchors on a problem z=τ and asks what solving it demands — evidence is discovered and assembled, not handed over
- 5
The record R retains the evidence used, checks performed, and unresolved gaps — skills carry their own provenance and known limits
- 6
Verification separates distillation from summarization: candidates are checked with assertion-backed cases, repo-native tests, CLI checks, tiny-fixture checks, or smoke scripts
- 7
A failure attributed to the graph triggers local repair and reruns; surviving gaps are recorded, never hidden
Mathematical Formulation
The Four-Stage Distillation Pipeline
zscopeQgroundXconstructG~verify(G,R)
From an anchor z, scoping decides the capabilities Q, grounding gathers supporting evidence X, construction assembles the candidate graph in the three skill layers, and verification produces the accepted graph plus a construction record R.
The Two Anchors
task-agnostic: z=c∈Ctask-oriented: z=τ
Task-agnostic runs anchor on a source c drawn from the available material C and build reusable skills ahead of time. Task-oriented runs anchor on a problem and search for the material a specific task needs. The anchor is the only structural difference between the two forms.
The framework has two halves — a layer that must be produced and a layer that must be used — and they meet in a single agent. DisCo operates in two modes over the same backbone and harness. In creator mode it carries out distillation: it scopes, grounds, constructs, and verifies, then deposits the accepted graph G into the AREX-Skill Library. In researcher mode it is the agent Ares=(Mθ,H,K), solving a task with K drawn from that library. The library is the seam between the two: creator mode writes accepted graphs, researcher mode retrieves them.
The two modes are deliberately asymmetric in cost, and that asymmetry is what makes the layer scalable. Creator mode is paid once per source and amortized over every task that later draws on the result; researcher mode pays only for what a task actually opens. Distillation can therefore run offline at whatever breadth the source ecosystem allows, while the agent solving a task inherits the result without re-deriving it.
Inside researcher mode the remaining question is how a graph is consumed, and the answer is again progressive disclosure. Rather than reading a full graph, the agent first sees a router or entry skill that summarizes candidate graphs by scope and intended use; it chooses an entry point and opens only the skills it needs during execution. The links then extend that selection beyond the first skill — an entry skill can route to component skills for setup, evaluation, diagnosis, or repair — so the agent moves from an opened skill to a referenced one only when the task calls for it, never reading unrelated parts of the graph.
The design point the authors stress is that this adds operating context rather than a new control loop. A skill graph is not a new way of running an agent, which keeps the knowledge layer separate from harness design: the same distilled skills can serve any compatible harness that exposes agent-readable skills, while each harness keeps its own planning policy, tool interface, and execution loop.
Key Points
- 1
DisCo is one agent in two modes over the same Mθ and H: creator (distills and deposits graphs) and researcher (solves tasks with K from the library)
- 2
The AREX-Skill Library is the seam: creator mode writes accepted graphs, researcher mode retrieves a task-relevant branch
- 3
The modes are asymmetric in cost: creator is paid once per source and amortized; researcher pays only for what a task opens
- 4
This asymmetry is what makes the layer scalable — distillation runs offline at ecosystem breadth, and task-solving inherits the result without re-deriving it
- 5
Consumption is progressive disclosure: the agent reads a router/entry skill, opens only what it needs, and follows links to setup, evaluation, diagnosis, or repair skills on demand
- 6
The interface adds operating context, not a new control loop — the same skills serve any compatible harness, which keeps the knowledge layer independent of harness design
Mathematical Formulation
The Two Modes over One Agent
creator modec→(G,R)⟶researcher modeAres=(Mθ,H,K)
Creator mode maps a source to an accepted graph and its record, deposited in the library. Researcher mode is the research agent drawing K from that library. The same backbone and harness serve both; only the mode changes.
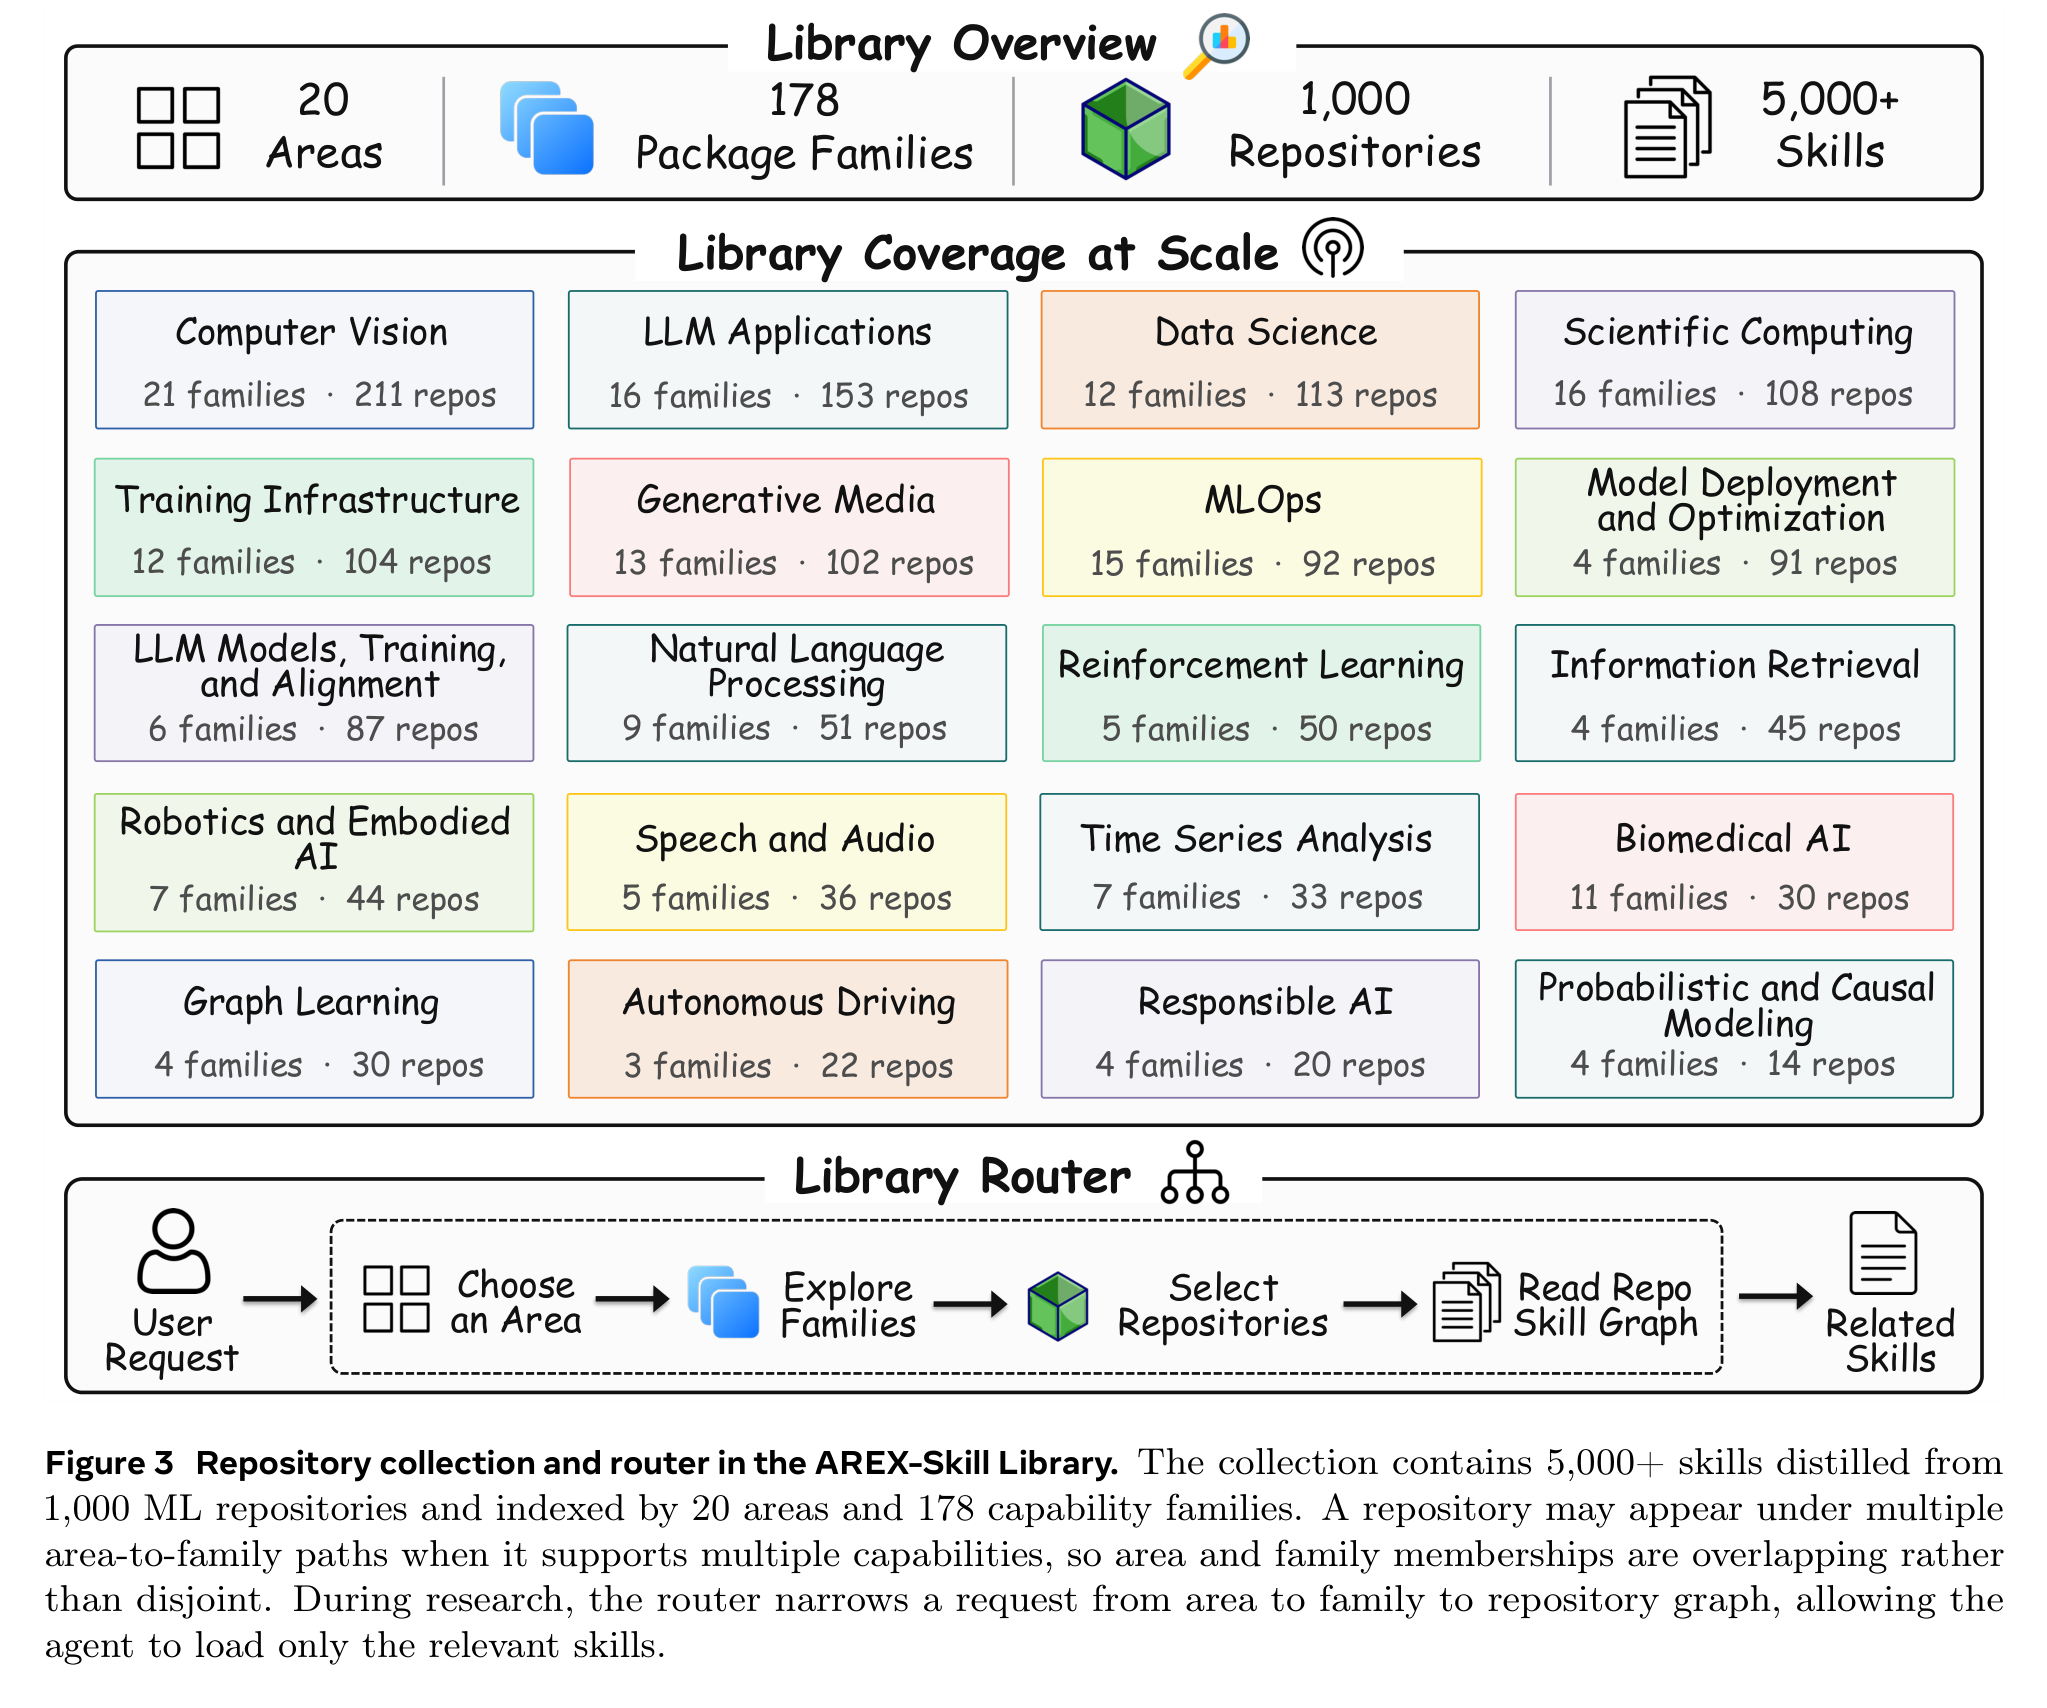
Scaling DisCo's creator mode across the open ecosystem yields the AREX-Skill Library, the persistent operational-knowledge store the researcher mode draws on. The public repository snapshot covers 1,000 ML repositories, selected on open-source visibility and practical use (with GitHub stars among the curation signals), spanning model implementations, training and deployment systems, data and evaluation tools, and scientific software. For each repository DisCo constructs a verified skill graph using the task-agnostic procedure, at an average allocation of about $40 per repository with GPT-5.5 and GPT-5.6-sol at xhigh reasoning effort. The evidence boundary is the repository itself: source, docs, examples, tests, scripts, and configuration.
The resulting snapshot contains 5,353 skills across 1,000 repository graphs, organized into 20 areas and 178 capability families. It records 2,209 exact assignments of repositories to area-to-family paths, with 700 repositories appearing in more than one family — area and family memberships are overlapping, not disjoint, because a repository can support several capabilities. The largest areas are Computer Vision (21 families, 211 repos), LLM Applications (16 / 153), Data Science (12 / 113), and Scientific Computing (16 / 108).
A generated router exposes the taxonomy before any graph is opened. The taxonomy is fixed before final assignment: a short summary is frozen for each source (stars, URLs, and pre-existing category fields are excluded from the model input) and a two-level tree of areas and families is induced, evaluated on stable batches with separate locator and judge calls, and revised. Only then is each verified graph classified against exact area-to-family paths, with keyword-only, dependency-only, optional-integration, and example-only matches rejected. During research the agent starts from the router description, follows the relevant area-to-family path, opens the selected repository graph, and loads only the skills, references, or scripts the current step needs — progressive disclosure again, now at library scale.
The repository snapshot is not the whole library. Paper-derived skills form a second task-agnostic collection — 636 skills from 153 source papers for the current study — and task-oriented graphs are built for individual benchmarks (one descriptive graph per MLE-bench competition, one recovery-oriented graph shared across FrontierCS, one benchmark-level graph for PassNet).
Key Points
- 1
1,000 ML repositories selected on open-source visibility and practical use, spanning models, training/deployment systems, data/evaluation tools, and scientific software
- 2
Each repository is distilled at ~$40 with GPT-5.5 and GPT-5.6-sol (xhigh reasoning); the evidence boundary is the repo's source, docs, examples, tests, scripts, and config
- 3
The snapshot holds 5,353 skills across 1,000 graphs, organized into 20 areas and 178 capability families
- 4
2,209 area-to-family assignments with 700 repos in more than one family — memberships overlap because a repo can support several capabilities
- 5
A generated router narrows a request area → family → repository graph; the taxonomy is fixed before assignment, with stars/URLs excluded from the model input
- 6
Classification rejects weak matches — keyword-only, dependency-only, optional-integration, and example-only assignments are not accepted
- 7
Beyond repositories: 636 paper-derived skills from 153 papers, plus task-oriented graphs per benchmark (MLE-bench, FrontierCS, PassNet)
Mathematical Formulation
Library Coverage at Scale
repositories1,000⟶skills5,353routed overareas20×capability families178
One thousand repository graphs yield 5,353 verified skills, indexed by a two-level taxonomy of 20 areas and 178 capability families. The router uses this index to load only the branch a task needs.
The evaluation is built as a controlled ablation. The harness is Codex, the backbone is GPT-5.5 at xhigh reasoning, and the downstream execution budget is fixed; the only variable is whether the agent is equipped with DisCo-distilled skills. Skill construction is completed before downstream execution begins and uses a separate budget, so at run time the skills are the only thing that changes.
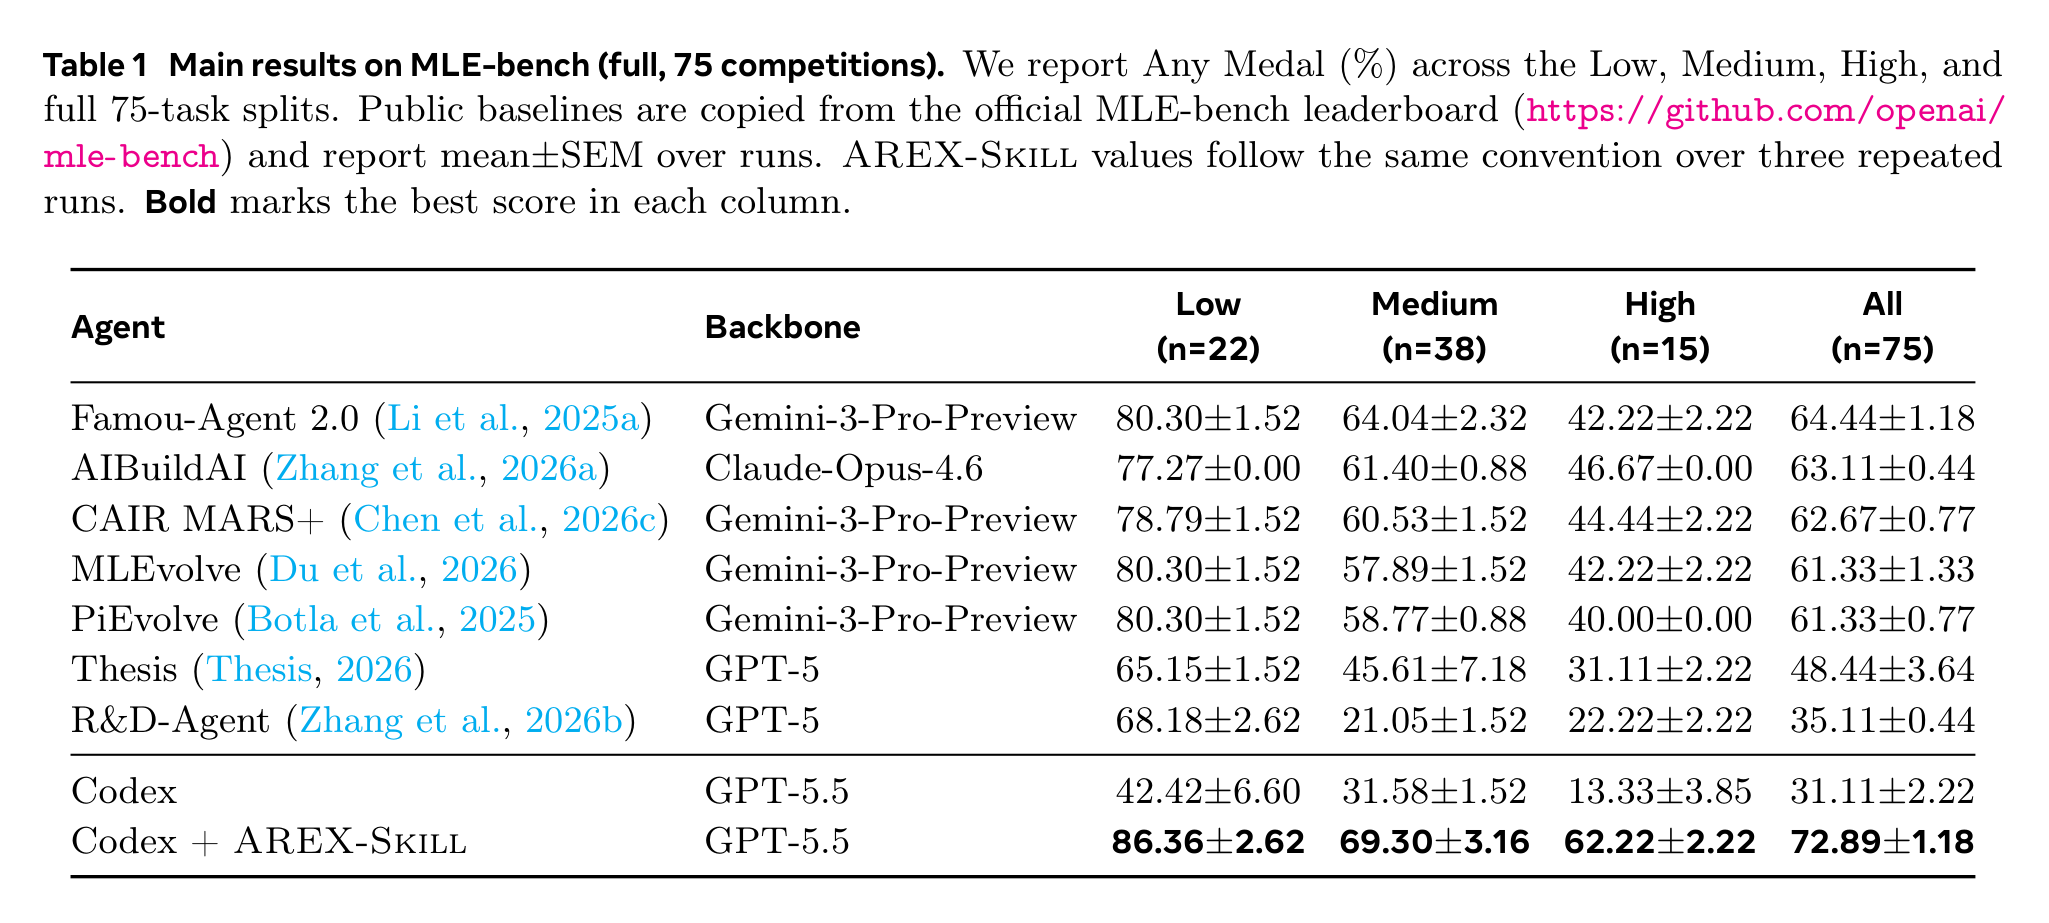
On MLE-bench (full, 75 competitions) skills raise Codex's Any-Medal score from 31.11% to 72.89% — a 41.78-point absolute gain and the headline 134.3% relative improvement — without changing the backbone. The gains hold across every difficulty tier (Low 42.42 → 86.36, Medium 31.58 → 69.30, High 13.33 → 62.22) and are sharpest on the hardest tasks, where the score rises 366.8% relative, or 4.67x the no-skill score. Skill-equipped Codex also surpasses the strongest public baseline, Famou-Agent 2.0 at 64.44%, using vanilla Codex with no custom harness.
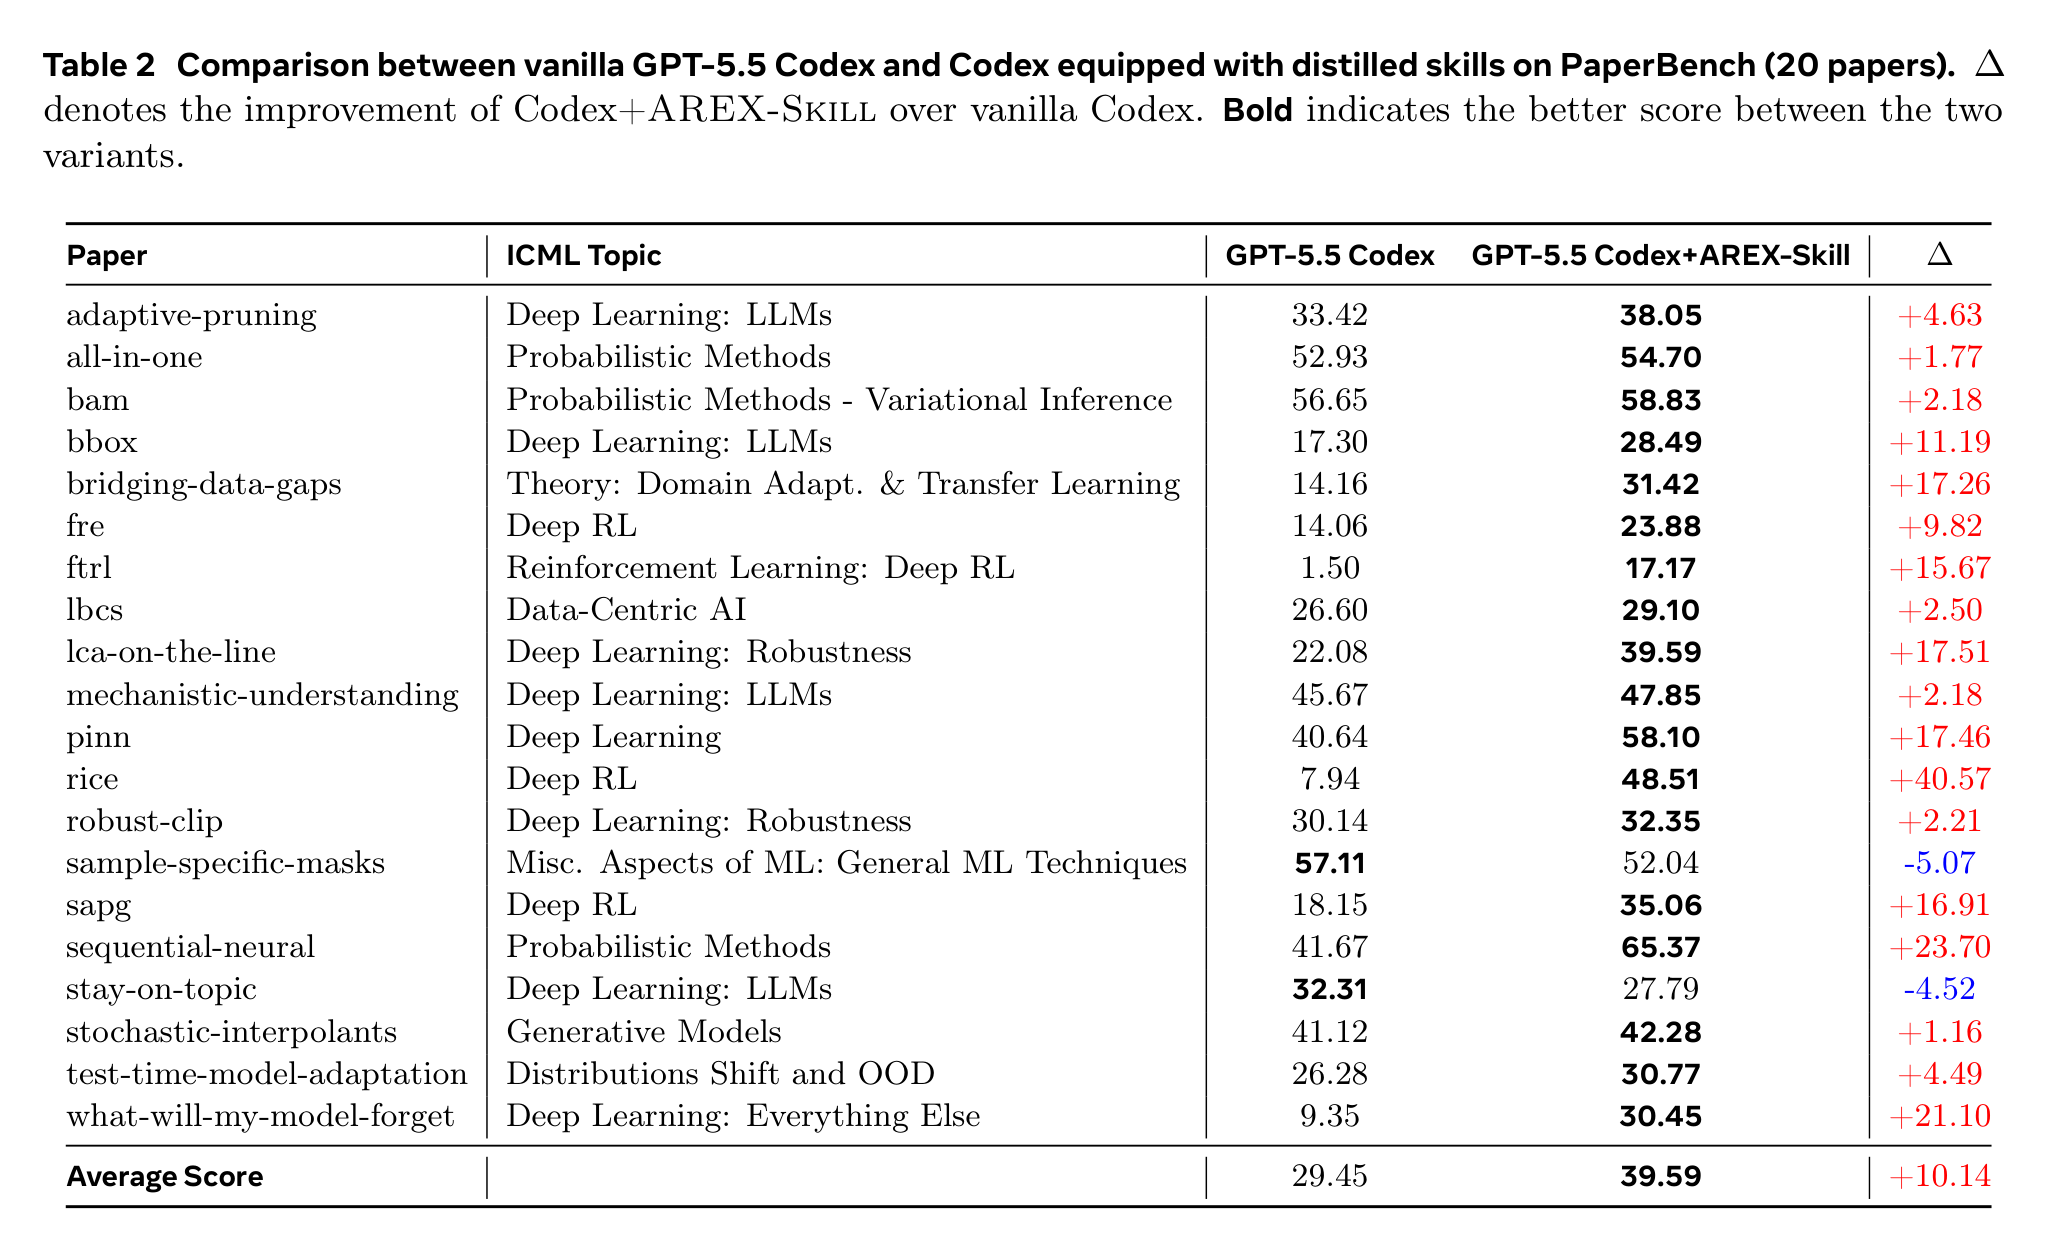
On PaperBench (20 papers) the average replication score climbs from 29.45% to 39.59% (+10.14 points, a 34.4% relative improvement), improving 18 of 20 tasks. The largest lifts land on low-baseline tasks: rice 7.94 → 48.51 (a 6.1x increase), sequential-neural +23.70, and ftrl 1.50 → 17.17 (an 11.4x increase). On FrontierCS (188 Agent Track tasks) the aggregate Score rises from 70.63 to 77.14 (+6.51, +9.22%), improving 74 tasks and leaving 66 unchanged, with a 95% bootstrap interval of [3.41, 9.83] points.
On PassNet (graph-compiler pass generation) the AS Score rises from 1.343 to 1.5313 (+0.1883, a 14.0% relative improvement) and the geometric-mean speedup from 1.5891 to 1.6688. Correctness climbs from 81.35% to 90.76%, failed samples drop from 14 to 5 (a 64.3% reduction), and skill-equipped Codex edges past TorchInductor's 1.419 on aggregate score. Across all four benchmarks the story is the same: distilled operating context, added under a fixed backbone, harness, and budget, is what moves the needle.
Key Points
- 1
Clean ablation: Codex harness, GPT-5.5 backbone, fixed budget — the only variable is the presence of DisCo-distilled skills, constructed on a separate budget before run time
- 2
MLE-bench (75 comps): 31.11% → 72.89% Any-Medal — +41.78 points, the +134.3% headline; also beats the best public baseline (Famou-Agent 2.0, 64.44%)
- 3
Gains hold across tiers (High: 13.33 → 62.22, a 366.8% relative jump) — the advantage grows with task difficulty
- 4
PaperBench (20 papers): 29.45% → 39.59% (+10.14, +34.4%), improving 18 of 20; biggest lifts on low-baseline tasks (rice 7.94 → 48.51, ftrl 1.50 → 17.17)
- 5
FrontierCS (188 tasks): 70.63 → 77.14 (+6.51, +9.22%), 74 improved / 66 unchanged, bootstrap CI [3.41, 9.83]
- 6
PassNet: AS Score 1.343 → 1.5313 (+14.0%), correctness 81.35% → 90.76%, failed samples 14 → 5 (64.3% fewer), past TorchInductor's 1.419
- 7
Every gain comes from adding operating context, not a stronger model or a new control loop
Mathematical Formulation
The MLE-bench Headline
31.1172.89−31.11≈1.343=+134.3%
The relative improvement on MLE-bench Any-Medal: from 31.11% without skills to 72.89% with them, a 41.78-point absolute gain, under a matched backbone, harness, and execution budget.
Further Reading
The aggregate numbers are strong, but the paper is careful about where the gains come from, and the structure is consistent across all four benchmarks: skills help most exactly where unguided exploration is most likely to stall.
The clearest pattern is that the advantage grows with task difficulty and low baselines. On MLE-bench the largest absolute gain is on High-difficulty tasks (+48.89 points over no-skill Codex). On PaperBench the biggest relative lifts land on tasks where the no-skill baseline is near the floor — ftrl at an 11.4x increase, rice at 6.1x — while tasks that already scored moderately, like all-in-one (52.93) and bam (56.65), gain only +1.77 and +2.18. On FrontierCS, stratifying by no-skill score, the largest lift is on the 47 tasks scoring below 50, whose mean rises from 19.43 to 45.99, with 30 of them crossing the 50-point threshold. Harder tasks expose the agent to a larger space of libraries and implementation choices, so unguided trial and error costs more — and guidance is worth more.
Just as important, the gains are not bought with extra compute. On FrontierCS skills do lead to more active search (more tokens, steps, and tool calls), but per-task gains are essentially uncorrelated with the extra usage: Spearman's rho is 0.006 for tokens, 0.014 for steps, 0.015 for tool calls. Skill-equipped Codex uses 4.47M tokens per task against Claude Code's 14.72M and 13.85M while scoring higher — a strictly better score-efficiency frontier, Pareto-dominating both on score, tokens, steps, and tool calls.
The honest part is the regressions. On PaperBench two of twenty tasks score lower with skills — sample-specific-masks (57.11 → 52.04) and stay-on-topic (32.31 → 27.79) — and both had above-average no-skill scores, which points to a retrieval-precision failure: when replication hinges on a narrow, idiosyncratic implementation choice the constructed graph does not cover well, following a retrieved skill can pull the agent away from an approach it would have found unaided. The authors frame this as a modest precision-recall trade-off in skill retrieval, fixable with better routing or an explicit fallback to unguided reasoning when the retrieved skills are a poor match.
Key Points
- 1
The advantage grows with difficulty: MLE-bench High tasks gain +48.89 points; FrontierCS tasks below 50 rise from a 19.43 to 45.99 mean, 30 crossing the 50 threshold
- 2
The largest relative lifts land on low-baseline tasks (PaperBench ftrl 11.4x, rice 6.1x), while already-moderate tasks gain little (all-in-one +1.77, bam +2.18)
- 3
Gains are not explained by extra compute: on FrontierCS Spearman's ρ is 0.006 (tokens), 0.014 (steps), 0.015 (tool calls) — essentially uncorrelated with per-task gain
- 4
A better score-efficiency frontier: 4.47M tokens/task vs Claude Code's 14.72M and 13.85M, at a higher score — Pareto-dominant on score, tokens, steps, and tool calls
- 5
The honest caveat: 2 of 20 PaperBench tasks regress (sample-specific-masks 57.11 → 52.04, stay-on-topic 32.31 → 27.79), both above the no-skill average
- 6
Likely cause is retrieval-precision failure — retrieved skills distract from a narrow, idiosyncratic strategy the base agent would otherwise discover
- 7
Suggested fix: better routing or an explicit fallback to unguided reasoning when retrieved skills are a poor match
Keep reading
Related Papers
Go deeper