UrbanGround
From Local Perception to Spatial Agency in a Real-Scale City
Tianjie Ju, Zheng Wu, Yueqing Sun, Yuhan Cui, Bobo Li, Shengqiong Wu,
7
Concepts
2
Formulas
5
Figures
5
Demos
Paper Overview
UrbanGround (Ju, Wu, Sun et al. — Shanghai Jiao Tong University, National University of Singapore, Meituan, and collaborators, August 2026) takes a capability everyone already agrees MLLMs have — reading a street view — and asks the question that actually matters for a city: does that reading survive the next step the agent takes?
A multimodal model can name the storefront in front of it. But an urban agent does not receive its observations as a photo album; it receives them through a continuing physical process where every movement produces the next first-person view. Turn a corner and the landmark that justified your last decision vanishes, even though its location still matters. Strong recognition at one viewpoint therefore tells you almost nothing about whether spatial understanding stays coherent through continued action.
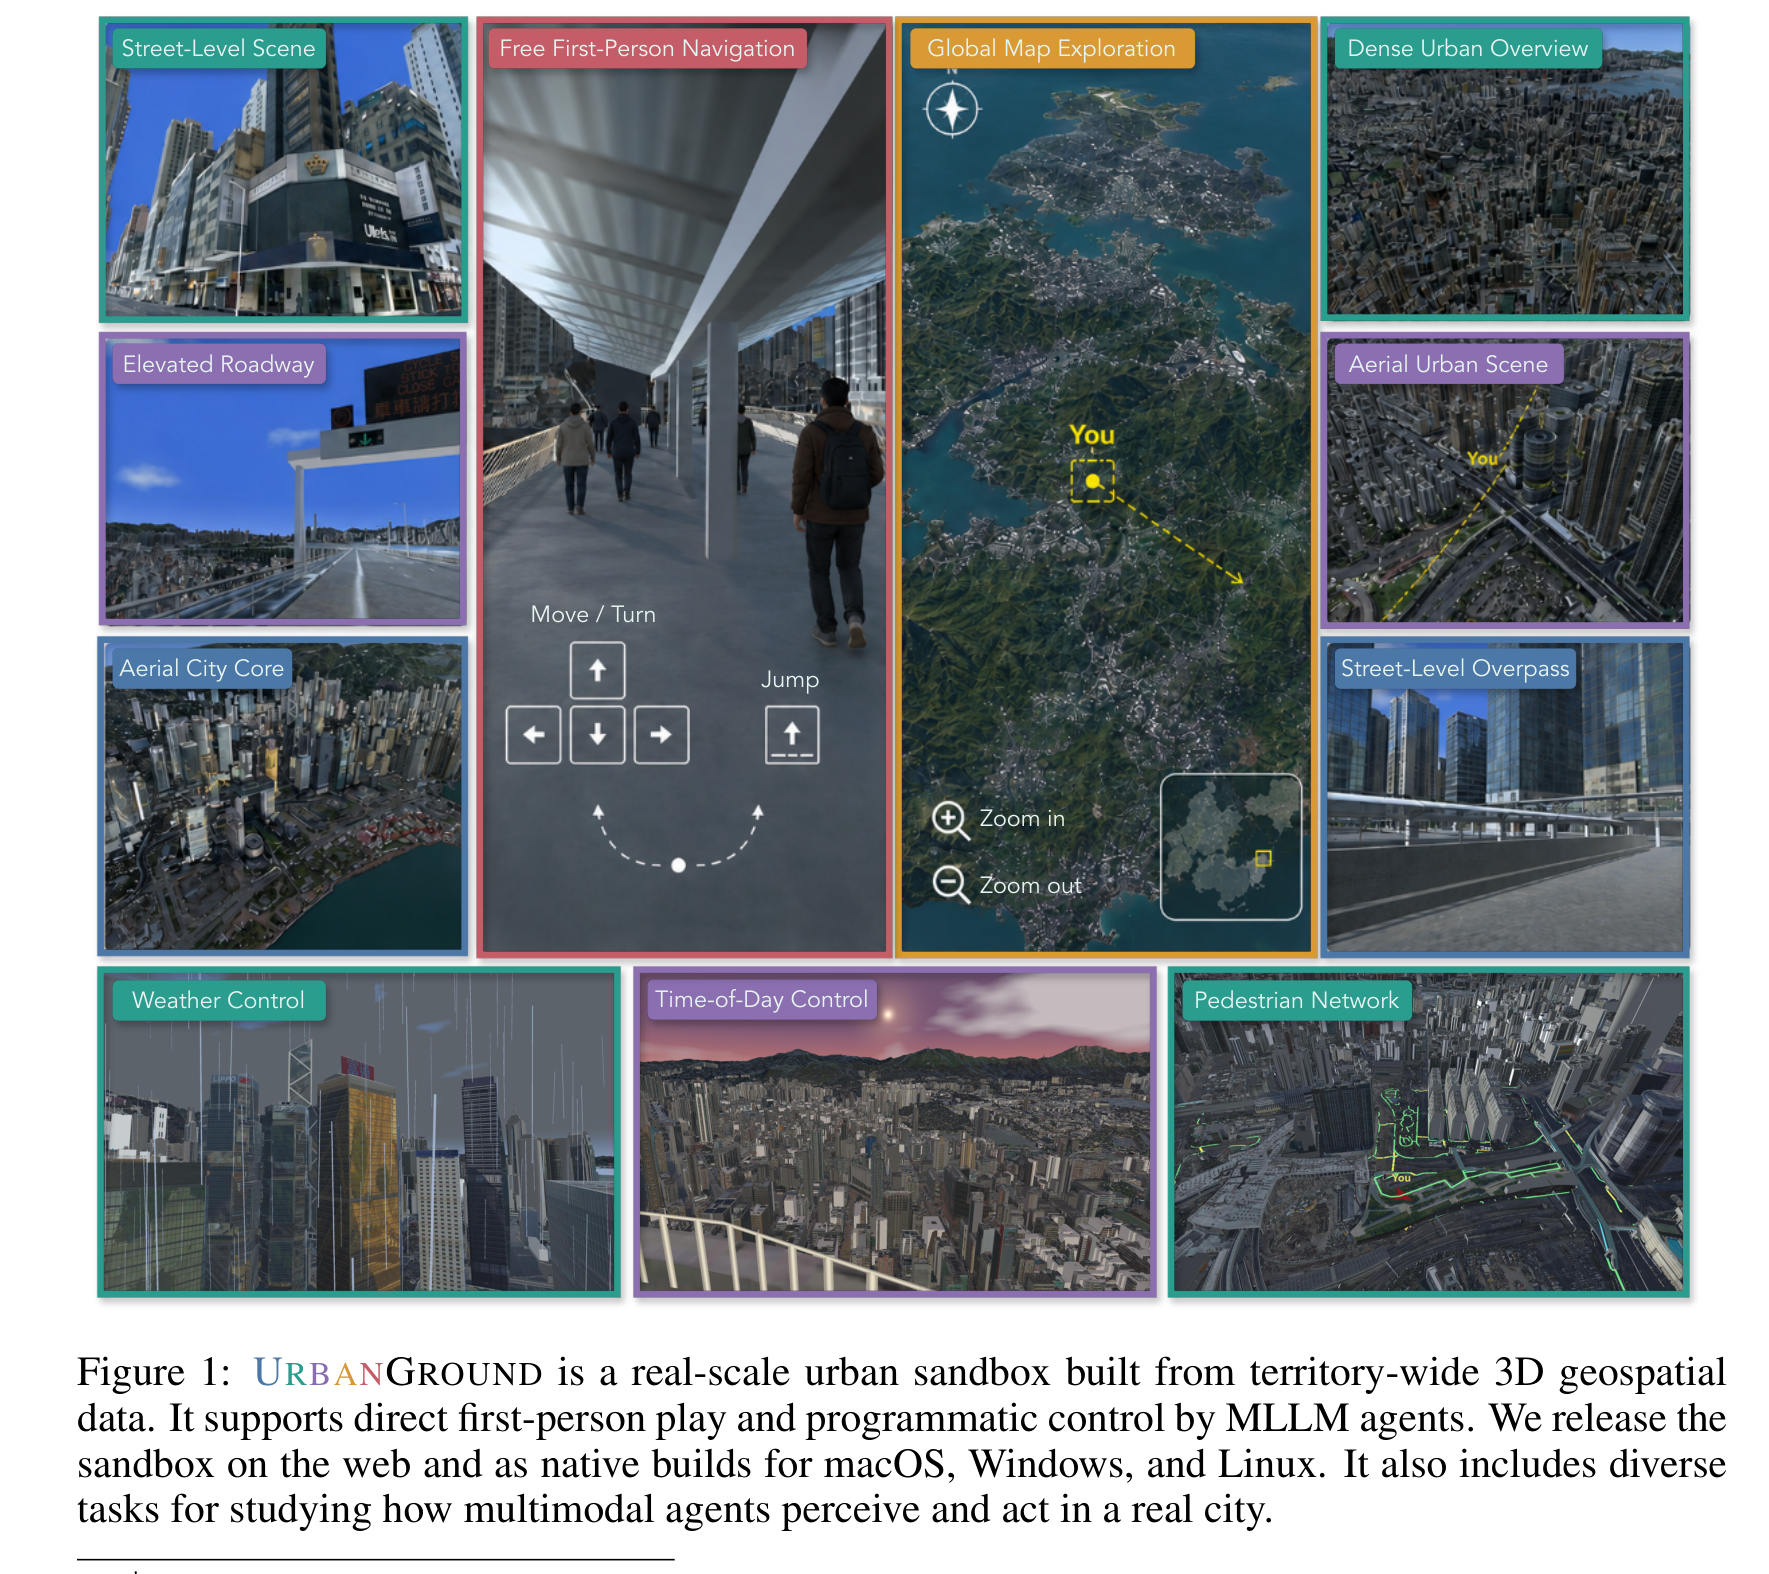
The paper makes this testable by building the first sandbox for it: a physically constrained, georegistered replica of Hong Kong, streamed from the Lands Department's territory-wide 3D geospatial data into Unity, with real collision geometry, a controllable clock and weather, and animated pedestrian crowds. Agents enter from a first-person view, act through a structured interface, and their trajectories are recorded in geographic coordinates.
The evaluation follows the spatial problem as it grows — from grounding a local scene (RQ1), to holding a goal across a route (RQ2), to adapting when the city itself changes (RQ3). The finding is consistent and sobering: contemporary agents (GPT-5.5, Claude-Opus-5, Gemini-3.6-Flash, Kimi-K3 and others) have useful atomic skills, yet navigation collapses once a route spans a few city blocks — best short-range success reaches 81.3% while long-range success sits near 0% — because local competence never composes into sustained, self-correcting behavior.
Chapter Roadmap
Click any topic to jump in
The Spatial Agency Problem
An MLLM can read a street view — but does that local evidence stay useful once the agent starts to move and the landmark leaves the frame?
Closed-Loop Urban Interaction
Grounding, persistence, adaptation — three cumulative capabilities, formalized as a hidden-state loop the model never observes directly.
A Real-Scale Hong Kong
Territory-wide 3D tiles and a georeferenced pedestrian graph streamed into Unity, with physical collision, time-of-day, weather, and animated crowds.
Perception & Action Interface
First-person RGB plus an interactive map in; one structured action per turn out. No shortest path, no remaining distance, no route API.
The Spatial Agency Ladder
810 verified tasks across five levels that raise the spatial state required for success while holding the interface fixed.
Findings and the central gap
What Agents Can and Cannot Do
Strong local recognition, weak orientation, and navigation that collapses past a few blocks — the same separation recurs at every scale.
The Compositionality Gap
Local abilities do not compose into sustained goal-directed behavior; errors accumulate without effective correction.
Concept by concept
7 sections, in reading order.
The paper opens with a distinction that is easy to miss and organizes everything after it: the difference between perceiving a place and acting within it. Recent MLLM agents recognize urban objects from individual observations extremely well. But an agent does not stand still and describe photographs — it is embedded in a physical loop where each action it takes changes the very evidence it will see next.
That loop is what breaks the naive assumption. Once the agent turns a corner, a landmark that supported its last decision may disappear even though its location still matters. The earlier evidence then has to be reconciled with the new view so the agent keeps a usable estimate of where it is. A model can be excellent at the single-frame task and still lose its spatial account the moment the frame moves — so strong recognition at one viewpoint does not demonstrate that spatial understanding will remain coherent through continued action.
UrbanGround decomposes spatial agency into three cumulative capabilities, and the ordering is the whole thesis. Grounding forms task-relevant local relations from locally acquired observations — the atomic skill. Persistence keeps those relations usable after the earlier evidence has left the first-person view, and for global tasks additionally requires aligning map context with the geometry met on the ground. Adaptation concerns whether the state stays reliable when external conditions alter the visible evidence — when new evidence invalidates an earlier assumption, adaptation demands a corresponding revision of the working state.
Each capability presupposes the one before it, which is why the paper can locate exactly where an agent fails rather than only that it failed. RQ1 primarily probes grounding; RQ2 retains grounding while stressing persistence over a route; RQ3 presupposes both and examines robustness when the city changes. Prior settings could not expose this staircase: game sandboxes tie success to game-specific mechanics, bounded indoor benchmarks rarely require an account to stay useful beyond a local area, and street-view or aerial urban studies move the agent between sampled viewpoints without continuous physical contact with the same city.
Key Points
- 1
The core reframing: an urban agent receives observations through a continuing physical process where each movement produces the next first-person view — not as independent images
- 2
Strong single-viewpoint recognition does not imply coherent spatial understanding through action — once the agent moves, the supporting landmark can leave the frame while its location still matters
- 3
Spatial agency is defined as three cumulative capabilities: Grounding (local relations from local observation), Persistence (relations stay usable after evidence leaves view), Adaptation (state stays reliable when the scene changes)
- 4
The capabilities are strictly ordered — persistence presupposes grounding, adaptation presupposes both — which is what lets the benchmark pinpoint where an agent breaks
- 5
RQ1 → grounding, RQ2 → persistence, RQ3 → adaptation — the three research questions map one-to-one onto the capability ladder
- 6
Existing environments each miss part of the transition: game worlds impose game-specific mechanics, indoor benchmarks are spatially bounded, and street-view/aerial urban work lacks continuous physical contact with one real city
To make the three capabilities measurable, the paper writes the interaction down as a control loop — and the important design choice is what the agent is not allowed to see.
Let st be the hidden interaction state at turn t. It holds the georegistered agent pose, the current interface state, task progress, and city conditions. The evaluated model never reads st directly. What it receives is an observation bundle ot=O(st): the current first-person or map view plus any task-specific notice or status exposed that turn. From this the model maintains a working spatial state mt, chooses one structured action at=π(mt,g) toward objective g, and the simulator advances the world by st+1=T(st,at,ξt).
The variable mt is deliberately not a memory module. It is an analytical description of the task-relevant spatial information induced in the model's interaction context — the paper does not assume any explicit memory mechanism and does not observe mt either. This matters because it keeps the benchmark honest about what it is testing: whatever spatial account the model carries has to live in its ordinary context, not in privileged scaffolding.
The exogenous term ξt is where adaptation gets its teeth. For matched time-and-weather episodes the scene condition varies in the initial state s0 while ξt stays fixed; but ξt can also change during execution — a road-closure event or pedestrian motion — so an earlier plan can be invalidated mid-episode. Each non-terminal action updates the physical or interface state, which determines the next evidence ot+1, closing the loop.
The framework realizes this through three layers with a clean separation of concerns. The geospatial layer anchors the visible city and pedestrian connectivity in one geographic frame and records each trajectory in the same coordinates. The simulation layer implements the transition T through continuous physical motion with collision, and controls the changes represented by ξt. The agent layer exposes the observation function O plus the structured action interface. Keeping the geographic world and the embodiment fixed across every evaluated model is what makes cross-model comparison mean something.
Key Points
- 1
The interaction is a closed loop over a hidden state st the model never reads — it holds pose, interface state, task progress, and city conditions
- 2
The model sees only the observation bundle ot=O(st) and carries a working spatial state mt, which is an analytical description of context, not an assumed memory module
- 3
The interface exposes no privileged information — no remaining distance, no shortest path, no route API
- 4
The exogenous disturbance ξt is fixed for matched weather/time episodes but can change mid-episode (road closure, moving pedestrians), which is what stresses adaptation
- 5
Three layers separate concerns: geospatial (anchor + record in one frame), simulation (implements T and controls ξt), agent (exposes O + action interface)
- 6
Holding the geographic world and embodiment fixed across models is what makes cross-model comparison valid
Mathematical Formulation
The Closed Interaction Loop
ot=O(st),m0=U0(o0,g),mt=U(mt−1,ot,at−1,g),at=π(mt,g),st+1=T(st,at,ξt)
The model observes oₜ from the hidden state sₜ through O, updates its working spatial state mₜ from the previous state, the new observation, its last action, and the goal g, then acts via policy π. The simulator transition T folds in the exogenous disturbance ξₜ. The evaluator sees sₜ; the model never does.
The environment is what separates UrbanGround from generated or assembled urban simulators: it does not model a plausible city, it streams an existing one.
The geospatial layer is built on the 3D Digital Map released by the Hong Kong Lands Department, using two datasets. The 3D Visualisation Map is a tile-based textured mesh reconstructed from oblique aerial imagery covering the full territory, distributed through an open API as Cesium 3D Tiles under WGS84. The 3D Pedestrian Network is a set of georeferenced 3D line features derived from pedestrian road records. The former captures the visible form of the city; the latter describes how its pedestrian spaces connect — and Hong Kong is an unusually demanding choice, with dense development on steep terrain and a pedestrian network that repeatedly shifts between street level and elevated passages.
Unity loads the 3D Tiles hierarchy at runtime and transforms each tile's geographic coordinates into a shared simulation frame. Tiles stream by viewing scale, and the active geometry supplies both the rendered surface and the collision geometry used by the character controller — so the agent moves on the surface it actually sees and cannot cross a visible structure by editing its coordinates. The pedestrian network is imported into the same coordinate system as a connected graph, each vertex keeping its geographic position, each edge a walkable segment. Crucially it does not constrain the agent to graph edges: the agent moves freely in continuous space, and its trajectory is compared to the network after the fact — which is what makes off-network movement observable rather than impossible.
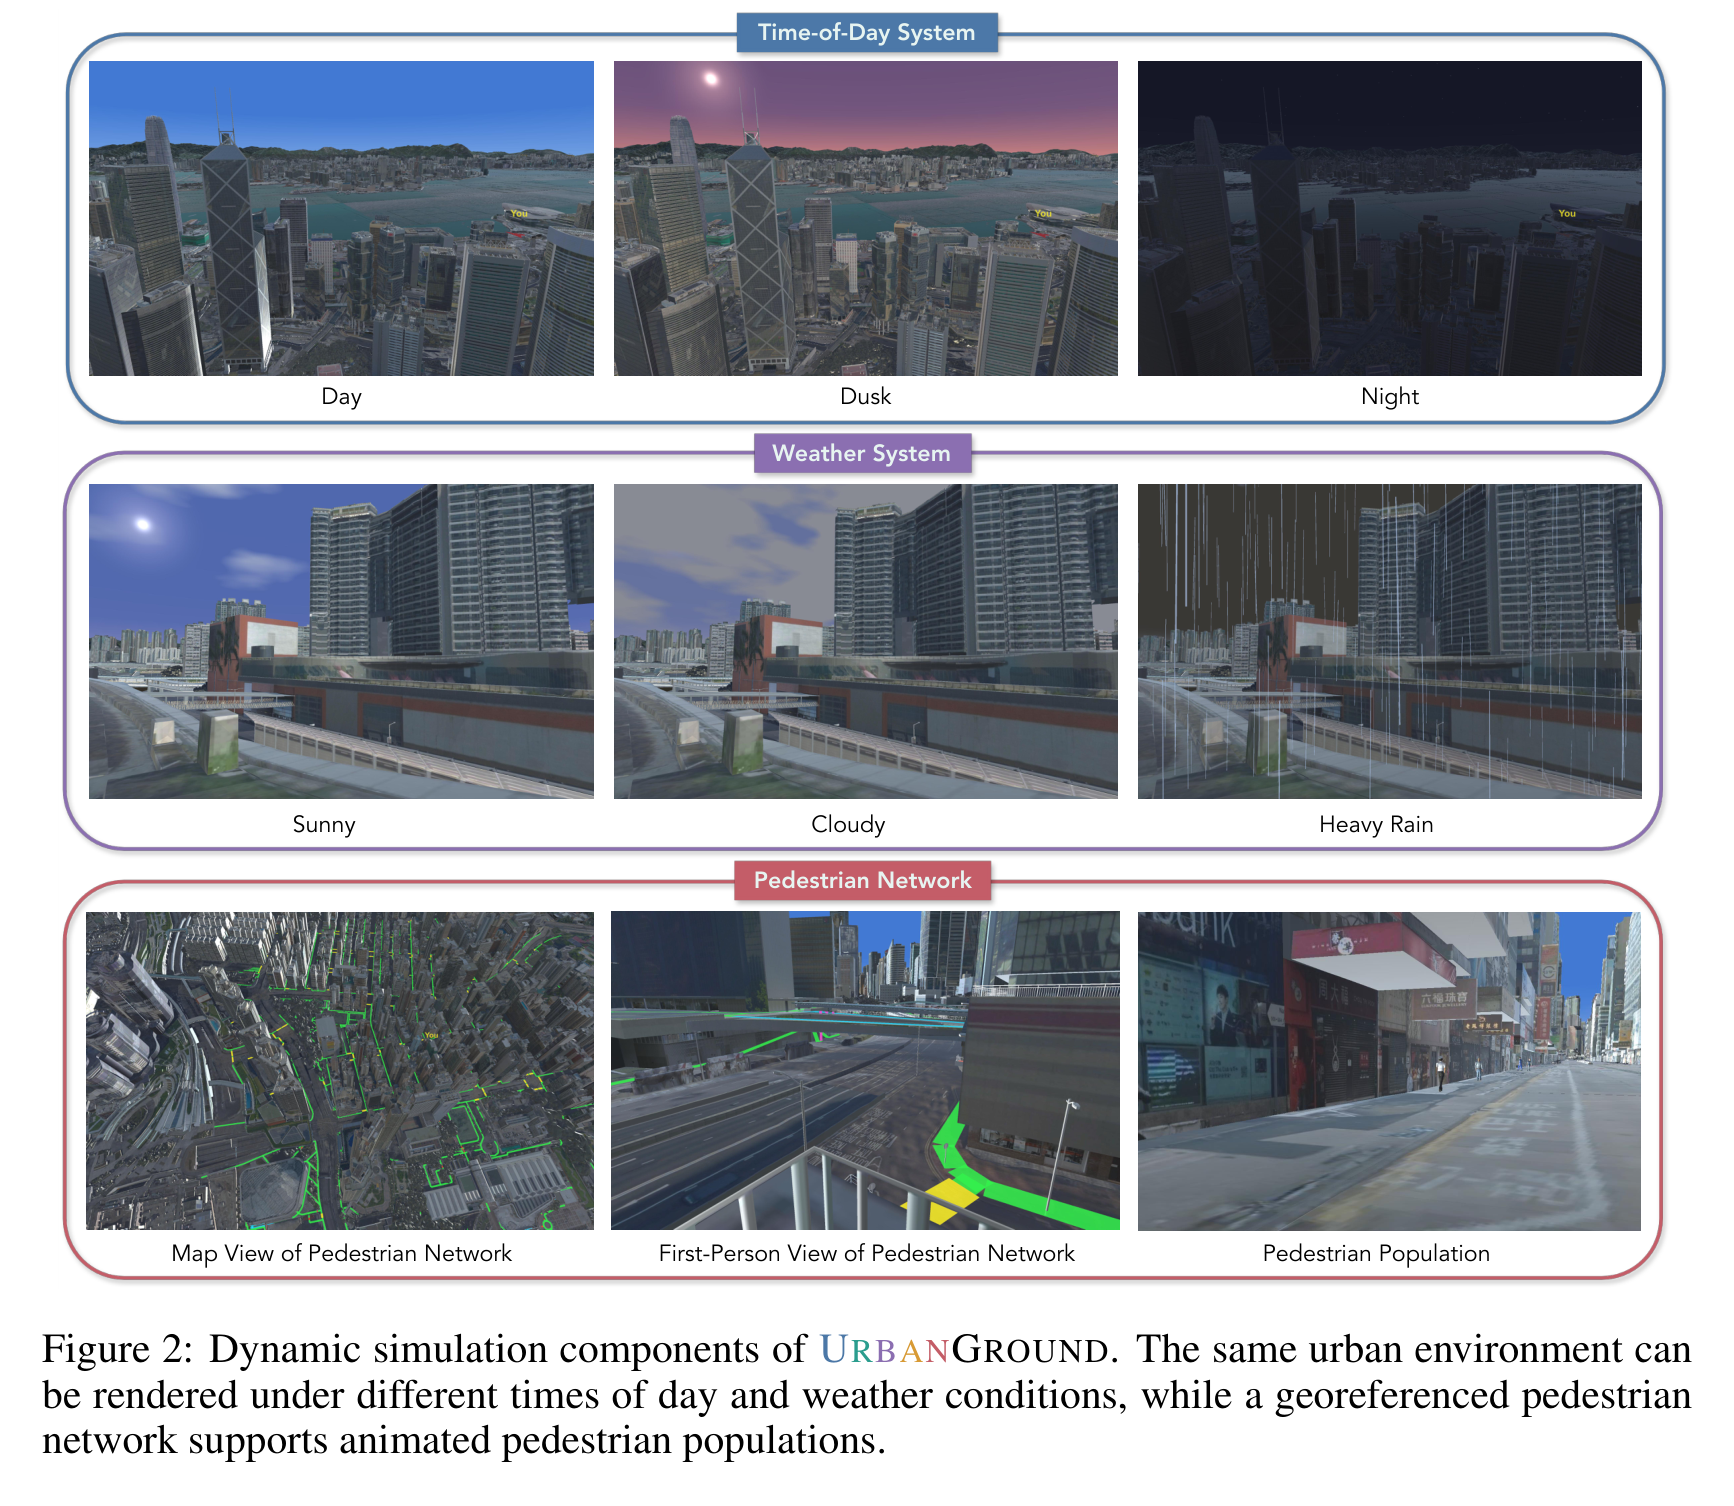
The simulation layer then makes the registered city a continuously evolving world. A continuous time-of-day clock drives the sky, sun, ambient light and shadows, with artificial lighting after dark; it can be pinned to an hour for controlled comparison or allowed to advance. The weather system adds rain and fog that alter visibility and rendering, and rain produces particles that interact with the scene — yielding an exposure signal that distinguishes covered paths from open streets, so route quality can depend on whether an agent picks shelter under rain. And the city is not empty: sidewalks are populated with animated pedestrians from the open-source Microsoft Rocketbox avatar library, spawned on the registered network and assigned routes over its edges, with positions and collisions recorded every step so navigation success can be weighed against trajectory safety.
Key Points
- 1
Built from the Hong Kong Lands Department 3D Digital Map — the 3D Visualisation Map (Cesium 3D Tiles, WGS84, textured mesh over the full territory) and the 3D Pedestrian Network (georeferenced 3D line features)
- 2
Hong Kong is chosen for difficulty: dense development on steep terrain with a pedestrian network that repeatedly shifts between street level and elevated passages
- 3
Active tile geometry serves as both rendered surface and collision geometry — the agent moves on what it sees and cannot phase through visible structures via coordinate updates
- 4
The pedestrian graph does not restrict the agent to edges — it moves in continuous space and the trajectory is compared to the network afterward, making off-network movement observable
- 5
Time-of-day: a continuous clock over sky, sun, light and shadow (with artificial lighting after dark); pinnable to an hour or free-running
- 6
Weather: rain and fog alter visibility; rain particles yield an exposure signal separating covered from open paths, so sheltered-route tasks become measurable
- 7
Pedestrians: animated avatars from the open-source Microsoft Rocketbox library, spawned on the network with per-step positions and collisions recorded
The agent layer connects an external MLLM to the running Unity world as a separate process over a client-server interface, so any model or agent framework can drive the same embodiment without touching the Unity implementation. That isolation is what keeps the embodiment identical across every evaluated system.
The primary observation is an RGB image rendered from the agent's first-person camera, presenting the real city from the pose the previous physical action produced. A bounded frame buffer may be carried in the observation context to provide visual history across consecutive decisions. For tasks needing global reasoning, an interactive map tool offers a georeferenced overhead view marking the agent's current location, which it can pan and zoom to inspect areas outside its first-person view — but the map does not expose a computed or highlighted route. The design principle throughout is that the interface reveals no privileged information: no remaining distance, no shortest path, no route API.
The action space is a strict one-per-turn selection from A=Afp∪Amap∪{terminate}. The first-person actions are Afp={move,sprint,look,jump,open map}; the map actions are Amap={map select,map pan,map zoom,map orbit,close map}. The move and sprint actions specify one of four movement directions and a duration, and may additionally carry yaw rate, pitch rate, jump, and jump-at fields — so the agent can adjust its view or jump within the same movement action. Because the direction field already covers lateral movement, strafe is not a separate action. The look action changes yaw and pitch without translating; jump is a standalone hop; the map actions open, close, select a point, and control the map view. The terminate action ends the episode.
An episode ends when the agent submits an answer, signals completion, or reaches 100 interaction steps. Since each movement action lasts at most two seconds, that budget permits up to 200 seconds of commanded motion — enough that model failures cannot be blamed on tasks being infeasible within the horizon. It is a small, honest interface: rich enough to move and look through a real city, deliberately stripped of anything that would do the spatial reasoning for the agent.
Key Points
- 1
The MLLM runs as a separate process over a client-server interface, so any model drives the same fixed embodiment without modifying Unity
- 2
Primary observation: first-person RGB from the pose the last action produced, optionally with a bounded frame buffer for visual history
- 3
A map tool gives a georeferenced overhead view the agent can pan/zoom — but it never shows a computed or highlighted route
- 4
One structured action per turn from A=Afp∪Amap∪{terminate}
- 5
Afp={move,sprint,look,jump,open map} — move/sprint carry a direction, duration, and optional yaw/pitch/jump fields, so view changes and jumps fold into a movement action; strafe is not separate
- 6
Amap={map select,map pan,map zoom,map orbit,close map}
- 7
Episodes end on answer, completion signal, or 100 steps; at ≤2s per movement action that is up to 200s of commanded motion, so failures can't be blamed on an infeasible horizon
Mathematical Formulation
The Action Space
A=Afp∪Amap∪{terminate},Afp={move,sprint,look,jump,open map},Amap={map select,map pan,map zoom,map orbit,close map}
At each turn the agent selects exactly one action object from A. Movement actions fold view control (yaw/pitch) and jumping into their fields rather than adding separate actions, keeping the interface compact while still allowing continuous physical control.
Further Reading
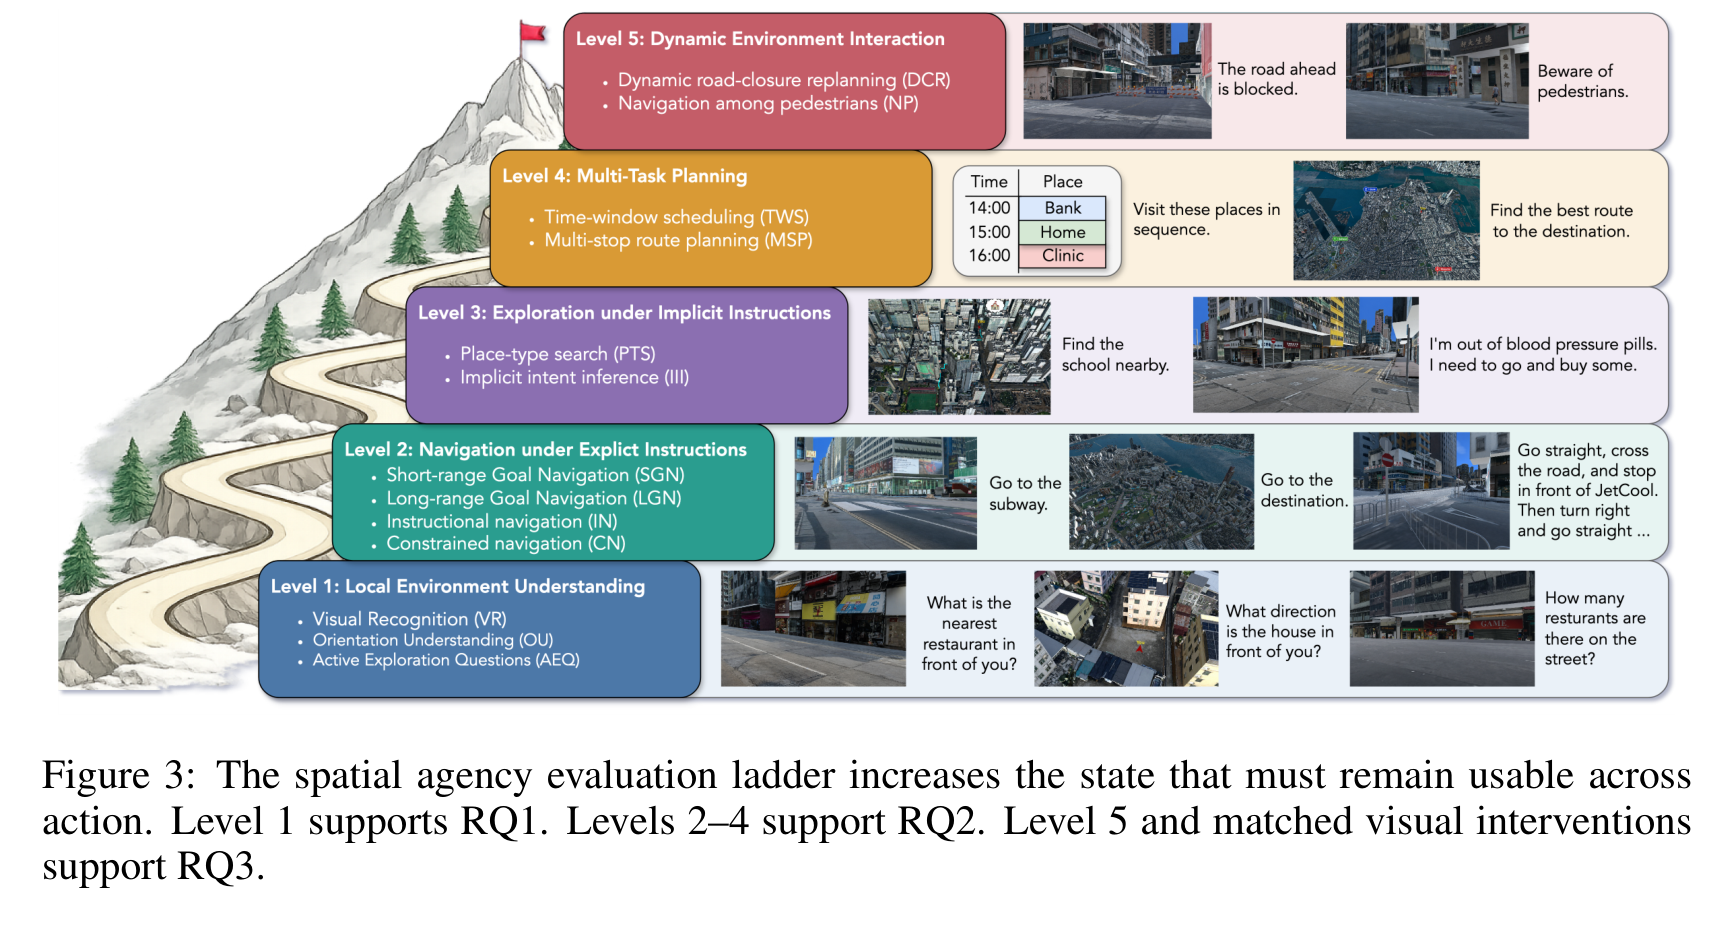
The tasks are organized as a five-level ladder that increases the spatial state required for success while keeping the interaction interface fixed. Holding the interface constant is what isolates the variable of interest: what changes from level to level is not the controls but how much spatial account must survive across action.
Level 1 — Local Environment Understanding (220 instances) studies what can be grounded around the current pose. Visual recognition and orientation test recognition and heading-relative localization; active exploration adds a brief search for evidence outside the initial view. This is the main source of RQ1 tasks. Level 2 — Navigation under Explicit Instructions (240) introduces goals over routes: short- and long-range tasks vary how long grounded evidence must remain useful, while instructional and constrained variants test whether route language or path restrictions stay active during execution. Level 3 — Exploration under Implicit Instructions (120) moves to place-type search and implicit intent inference, where the agent must infer where to go before it can navigate. Level 4 — Multi-Task Planning (120) extends persistence to time-window scheduling and multi-stop routing, maintaining and executing a plan across several goals under task-provided progress updates. Levels 2–4 together provide the RQ2 tasks and stress persistence while retaining local grounding.
Level 5 — Dynamic Environment Interaction (110) introduces change during execution. A one-time system notice discloses a road closure that invalidates an earlier route, with the unavailable segment marked on the map; moving pedestrians require the agent to adjust its motion around visible obstacles. Matched time-and-weather conditions additionally apply to Level 1 and the short-navigation task in Level 2, changing the visual evidence at the same task locations. These provide the RQ3 tasks, examining adaptation while presupposing the earlier capabilities.
The whole study contains 810 manually verified base instances distributed across urban regions of Hong Kong chosen to differ in street pattern, terrain, and vertical pedestrian connection. Every instance was completed by human testers under the same 100-step limit used for the agents. The scoring is deliberately physical: question-answering episodes are scored against the annotated answer, but single-endpoint navigation succeeds only when the final position is within 15 meters of the destination and any enforced constraint is satisfied. Pedestrian-network adherence (PNA) — the fraction of action time whose post-action state lies on the registered network — is tracked throughout, and dynamic tasks add closure-violation, pedestrian-contact, and rain-exposure records.
Key Points
- 1
A five-level ladder raises the required spatial state while holding the interface fixed — isolating persistence, not controls, as the variable
- 2
L1 · Local Environment Understanding — 220 instances (visual recognition, orientation, active exploration) → the main RQ1 tasks
- 3
L2 · Navigation under Explicit Instructions — 240 (short, long, instructional, constrained navigation)
- 4
L3 · Exploration under Implicit Instructions — 120 (place-type search, implicit intent inference — the destination must be inferred)
- 5
L4 · Multi-Task Planning — 120 (time-window scheduling, multi-stop routing) — L2–L4 supply the RQ2 tasks
- 6
L5 · Dynamic Environment Interaction — 110 (road-closure replanning, navigation among pedestrians) + matched weather/time → the RQ3 tasks
- 7
810 manually verified base instances across Hong Kong regions, each also completed by human testers under the same 100-step limit
- 8
Navigation succeeds only within 15 meters of the target with constraints satisfied; PNA (fraction of action time on the registered pedestrian network) is tracked throughout
Further Reading
The results read as a descent down the ladder, and the pattern is remarkably consistent across twelve contemporary models — GPT-5.6-Luna/5.5/5.4/5.2, Claude-Opus-5/4.6, Gemini-3.8-Flash/3.6-Flash/3.1-Pro, Doubao-Seed-2.0-Pro, GLM-5V-Turbo, and Kimi-K3.
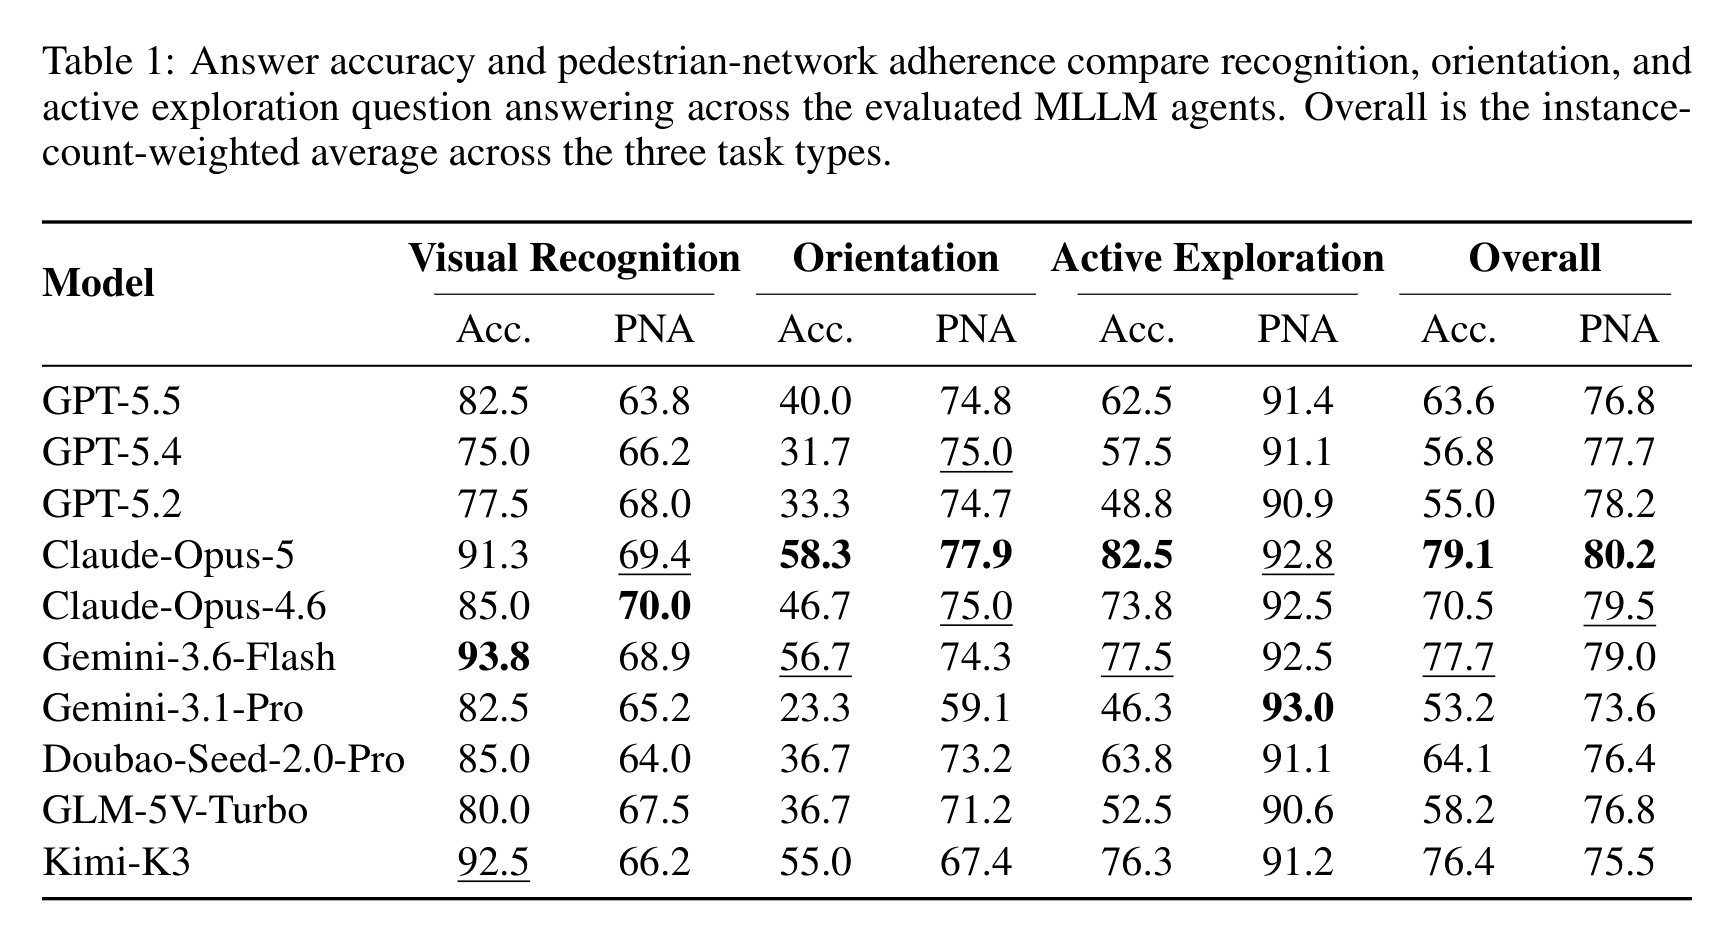
RQ1 — grounding mostly works, orientation does not. On local question answering, most models are strong on visual recognition where the instruction and evidence are explicit, and answer accuracy declines only moderately on active exploration. Overall Level-1 accuracy tops out at 79.1 (Claude-Opus-5), with Gemini-3.6-Flash at 77.7 and Kimi-K3 at 76.4. But orientation is a shared atomic weakness: performance falls markedly, with several systems approaching the random-guessing baseline for a four-option question — Gemini-3.1-Pro reaches just 23.3 on orientation, below chance, and even GPT-5.2 sits at 33.3. Identifying a visible landmark plainly does not guarantee a stable representation of its direction relative to the current heading. Pedestrian-network adherence exposes a second gap: agents often favor a shorter path to the evidence and sacrifice road compliance to answer faster.
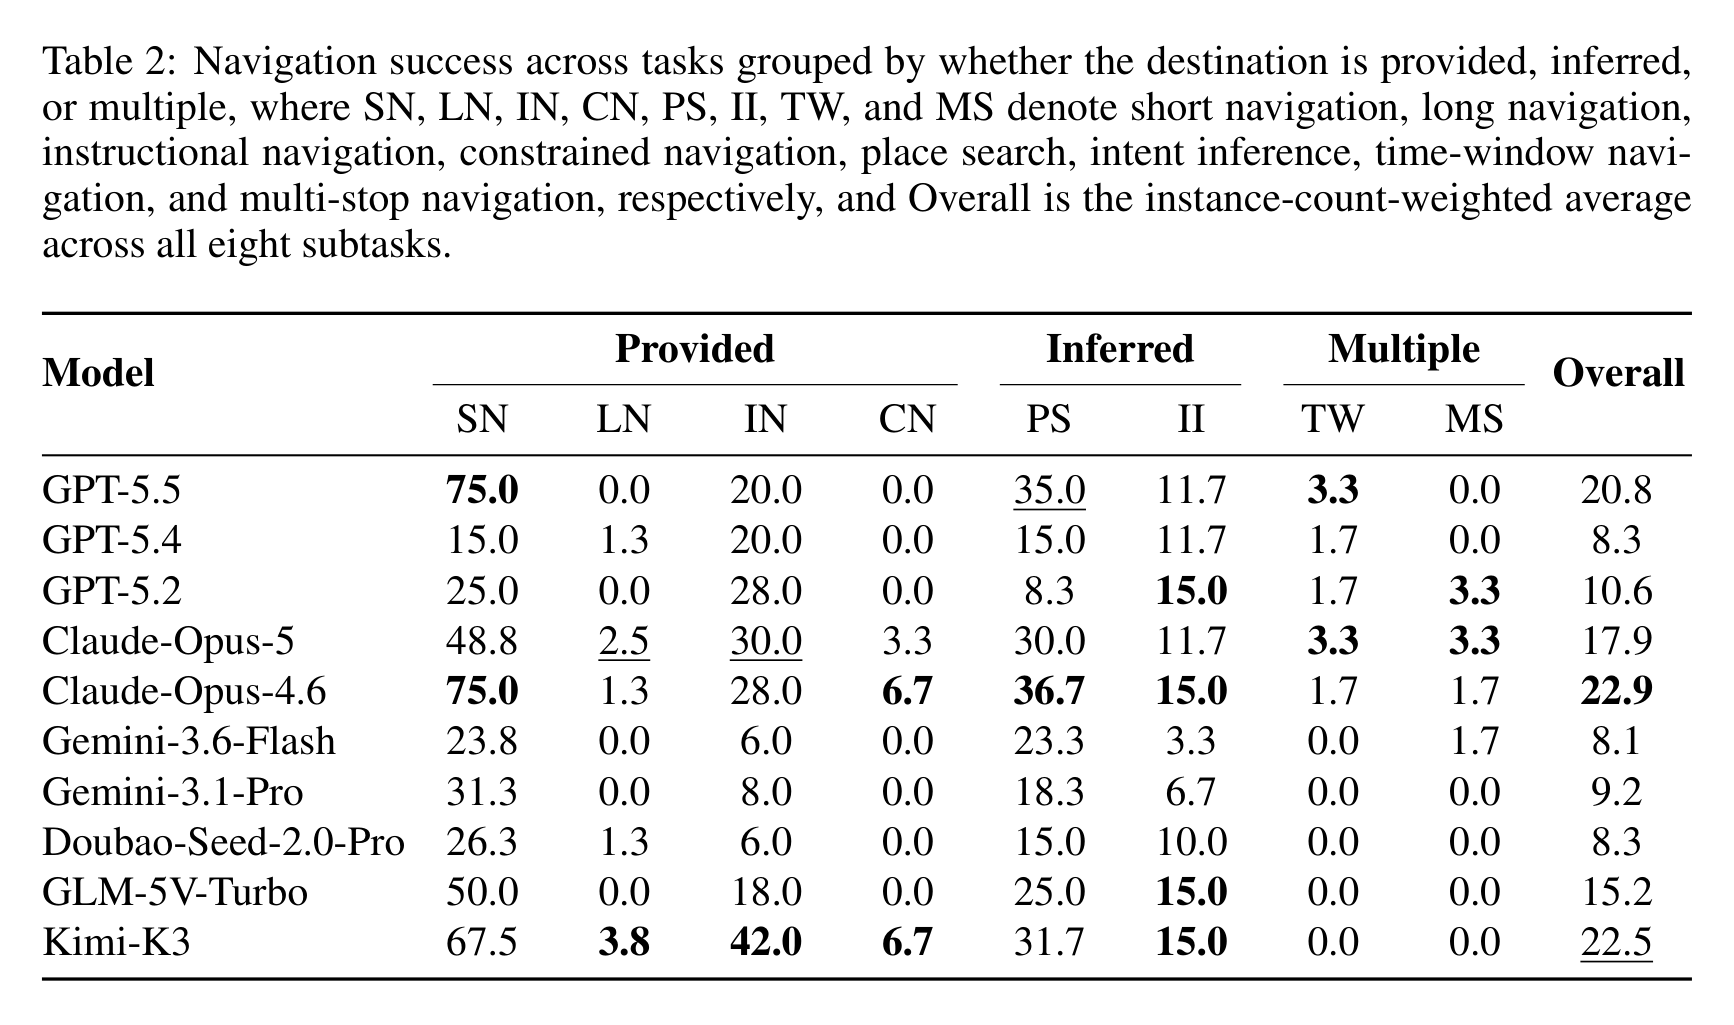
RQ2 — navigation collapses past a few blocks. With an explicit, visible destination on short routes, some models do meaningfully well — GPT-5.6-Luna hits 81.3 on ShortNav, and GPT-5.5 and Claude-Opus-4.6 both reach 75.0. But when the same point-to-point task is evaluated at a longer scale, nearly every model fails: long-range success is 0.0 for half the models and never above 5.0. This is not merely a longer distance — a route that decomposes into short-range goals should be solvable one hop at a time. The models cannot compose those atomic capabilities because errors accumulate during execution without effective correction. Overall navigation stays low across the eight subtasks: 22.9 (Claude-Opus-4.6), 22.5 (Kimi-K3), 20.8 (GPT-5.5) at the top; several models under 10. A distance-stratified analysis confirms success concentrates in the shorter bins and declines with horizon even within nominally local tasks. Trajectory analysis softens the picture only slightly: more than 50% of long-range episodes still end closer to the goal than they began (up to 81.3%), and multi-stop agents reach 6.8–20.7% of required destinations on average — useful local direction, without preserved global route state.
RQ3 — plausible movement outlives effective adaptation. Dusk and night reduce local QA accuracy by lowering sign and storefront visibility, and robustness is uneven even within a family — GPT-5.5 and Gemini-3.6-Flash stay comparatively stable while GPT-5.4 and Gemini-3.1-Pro swing more. Curiously, agents often do worse at dusk than at night, possibly from dusk lighting interference. Weather and time affect navigation less systematically than QA. The sharpest result is dynamic: under a road closure, goal-reaching rate stays near zero while PNA stays high (~93–96%) and safe-progress rate remains low (10–46.7%); under moving pedestrians, the pedestrian-collision rate is high for every model (76.3–90.0%). Staying on the pedestrian network plainly does not imply collision-aware or goal-directed control.
Key Points
- 1
RQ1 grounding is strong: top Level-1 overall accuracy 79.1 (Claude-Opus-5), 77.7 (Gemini-3.6-Flash), 76.4 (Kimi-K3), declining only moderately on active exploration
- 2
Orientation is a shared atomic weakness — several models near the four-option random baseline: Gemini-3.1-Pro 23.3, GPT-5.2 33.3 — so recognizing a landmark ≠ knowing its direction relative to heading
- 3
RQ2 short-range works, long-range collapses: GPT-5.6-Luna reaches 81.3 on ShortNav (GPT-5.5 and Claude-Opus-4.6 75.0), but long-range success is 0.0 for half the models and never above 5.0
- 4
Best overall navigation across eight subtasks is only 22.9 (Claude-Opus-4.6) / 22.5 (Kimi-K3) / 21.3 (GPT-5.6-Luna); several models fall below 10
- 5
The failure is compositional, not distance: errors accumulate without effective correction, and success declines with horizon even within nominally local tasks
- 6
Partial credit exists: >50% of long-range episodes end closer to the goal (up to 81.3%); multi-stop agents reach 6.8–20.7% of destinations on average
- 7
RQ3: dusk/night lower local QA (often worse at dusk than night); weather affects navigation less systematically than QA
- 8
Dynamic failure is the sharpest: under road closure, goal-reaching ≈ 0 while PNA stays ~93–96% and safe-progress rate is 10–46.7%; among pedestrians, collision rate is 76.3–90.0%
The paper's conclusion is a single, well-supported diagnosis: urban agency cannot be inferred from isolated perception or from success over a short route. Current MLLMs possess useful local spatial skills — visual recognition and short-range reasoning — but these skills lose reliability as interaction extends through the city, and the central failure emerges over extended exploration where local abilities do not compose into sustained goal-directed behavior.
What makes the finding precise rather than merely pessimistic is the shape of the failure, which recurs at every spatial scale. Models recognize local evidence more reliably than they orient it; they execute useful local motion more reliably than they complete a route; and they preserve compliant movement more reliably than they update a plan after the city changes. Read together, these say the same thing at three resolutions: the grounded spatial state ceases to guide action toward the objective long before the agent stops producing plausible local movements. An agent can keep making locally sensible steps — staying on the pedestrian network, moving toward the estimated goal direction — for the entire episode while the goal-directed thread has already been lost.
The dynamic tasks make the gap most visible. When a route becomes invalid mid-execution, agents often continue producing locally compliant movements even after their spatial plan has become obsolete — a road-closure notice is acknowledged on the map yet the safe-progress rate stays low. When blocked by a central obstacle, an agent frequently repeats the same forward action without revising the route, unable to distinguish geometric proximity from a traversable path. This is the difference between plausible local behavior and effective adaptation, and it is exactly what a single-viewpoint benchmark can never surface.
The constructive reading is a research agenda. City-scale agency depends on maintaining a spatial estimate after the current view disappears, and revising it whenever earlier plans cease to be feasible — persistence and adaptation, the two capabilities that grounding alone does not buy. UrbanGround's contribution is to make that gap observable in a real geographic setting, where every action changes the evidence available to the agent, so future work on agents that move reliably through complex, open-ended cities has a place to measure itself. The environment ships on the web and as native macOS, Windows, and Linux builds, with the tasks released alongside.
Key Points
- 1
Central claim: urban agency cannot be inferred from isolated perception or short-route success — local skills lose reliability as interaction extends through the city
- 2
The failure has a consistent shape at every scale: models recognize more reliably than they orient, move locally more reliably than they complete a route, and stay compliant more reliably than they replan
- 3
One sentence captures it: the grounded spatial state stops guiding action toward the goal long before the agent stops producing plausible local movements
- 4
Dynamic tasks expose it sharpest — after a route is invalidated, agents keep making locally compliant moves; when blocked, they repeat the same action without revising the route, confusing geometric proximity with a traversable path
- 5
The open problem is persistence + adaptation: maintain a spatial estimate after the view disappears and revise it when plans become infeasible — what grounding alone cannot provide
- 6
UrbanGround's value is making this gap observable in a real georegistered city, where every action changes the available evidence
- 7
Released on the web and as native macOS / Windows / Linux builds, with the task suite, to support future study of reliable city-scale exploration
Further Reading
Keep reading
Related Papers
Go deeper