Qwen3
Unified Thinking and Non-Thinking Modes, Thinking Budgets, and Strong-to-Weak Distillation in an Open Dense + MoE LLM Family
Qwen Team
10
Concepts
9
Formulas
10
Figures
5
Demos
Paper Overview
Qwen3 (Qwen Team, Alibaba, 2025) is a family of open-weight LLMs — six dense models from 0.6B to 32B and two Mixture-of-Experts models, Qwen3-30B-A3B and the flagship Qwen3-235B-A22B — built around one idea: a single model should be able to both think and not think.
Until then, reasoning and chat were separate products. You ran a chat model for fast answers and a reasoning model (like QwQ-32B) for hard problems, and chose between them per query. Qwen3 folds both into one set of weights, switched per turn with /think and /no_think, and adds a thinking budget that caps reasoning tokens so latency and accuracy can be traded continuously. Remarkably, the budget is not trained — it emerges from teaching the model both endpoints.
The machinery behind this is a 36T-token, 119-language pre-training run in three stages; a four-stage post-training pipeline (long-CoT cold start, reasoning RL, thinking-mode fusion, general RL) for the flagships; and strong-to-weak distillation that passes both modes to small models at about a tenth of the GPU hours.
The flagship reaches 85.7 on AIME'24, 81.5 on AIME'25, 70.7 on LiveCodeBench v5 and a 2,056 CodeForces rating in thinking mode, beats DeepSeek-R1 on 17 of 23 benchmarks with 22B activated parameters, and everything ships under Apache 2.0.
Chapter Roadmap
Click any topic to jump in
One Model, Two Modes
Chat and reasoning used to be separate models. Qwen3 folds both into one set of weights, switched per turn by /think and /no_think.
Model and data
Dense + MoE Family
Six dense and two MoE models; QK-Norm replaces QKV-bias, and 128 experts with 8 active and no shared expert.
36T-Token Pre-training
119 languages, VLM-extracted PDFs and synthetic data; three stages for breadth, reasoning depth, then 32K context.
Stages 1–2: Build the Reasoner
A deliberately small long-CoT cold start, then GRPO on 3,995 query-verifier pairs — AIME'24 70.1 → 85.1 in 170 steps.
Two modes, one dial
Stage 3: Thinking Mode Fusion
SFT with a chat template where non-thinking answers keep an empty <think></think> block; the model obeys the last flag.
The Thinking Budget
Cut the reasoning at a token threshold, insert a stop instruction, and the model answers from partial thinking — untrained, emergent.
Flagships and lightweight models
Stage 4: General RL
Rewards over 20+ tasks lift mode switching to 98.9 and tool use by +15, at the cost of a few points of peak reasoning.
Strong-to-Weak Distillation
Small models learn both modes from the flagships; on-policy distillation beats RL on Qwen3-8B at 1/10 of the GPU hours.
Outcomes and caveats
Results
AIME'24 85.7, LiveCodeBench 70.7, CodeForces 2,056; beats DeepSeek-R1 on 17/23 and GPT-4o on 18/23 benchmarks.
Long Context & Limits
On RULER, thinking mode slightly hurts retrieval — a reminder that more test-time compute is not always better.
Concept by concept
10 sections, in reading order.
By early 2025 an open-model user who wanted both a fast chat assistant and a careful reasoner had to run two different models. The Qwen line itself was split this way: Qwen2.5 for chat, QwQ-32B for long chain-of-thought reasoning. The report names the same split in the closed world — chat-optimised GPT-4o on one side, dedicated reasoning models on the other. Every application had to decide up front which model a query deserved, and pay to deploy both.
That split is wasteful in an obvious way and a subtle one. The obvious waste is operational: two sets of weights, two serving stacks, a router in front. The subtle waste is that most queries sit somewhere between trivial and olympiad-hard. A greeting does not need thousands of reasoning tokens; a competition problem cannot be solved without them; and a large middle band would benefit from some thinking but not an unbounded amount. A binary choice between models cannot express that middle band at all.
Qwen3's central design decision is to fold both behaviours into a single set of weights. The same model answers immediately when asked with /no_think and reasons at length when asked with /think (or by default). Because one model has learned both endpoints, it also handles the in-between: stop its reasoning early at a user-chosen thinking budget, and it writes the best answer it can from the partial reasoning. Compute per query becomes a dial rather than a model choice.
The rest of the report is the machinery that makes this possible: a family of eight dense and MoE models pre-trained on 36T tokens in 119 languages, a four-stage post-training pipeline that first builds a reasoner and then teaches it to not reason on request, and a strong-to-weak distillation path that hands both modes down to small models at a fraction of the cost. The flagship Qwen3-235B-A22B — 235B parameters, 22B active per token — reaches 85.7 on AIME'24, 81.5 on AIME'25 and 70.7 on LiveCodeBench v5 in thinking mode, and everything is released under Apache 2.0.
Key Points
- 1
Before Qwen3, reasoning and chat were separate models (e.g. Qwen2.5 vs QwQ-32B; GPT-4o vs dedicated reasoning models) — users switched models to switch behaviour
- 2
Qwen3 integrates thinking mode (multi-step reasoning) and non-thinking mode (rapid responses) into one set of weights
- 3
Mode is selected per turn with /think and /no_think flags in the user query or system message; thinking is the default
- 4
A thinking budget lets users cap reasoning tokens, trading latency for accuracy continuously instead of choosing between two models
- 5
Family: 6 dense models (0.6B–32B) and 2 MoE models (30B-A3B, 235B-A22B), all open-weight under Apache 2.0
- 6
Multilingual coverage expands from 29 to 119 languages and dialects compared to Qwen2.5
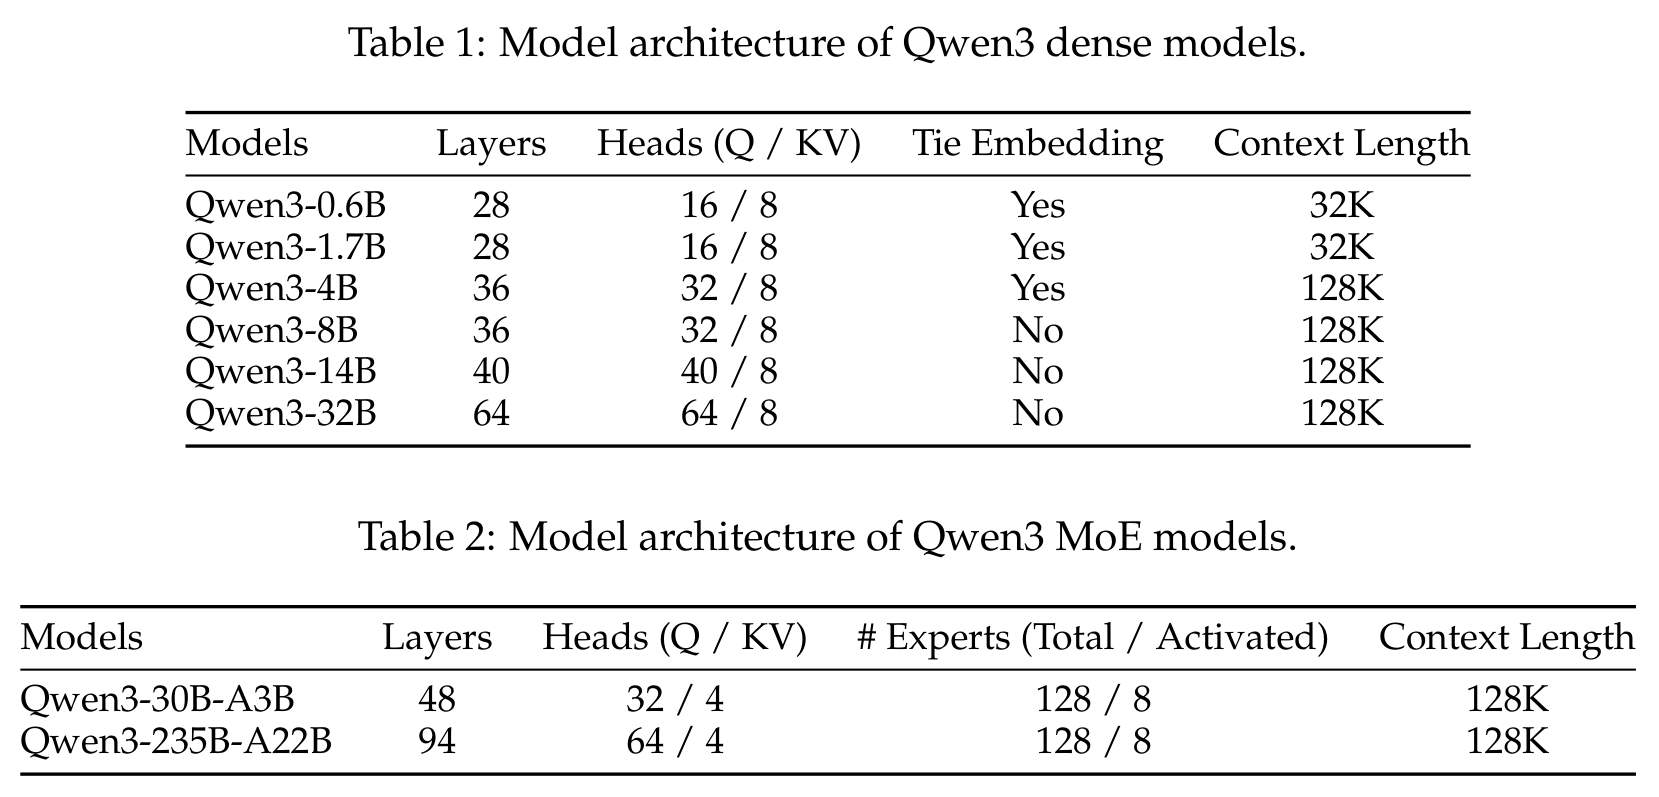
Qwen3 does not introduce a new architecture; it deliberately inherits Qwen2.5's and changes a few load-bearing details. The dense models use Grouped Query Attention, SwiGLU, RoPE and RMSNorm with pre-normalization — the standard modern decoder. Two changes are specific to Qwen3: the QKV-bias used in Qwen2 is removed, and QK-Norm is added to the attention mechanism "to ensure stable training."
QK-Norm addresses a specific instability. Attention logits are dot products q⊤k, and nothing in a plain transformer bounds the norms of q and k. As training proceeds those norms can grow, logits blow up, and softmax saturates into near one-hot attention with vanishing gradients — the loss-spike failure mode seen when scaling. Normalising queries and keys before the dot product caps the logit scale structurally instead of hoping the optimiser keeps it in check.
The MoE models share the dense architecture but replace the feed-forward block with 128 experts, 8 activated per token, using fine-grained expert segmentation. Two choices depart from Qwen2.5-MoE. First, Qwen3-MoE excludes shared experts — there is no always-on expert that every token passes through. Second, it adopts the global-batch load-balancing loss, which measures expert usage over the whole global batch rather than each micro-batch. Balancing per micro-batch forces every small slice of data to use every expert evenly, which fights specialisation; balancing globally lets a code-heavy micro-batch lean on code experts as long as usage evens out across the batch. The report states the goal plainly: "to encourage expert specialization."
The payoff shows up in the flagship: Qwen3-235B-A22B has 94 layers, 64 query heads sharing 4 KV heads, and activates about 22B of its 235B parameters per token. All models share Qwen's byte-level BPE tokenizer with a vocabulary of 151,669. The smaller dense models (0.6B–4B) tie input and output embeddings; context length is 32K for 0.6B/1.7B and 128K for everything else.
Key Points
- 1
Dense backbone inherited from Qwen2.5: GQA, SwiGLU, RoPE, RMSNorm with pre-normalization
- 2
QKV-bias removed (it was used in Qwen2) and QK-Norm added to the attention mechanism to stabilise training
- 3
Dense sizes: 0.6B, 1.7B, 4B, 8B, 14B, 32B — 28 to 64 layers, always 8 KV heads; embeddings tied up to 4B
- 4
MoE sizes: Qwen3-30B-A3B (48 layers, 32/4 heads) and Qwen3-235B-A22B (94 layers, 64/4 heads), both with 128 experts, 8 activated
- 5
Unlike Qwen2.5-MoE, Qwen3-MoE has no shared experts, and uses the global-batch load-balancing loss to encourage specialisation
- 6
Tokenizer: Qwen's byte-level BPE with a vocabulary of 151,669 tokens
- 7
Context length: 32K for 0.6B and 1.7B, 128K for 4B and above
Mathematical Formulation
QK-Norm Attention
Attn(Q,K,V)=softmax(dhNorm(Q)Norm(K)⊤)V
Queries and keys are normalised before the dot product (Dehghani et al., 2023), so attention logits cannot grow without bound as weight norms drift. The report adds this to Qwen3 in place of Qwen2's QKV-bias “to ensure stable training”; dh is the per-head dimension.
Sparse Activation
totalactive=235B22B≈9.4%,30B3B=10%,1288=6.25% of experts
Each token visits 8 of 128 experts. Attention, embeddings and norms are always active, so the activated-parameter share (about 9–10%) is higher than the expert share (6.25%). This is what lets the MoE models match dense models with roughly 1/5 of the activated parameters, as the base-model evaluation reports.
Compared with Qwen2.5, Qwen3 collects twice as many pre-training tokens covering three times more languages: 36 trillion tokens across 119 languages and dialects. Getting there required finding text the web does not hand over cleanly.
Two sources are notable. First, PDF-like documents: Qwen2.5-VL performs text recognition on a large volume of them, and Qwen2.5 then refines the recognised text — a two-step pipeline yielding "trillions" of additional high-quality tokens. Second, synthetic data: Qwen2.5, Qwen2.5-Math and Qwen2.5-Coder synthesise trillions of tokens in textbook, QA, instruction and code-snippet formats. The previous generation of models is, in effect, the data engine for the next.
The mixture is also chosen differently. A multilingual annotation system labels over 30T tokens along dimensions such as educational value, field, domain and safety. Where earlier work tunes the data mixture at the source or domain level, Qwen3 optimises it at the instance level, using ablations on small proxy models with these fine-grained labels.
Training then proceeds in three stages with a clear logic: breadth, then depth, then length. S1 (General) trains on over 30T tokens at a 4,096-token sequence length for language proficiency and world knowledge. S2 (Reasoning) raises the share of STEM, coding, reasoning and synthetic data for about 5T higher-quality tokens, with accelerated learning-rate decay. The Long Context stage trains on hundreds of billions of tokens at 32,768 length, raises the RoPE base frequency from 10,000 to 1,000,000 (ABF), and adds YARN and Dual Chunk Attention for a four-fold increase in usable sequence length at inference.
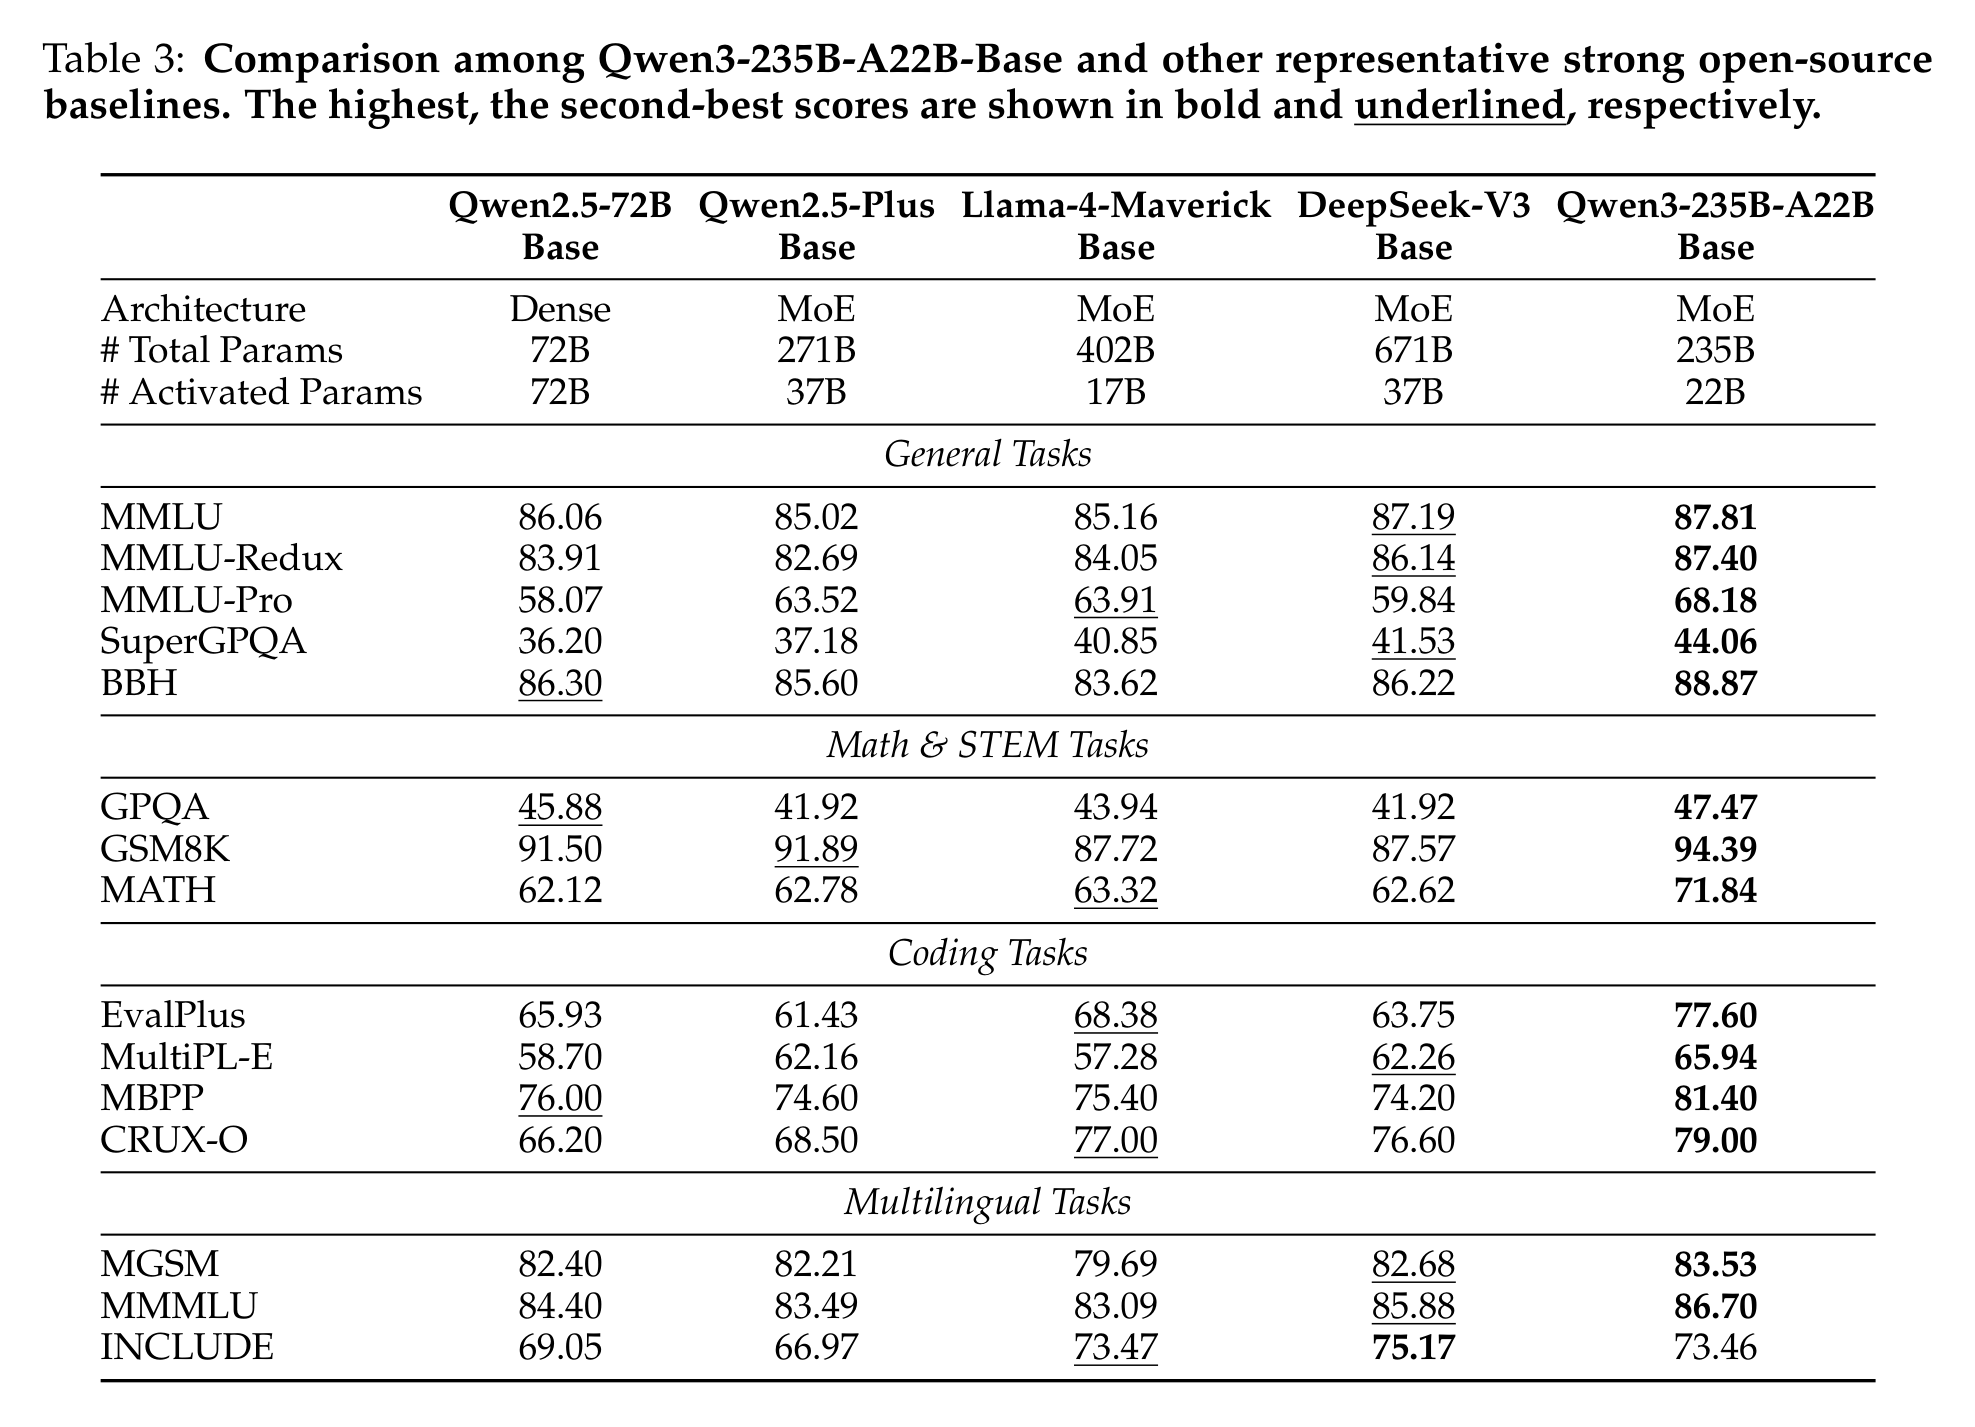
The base models show the effect. Qwen3-235B-A22B-Base beats DeepSeek-V3-Base on 14 of 15 benchmarks with about 1/3 the total and 2/3 the activated parameters, and Qwen3-1.7B/4B/8B/14B/32B-Base match Qwen2.5-3B/7B/14B/32B/72B-Base respectively — roughly one size class of free improvement from data and training alone.
Key Points
- 1
36T tokens in 119 languages and dialects — 2x the tokens and 3x the languages of Qwen2.5 (29 → 119)
- 2
Qwen2.5-VL extracts text from PDF-like documents, then Qwen2.5 refines it — trillions of extra tokens
- 3
Qwen2.5 / Qwen2.5-Math / Qwen2.5-Coder synthesise trillions of tokens: textbooks, QA, instructions, code snippets
- 4
A multilingual annotation system labels 30T+ tokens; the data mixture is optimised at the instance level with small proxy models
- 5
S1 General: 30T+ tokens at 4,096 length. S2 Reasoning: ~5T STEM/code/reasoning-heavy tokens, faster LR decay
- 6
Long-context stage: hundreds of billions of tokens at 32,768 length (75% of texts 16K–32K, 25% 4K–16K), RoPE base 10,000 → 1,000,000
- 7
YARN + Dual Chunk Attention give a 4x increase in sequence length capacity at inference
- 8
Scaling laws predict the optimal learning rate and batch size for each dense and MoE model per stage
Mathematical Formulation
RoPE Base-Frequency Adjustment (ABF)
θi=b−2i/d,b:10,000⟶1,000,000
Each pair of dimensions i rotates at frequency θi. Raising the base b slows every rotation, so positions far beyond the pre-training length still map to angles the model has seen. Qwen3 follows Qwen2.5 in applying this during the long-context stage.
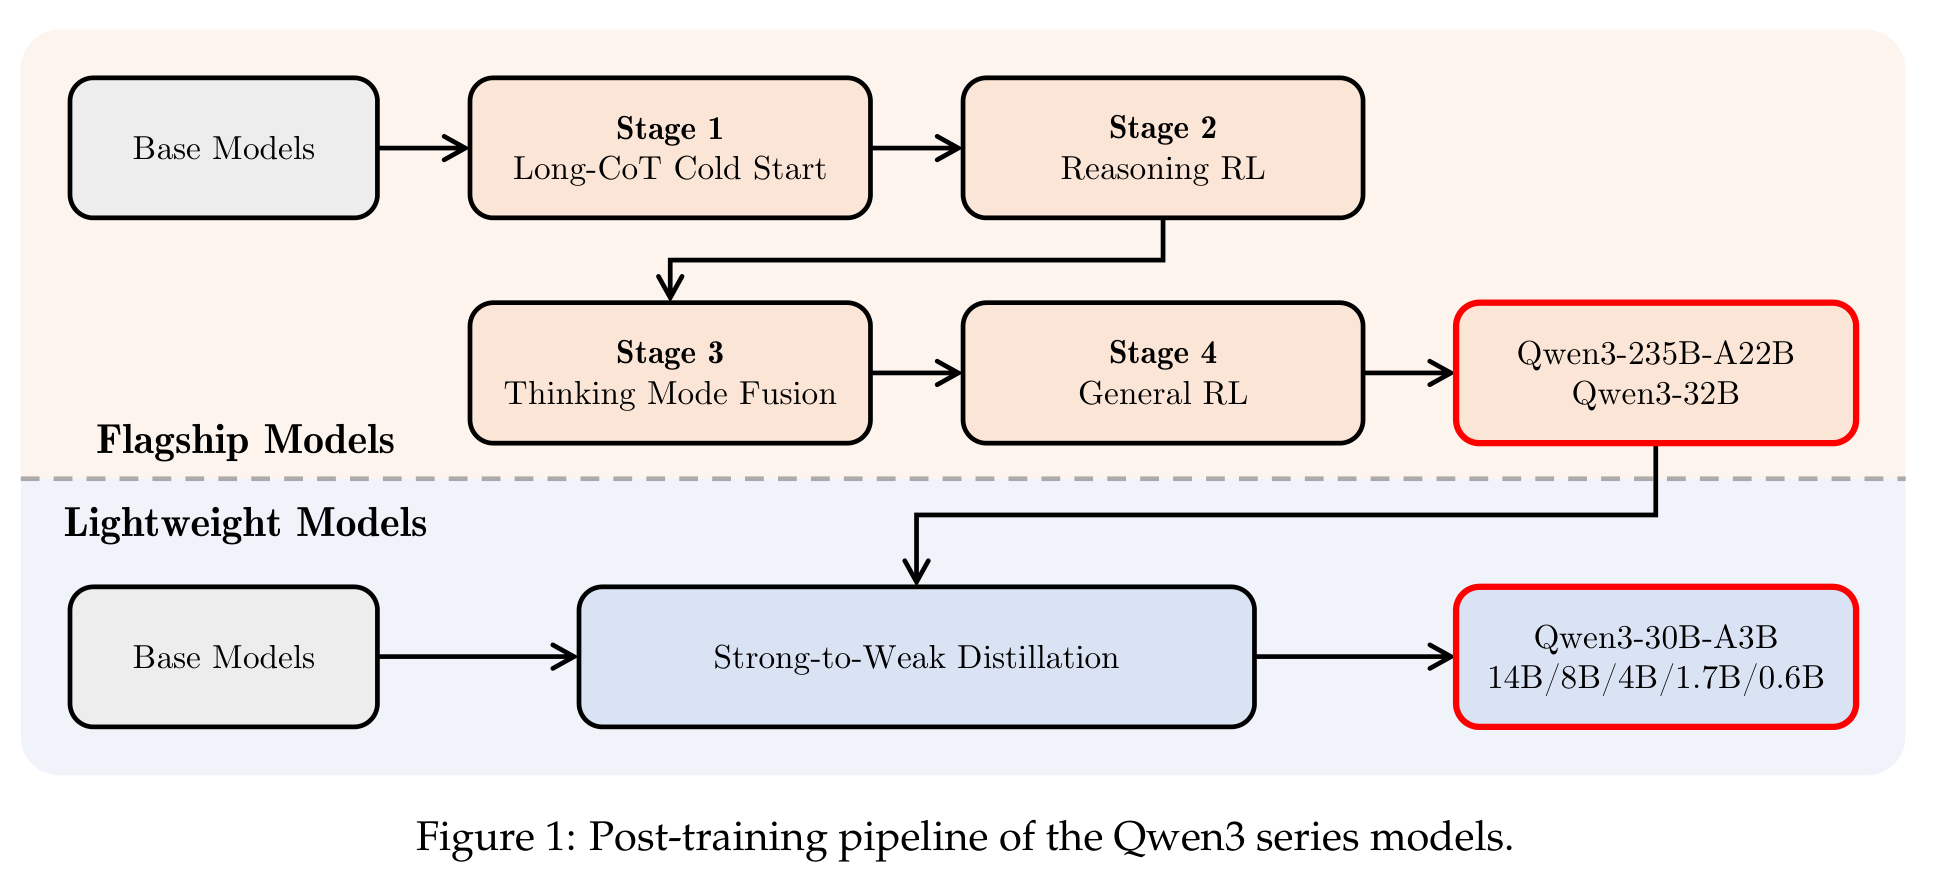
Post-training has two goals: thinking control (both modes, plus budgets) and strong-to-weak distillation (cheap small models). Only the flagship models — Qwen3-235B-A22B and Qwen3-32B — go through the full four-stage pipeline. The first two stages build a strong reasoner; the last two teach it to also not reason.
Stage 1, Long-CoT Cold Start, is notable for how little it tries to do. The data is filtered hard. Qwen2.5-72B-Instruct removes queries that are not easily verifiable, and — more interestingly — queries it can already answer without chain-of-thought, so the model cannot learn to guess its way past problems that should require reasoning. QwQ-32B generates N candidate responses per query, and responses are thrown out for wrong answers, heavy repetition, guesswork, thinking/summary inconsistency, language mixing, or suspected overlap with validation items. Then only a carefully selected subset is used, and the report says it is preferable to minimise both samples and steps. The objective is to instil reasoning patterns without over-committing the model's behaviour, leaving room for RL to improve on.
Stage 2, Reasoning RL, uses just 3,995 query-verifier pairs chosen to be unseen in cold start, learnable by the cold-start model, as hard as possible, and broad across sub-domains. Parameters are updated with GRPO. The report highlights three practical levers: large batch sizes, many rollouts per query, and off-policy training for sample efficiency — plus controlling the model's entropy to rise steadily or stay stable, balancing exploration and exploitation. The result is a single uninterrupted run with no manual hyperparameter intervention in which Qwen3-235B-A22B's AIME'24 score climbs from 70.1 to 85.1 over 170 RL steps.
Key Points
- 1
Flagship models follow four stages: Long-CoT Cold Start → Reasoning RL → Thinking Mode Fusion → General RL
- 2
Lightweight models skip the four stages and are built by Strong-to-Weak Distillation from the flagships
- 3
Cold-start query filter: drop unverifiable queries and queries Qwen2.5-72B-Instruct answers correctly without CoT
- 4
Responses come from QwQ-32B and are filtered for wrong answers, repetition, guesswork, thinking/summary inconsistency, language mixing, and validation overlap
- 5
Cold start deliberately uses few samples and few steps — the goal is reasoning patterns, not peak scores
- 6
Reasoning RL uses 3,995 query-verifier pairs and GRPO, with large batches, many rollouts per query, and off-policy training
- 7
Entropy is kept rising or stable; AIME'24 for Qwen3-235B-A22B goes 70.1 → 85.1 in 170 RL steps with no manual hyperparameter changes
Mathematical Formulation
Group-Relative Advantage (GRPO)
A^i=std(r1,…,rG)ri−mean(r1,…,rG)
GRPO (Shao et al., 2024) samples a group of G rollouts per query and scores each against the group rather than a learned critic. With verifiable rewards ri from the query-verifier pairs, a rollout is pushed up only if it beats its siblings — which is why many rollouts per query helps.
After Stage 2 the model is a strong reasoner that always reasons. Stage 3 adds the ability to answer directly — without losing what Stage 2 built. It is continual supervised fine-tuning on the Reasoning-RL model with a chat template that fuses the two modes.
The data design protects the reasoner. The "thinking" half of the SFT set is generated by rejection sampling on Stage 1 queries using the Stage 2 model itself, so the model is trained on its own best reasoning rather than on some other distribution that could drag it backwards. The "non-thinking" half is curated across coding, maths, instruction following, multilingual tasks, creative writing, QA and role-play, quality-checked with automatically generated checklists, with extra translation data to help low-resource languages.
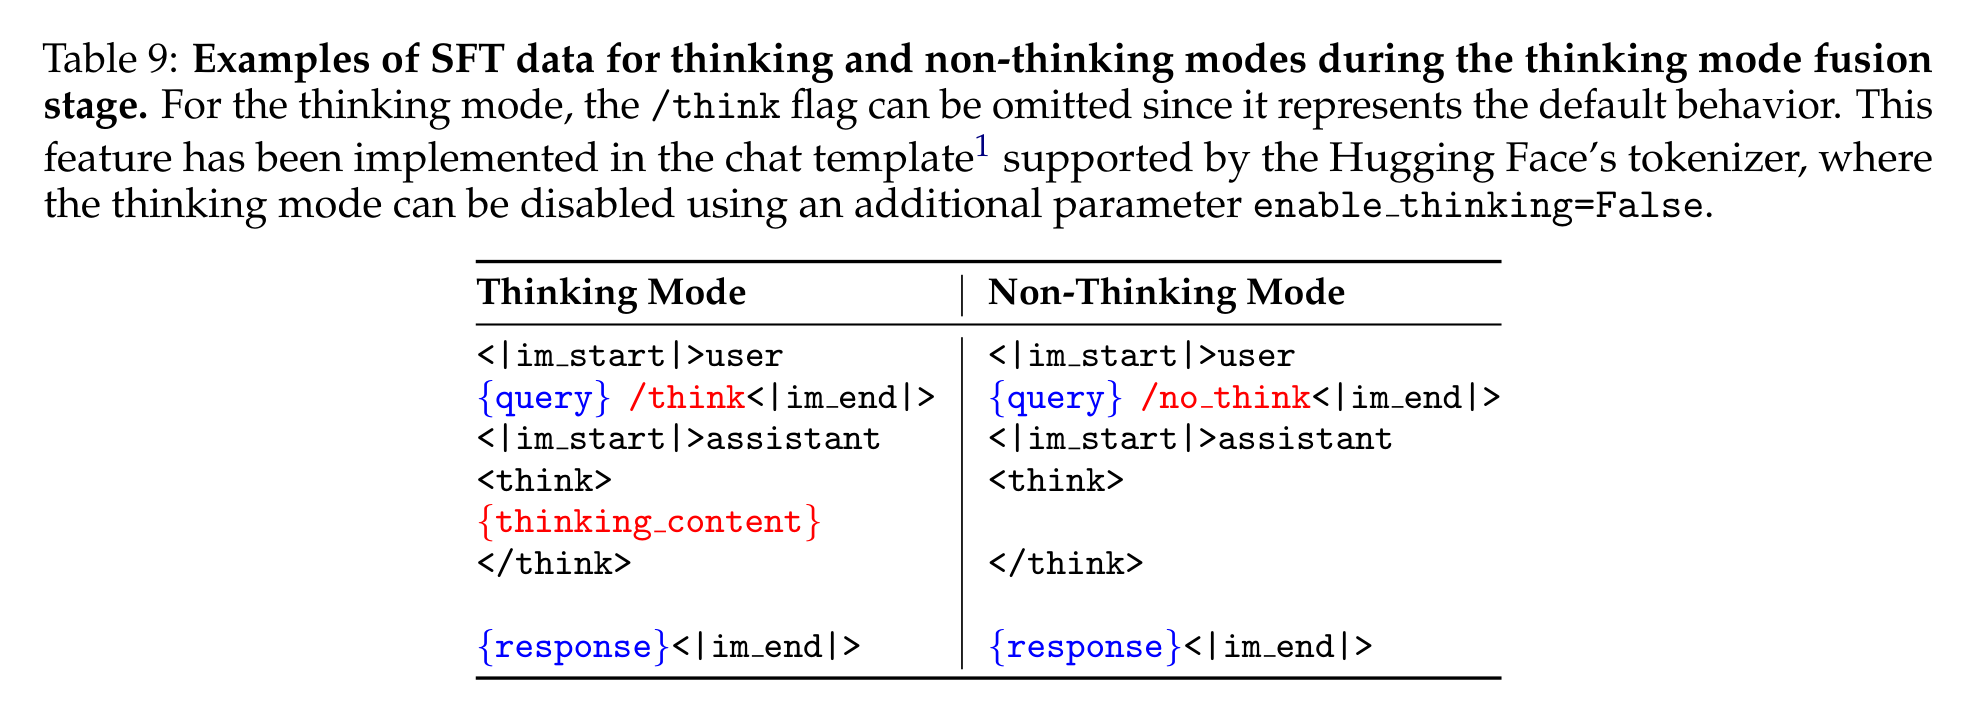
The template is where the interface lives. A /think or /no_think flag goes in the user query or system message. In non-thinking mode the assistant still emits a <think></think> block — just empty. That small choice does two things: the output format is identical in both modes, so the model never has to learn two layouts; and a developer can force non-thinking behaviour purely from the template by pre-filling an empty think block. Because thinking is the default, some training samples omit the flag entirely. For multi-turn dialogues, multiple flags are inserted at random and the model must obey the last flag encountered.
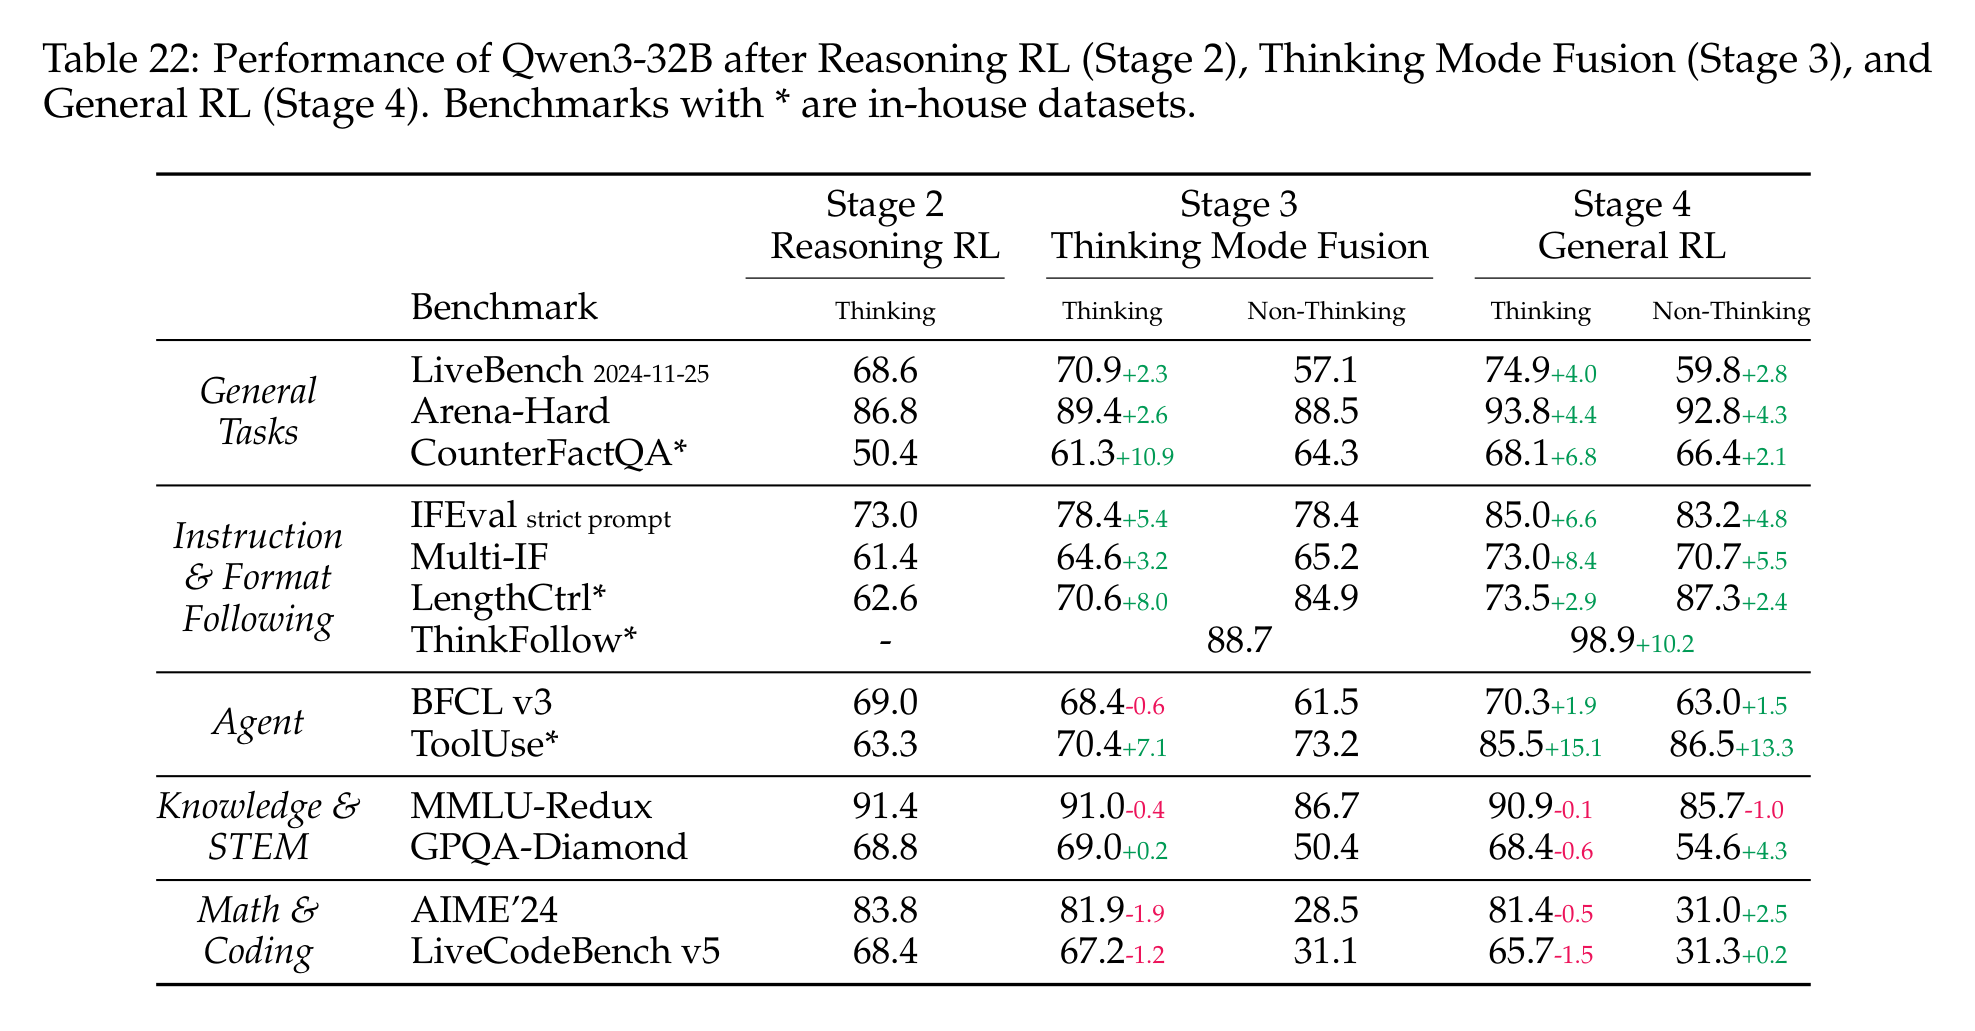
The report's ablation (Table 22) shows the cost and benefit on Qwen3-32B. Stage 3 gives the model an initial mode-switching ability — ThinkFollow 88.7 — and improves thinking-mode general skills (CounterFactQA +10.9, LengthCtrl +8.0). It slightly lowers the hardest thinking-mode scores (AIME'24 83.8 → 81.9, LiveCodeBench 68.4 → 67.2).
Key Points
- 1
Stage 3 is continual SFT on the Stage 2 model with a chat template that fuses both modes
- 2
Thinking data comes from rejection sampling on Stage 1 queries with the Stage 2 model itself, so Stage 2's ability is not overwritten
- 3
Non-thinking data spans coding, maths, instruction following, multilingual, creative writing, QA and role-play, checked with auto-generated checklists
- 4
/think and /no_think flags go in the user query or system message; thinking is the default, so some samples carry no flag
- 5
Non-thinking responses keep an empty <think></think> block: one output format, and developers can force non-thinking via the template
- 6
In multi-turn dialogues the model follows the last flag encountered
- 7
On Qwen3-32B, Stage 3 reaches ThinkFollow 88.7 and lifts CounterFactQA by +10.9 and LengthCtrl by +8.0 in thinking mode
The thinking budget is the most interesting result in the report because nobody trained it. Once a model can respond in both full-thinking and no-thinking modes, it "naturally develops the ability to handle intermediate cases — generating responses based on incomplete thinking." The two trained endpoints make the interpolation work.
The mechanism is almost crude. When the model's thinking reaches a user-defined token threshold, generation is halted and a fixed stop-thinking instruction is inserted: "Considering the limited time by the user, I have to give the solution based on the thinking directly now." followed by </think>. The model then writes its final answer from whatever reasoning it accumulated. There is no separate controller, no budget token, no extra training objective.
Why would this work at all? Stage 3 already taught the model to produce a good answer after an empty think block. A truncated think block is the in-between case: more context than nothing, less than a full derivation. A model that can answer from zero reasoning and from complete reasoning has, in effect, learned to answer from whatever reasoning is present.
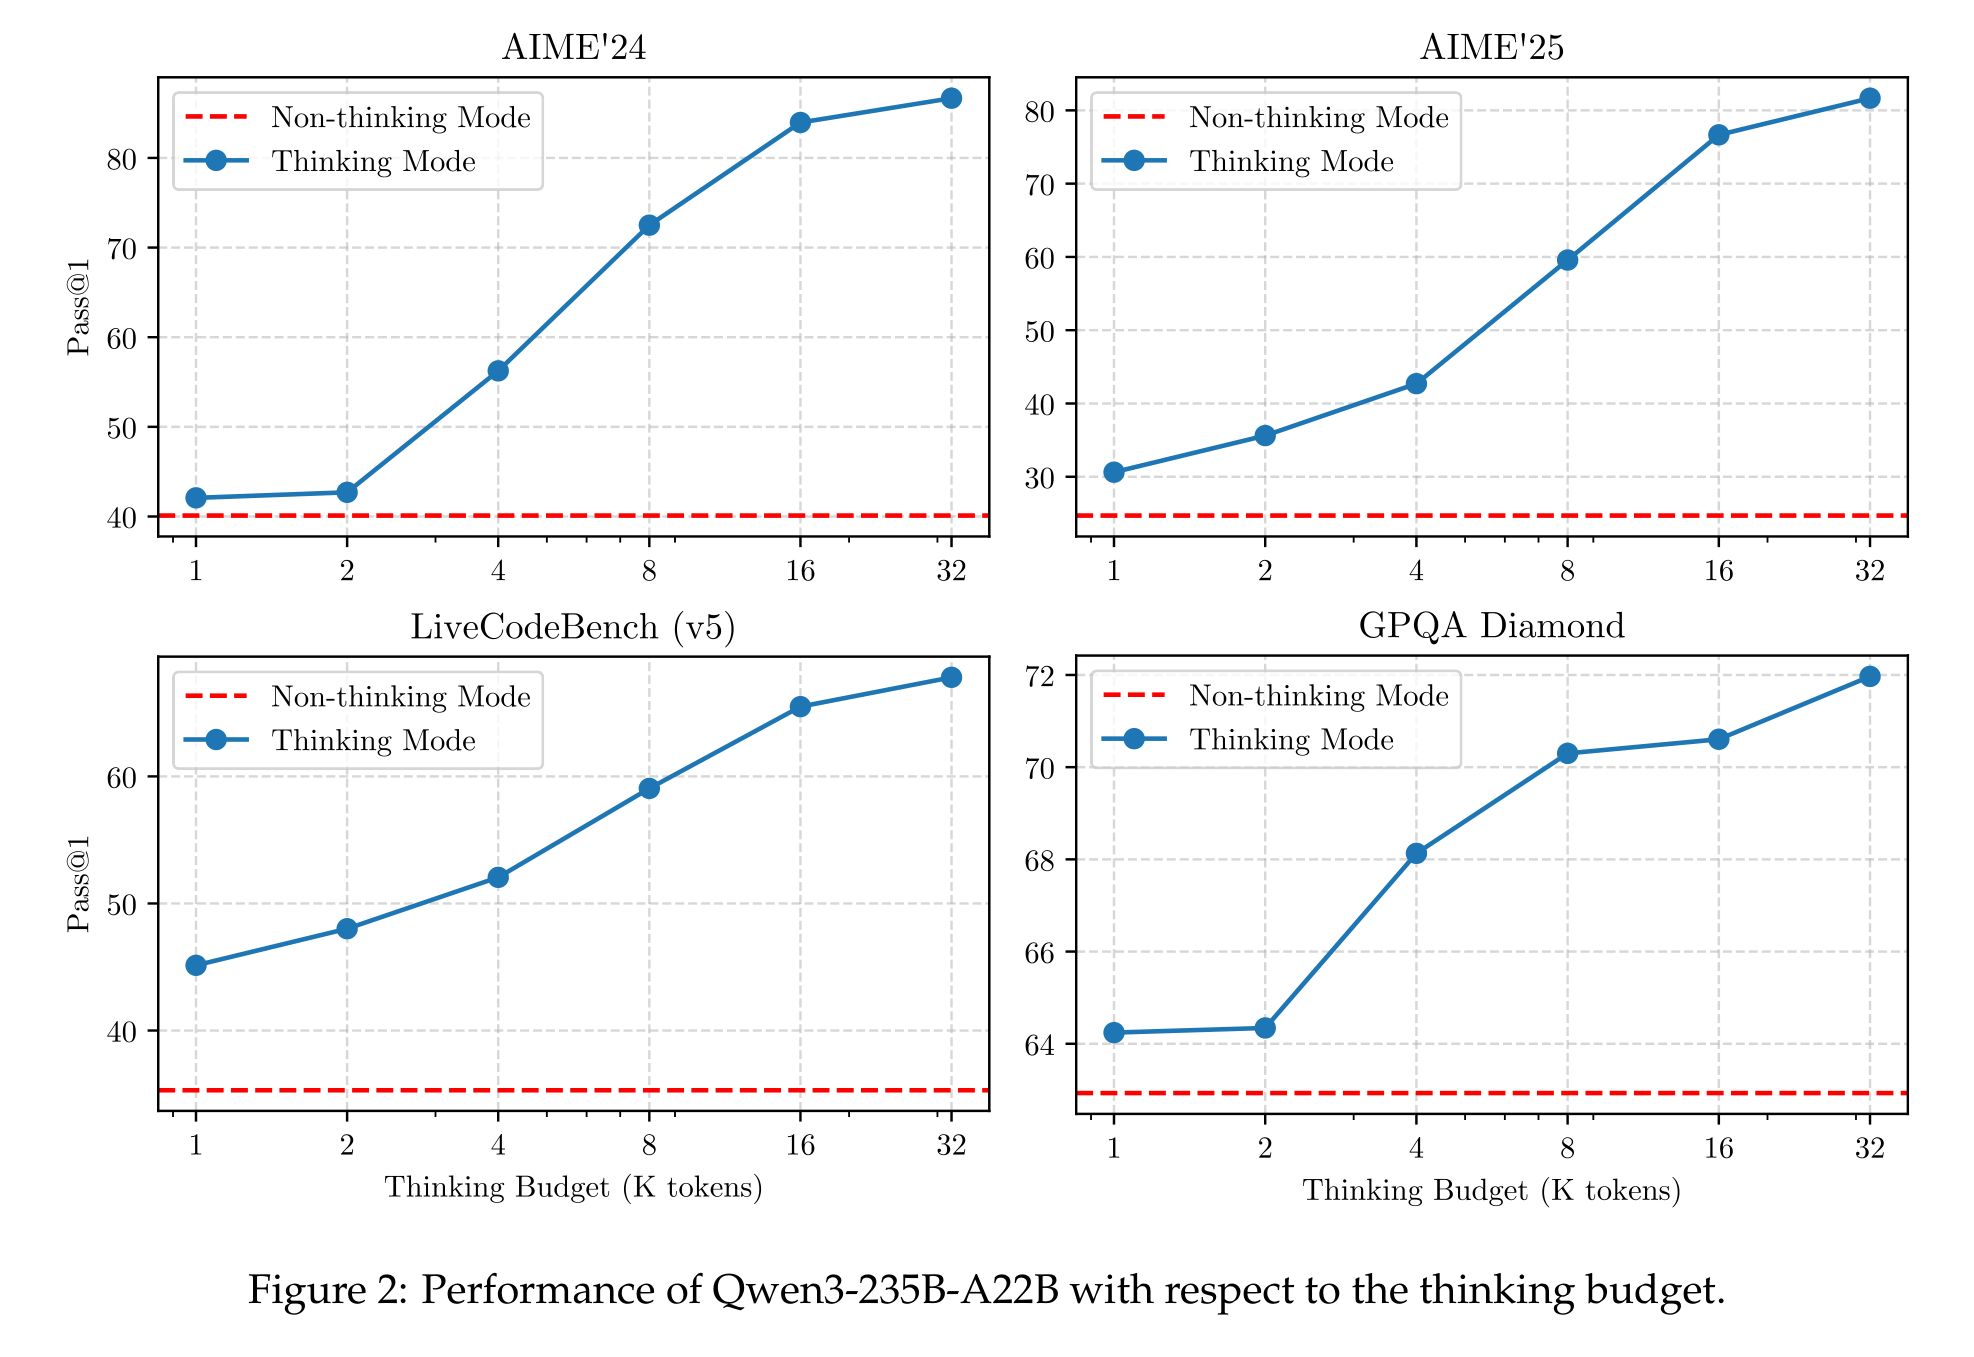
Figure 2 measures the result on Qwen3-235B-A22B across AIME'24, AIME'25, LiveCodeBench v5 and GPQA-Diamond, with budgets from 1K to 32K tokens. Performance rises smoothly and consistently with budget and every thinking-mode point sits above the non-thinking baseline. The authors also expect that extending output length beyond 32K would improve performance further, and leave it as future work. For users, the practical reading is that latency and accuracy trade off along a curve, not a cliff.
Key Points
- 1
When thinking reaches a user-defined threshold, generation is halted and a stop-thinking instruction plus </think> is inserted
- 2
The model then answers from its partial reasoning — no separate controller or budget token
- 3
This ability is not explicitly trained; it emerges from Thinking Mode Fusion teaching both endpoints
- 4
Figure 2 sweeps budgets of 1K–32K tokens on AIME'24, AIME'25, LiveCodeBench v5 and GPQA-Diamond
- 5
Performance improves smoothly and consistently with budget, above the non-thinking baseline at every budget shown
- 6
The authors expect further gains beyond 32K output tokens and leave this to future work
- 7
In the long-context appendix the budget is set to 8,192 tokens to curb overly verbose reasoning on very long inputs
Mathematical Formulation
Budget-Forced Decoding
y=[⟨think⟩t1:min(T,B)⊕sstop⟨/think⟩]⊕answer∼pθ(⋅∣x,t1:min(T,B),sstop)
The model would think for T tokens; with budget B<T the trace is cut at B, the fixed stop-thinking string sstop and the closing think tag are appended, and the answer is conditioned on the truncated trace. With B=0 this reduces to the trained non-thinking mode (an empty think block); with B≥T it is the full thinking mode.
Stage 4 broadens the model across everyday use. A reward system covers over 20 distinct tasks, each with its own scoring, targeting instruction following, format following (including respecting /think and /no_think and using the think tags correctly), preference alignment, agent ability, and specialised scenarios such as RAG, where rewards push against hallucination. For agent tasks the RL rollouts include complete multi-turn interaction cycles with real environment execution feedback.
Three reward types cover different kinds of task. Rule-based rewards are precise and resistant to reward hacking, and suit instruction and format adherence. Model-based rewards with a reference answer have Qwen2.5-72B-Instruct score a response against a reference, avoiding the false negatives a strict rule would produce on correctly phrased but differently formatted answers. Model-based rewards without a reference use a reward model trained on human preference data for open-ended queries.
The report is candid about what this costs. On Qwen3-32B (Table 22), Stage 4 lifts ThinkFollow from 88.7 to 98.9, ToolUse by +15.1 in thinking mode, and Arena-Hard to 93.8. But on knowledge, STEM, maths and coding, Stages 3 and 4 bring no significant gains, and on the hardest benchmarks thinking-mode scores fall — AIME'24 from 83.8 after Stage 2 to 81.4, LiveCodeBench v5 from 68.4 to 65.7. The authors conjecture that training on a broader range of general tasks compromises specialised skill on complex problems, and say they chose to accept this trade-off for overall versatility. It is a useful reminder that a unified model is not free: some peak reasoning is paid for generality.
Key Points
- 1
Reward system covers 20+ tasks: instruction following, format following, preference alignment, agent ability, specialised scenarios (e.g. RAG)
- 2
Rule-based rewards: high precision, resistant to reward hacking — used for instruction following and format adherence
- 3
Model-based rewards with reference: Qwen2.5-72B-Instruct scores responses against a reference answer, avoiding rule-based false negatives
- 4
Model-based rewards without reference: a reward model trained on human preference data handles open-ended queries
- 5
Agent RL rollouts run full multi-turn cycles with real environment execution feedback
- 6
On Qwen3-32B, Stage 4 raises ThinkFollow 88.7 → 98.9 and ToolUse +15.1 (thinking) / +13.3 (non-thinking)
- 7
Trade-off accepted: thinking-mode AIME'24 83.8 → 81.4 and LiveCodeBench v5 68.4 → 65.7 from Stage 2 to Stage 4
Mathematical Formulation
Net Effect of Stages 3–4 on Hard Reasoning (Qwen3-32B, thinking)
ΔAIME’24=81.4−83.8=−2.4,ΔLCB v5=65.7−68.4=−2.7,ΔThinkFollow=98.9−88.7=+10.2
Values from Table 22 (Stage 2 → Stage 4 for the two reasoning benchmarks; Stage 3 → Stage 4 for ThinkFollow, which has no Stage 2 score). A few points of peak reasoning are traded for reliable mode switching, tool use and alignment.
Running the full four-stage pipeline for every model in the family would be expensive and, the report argues, unnecessary. The five smaller dense models (0.6B, 1.7B, 4B, 8B, 14B) and Qwen3-30B-A3B are instead built by distilling from the flagships — and inherit both modes along the way.
Distillation runs in two phases. Off-policy distillation trains the student on teacher outputs generated in both /think and /no_think modes, giving it basic reasoning skills and mode switching. On-policy distillation then has the student generate responses to sampled prompts in either mode, and fine-tunes it by aligning its logits with those of a teacher (Qwen3-32B or Qwen3-235B-A22B) to minimise the KL divergence. The on-policy phase matters because the student is corrected on the states it actually visits, not only on the teacher's trajectories.
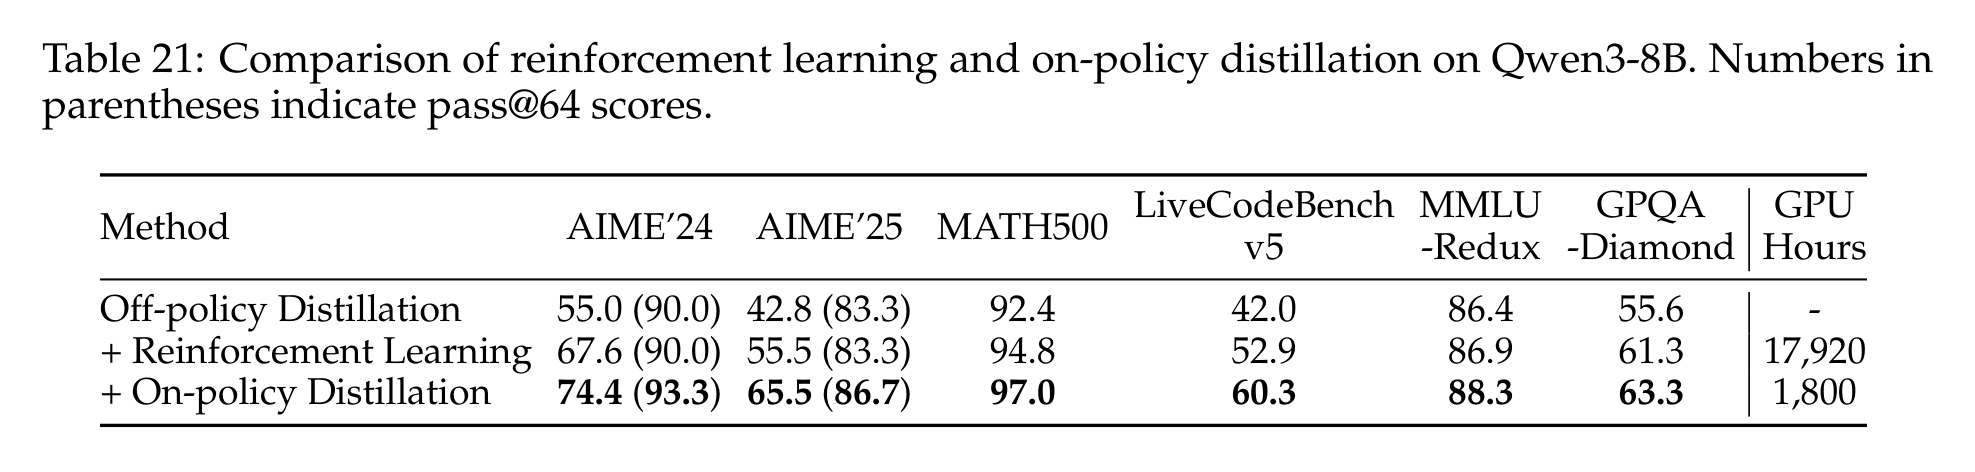
Table 21 compares the two ways of improving the same off-policy-distilled Qwen3-8B checkpoint on maths and code queries. Reinforcement learning takes 17,920 GPU hours and reaches 67.6 on AIME'24. On-policy distillation takes 1,800 GPU hours — about a tenth — and reaches 74.4. The more striking column is pass@64: RL leaves it unchanged (90.0 on AIME'24, 83.3 on AIME'25), while distillation raises it to 93.3 and 86.7. RL sharpens what the student can already sample; distillation from teacher logits expands the set of problems it can solve at all. The authors read this as the advantage of a stronger teacher guiding the student's exploration.
The downstream evidence is consistent: Qwen3-30B-A3B matches QwQ-32B in thinking mode with less than 1/10 of the activated parameters, and the edge models beat larger baselines, including earlier Qwen2.5 models, in both modes.
Key Points
- 1
Applies to Qwen3-0.6B, 1.7B, 4B, 8B, 14B and Qwen3-30B-A3B — the lightweight models skip the four-stage pipeline
- 2
Off-policy phase: learn from teacher outputs in both /think and /no_think modes → basic reasoning + mode switching
- 3
On-policy phase: the student generates; its logits are aligned to the teacher's (Qwen3-32B or Qwen3-235B-A22B) by minimising KL divergence
- 4
On Qwen3-8B, on-policy distillation reaches 74.4 AIME'24 vs 67.6 for RL, using 1,800 vs 17,920 GPU hours
- 5
Distillation improves pass@64 (AIME'24 90.0 → 93.3, AIME'25 83.3 → 86.7); RL leaves pass@64 unchanged
- 6
Overall, distillation needs only about 1/10 of the GPU hours of the four-stage method for lightweight models
Mathematical Formulation
On-Policy Logit Distillation
minθEx,y∼πθ(⋅∣x)∑tDKL(pT(⋅∣x,y<t)pθ(⋅∣x,y<t))
Sequences y are sampled from the student πθ (on-policy), and at every position the student's next-token distribution is matched to the teacher's pT. The report states only that logits are aligned “to minimize the KL divergence” and does not specify the KL direction; the forward form is shown here.
Compute Ratio
1,800 GPU h (distill)17,920 GPU h (RL)≈10×,74.4−67.6=+6.8 AIME’24
From Table 21: distillation costs about a tenth as much as RL from the same checkpoint and scores higher.
The headline comparison is between Qwen3-235B-A22B and the strongest open and closed models of the time, in both modes.
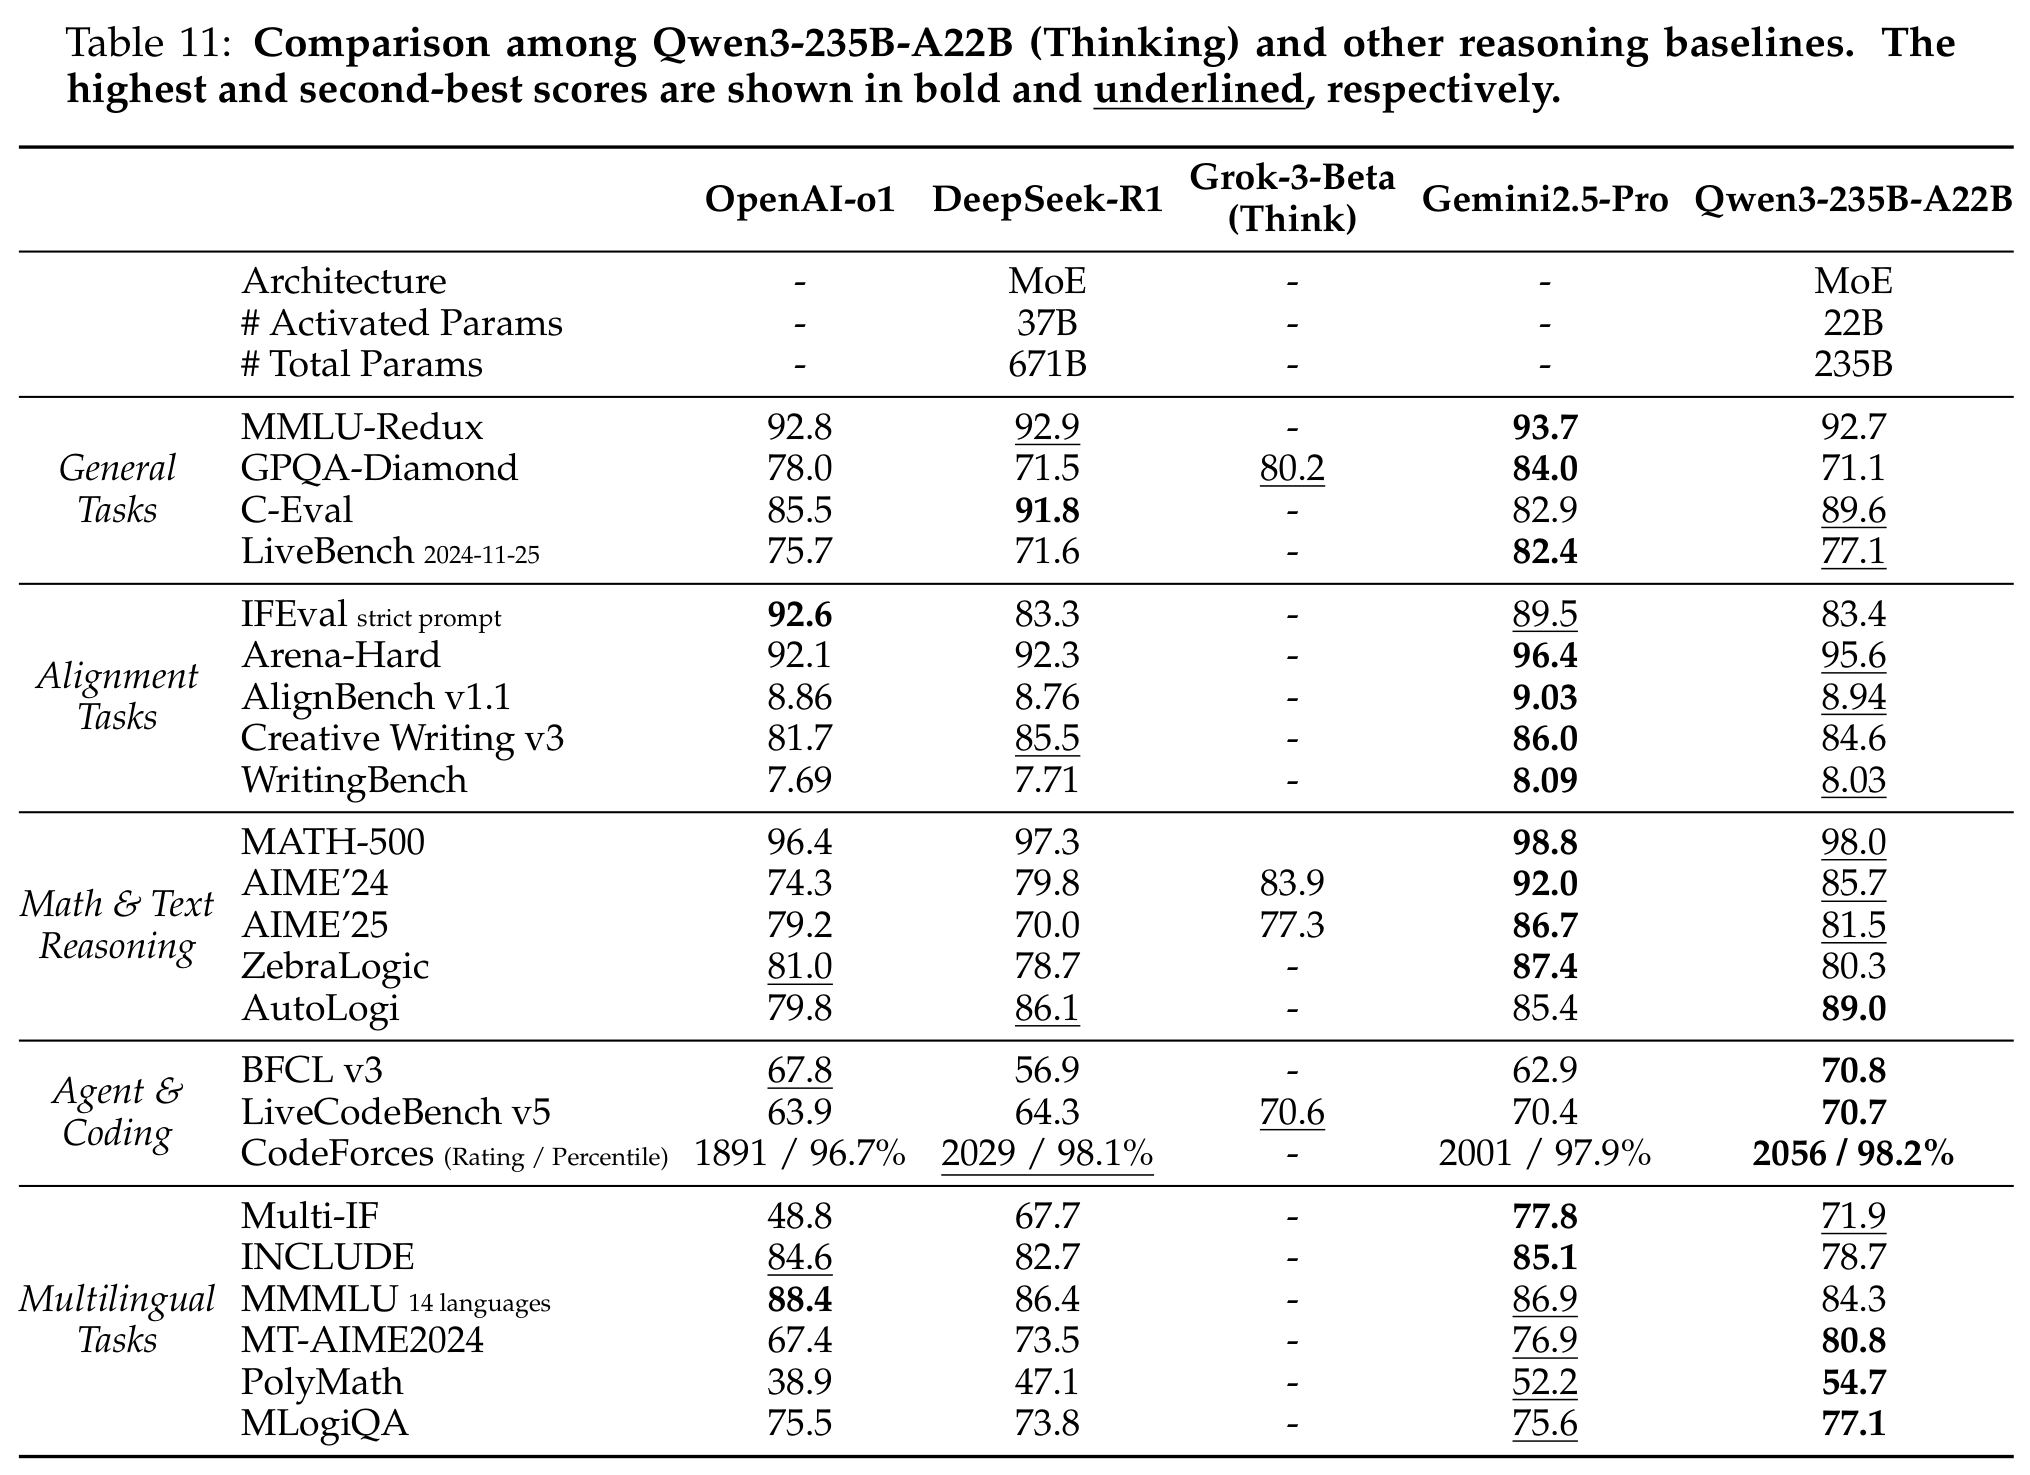
In thinking mode (Table 11), the flagship scores 85.7 on AIME'24, 81.5 on AIME'25, 70.7 on LiveCodeBench v5, 70.8 on BFCL v3 and a 2,056 CodeForces rating (98.2th percentile). With about 60% of the activated and 35% of the total parameters of DeepSeek-R1, it outperforms R1 on 17 of 23 benchmarks, especially on maths, agent and coding tasks. It remains behind Gemini 2.5 Pro on several reasoning benchmarks (for example 92.0 vs 85.7 on AIME'24) but, the authors argue, substantially narrows the open/closed gap.
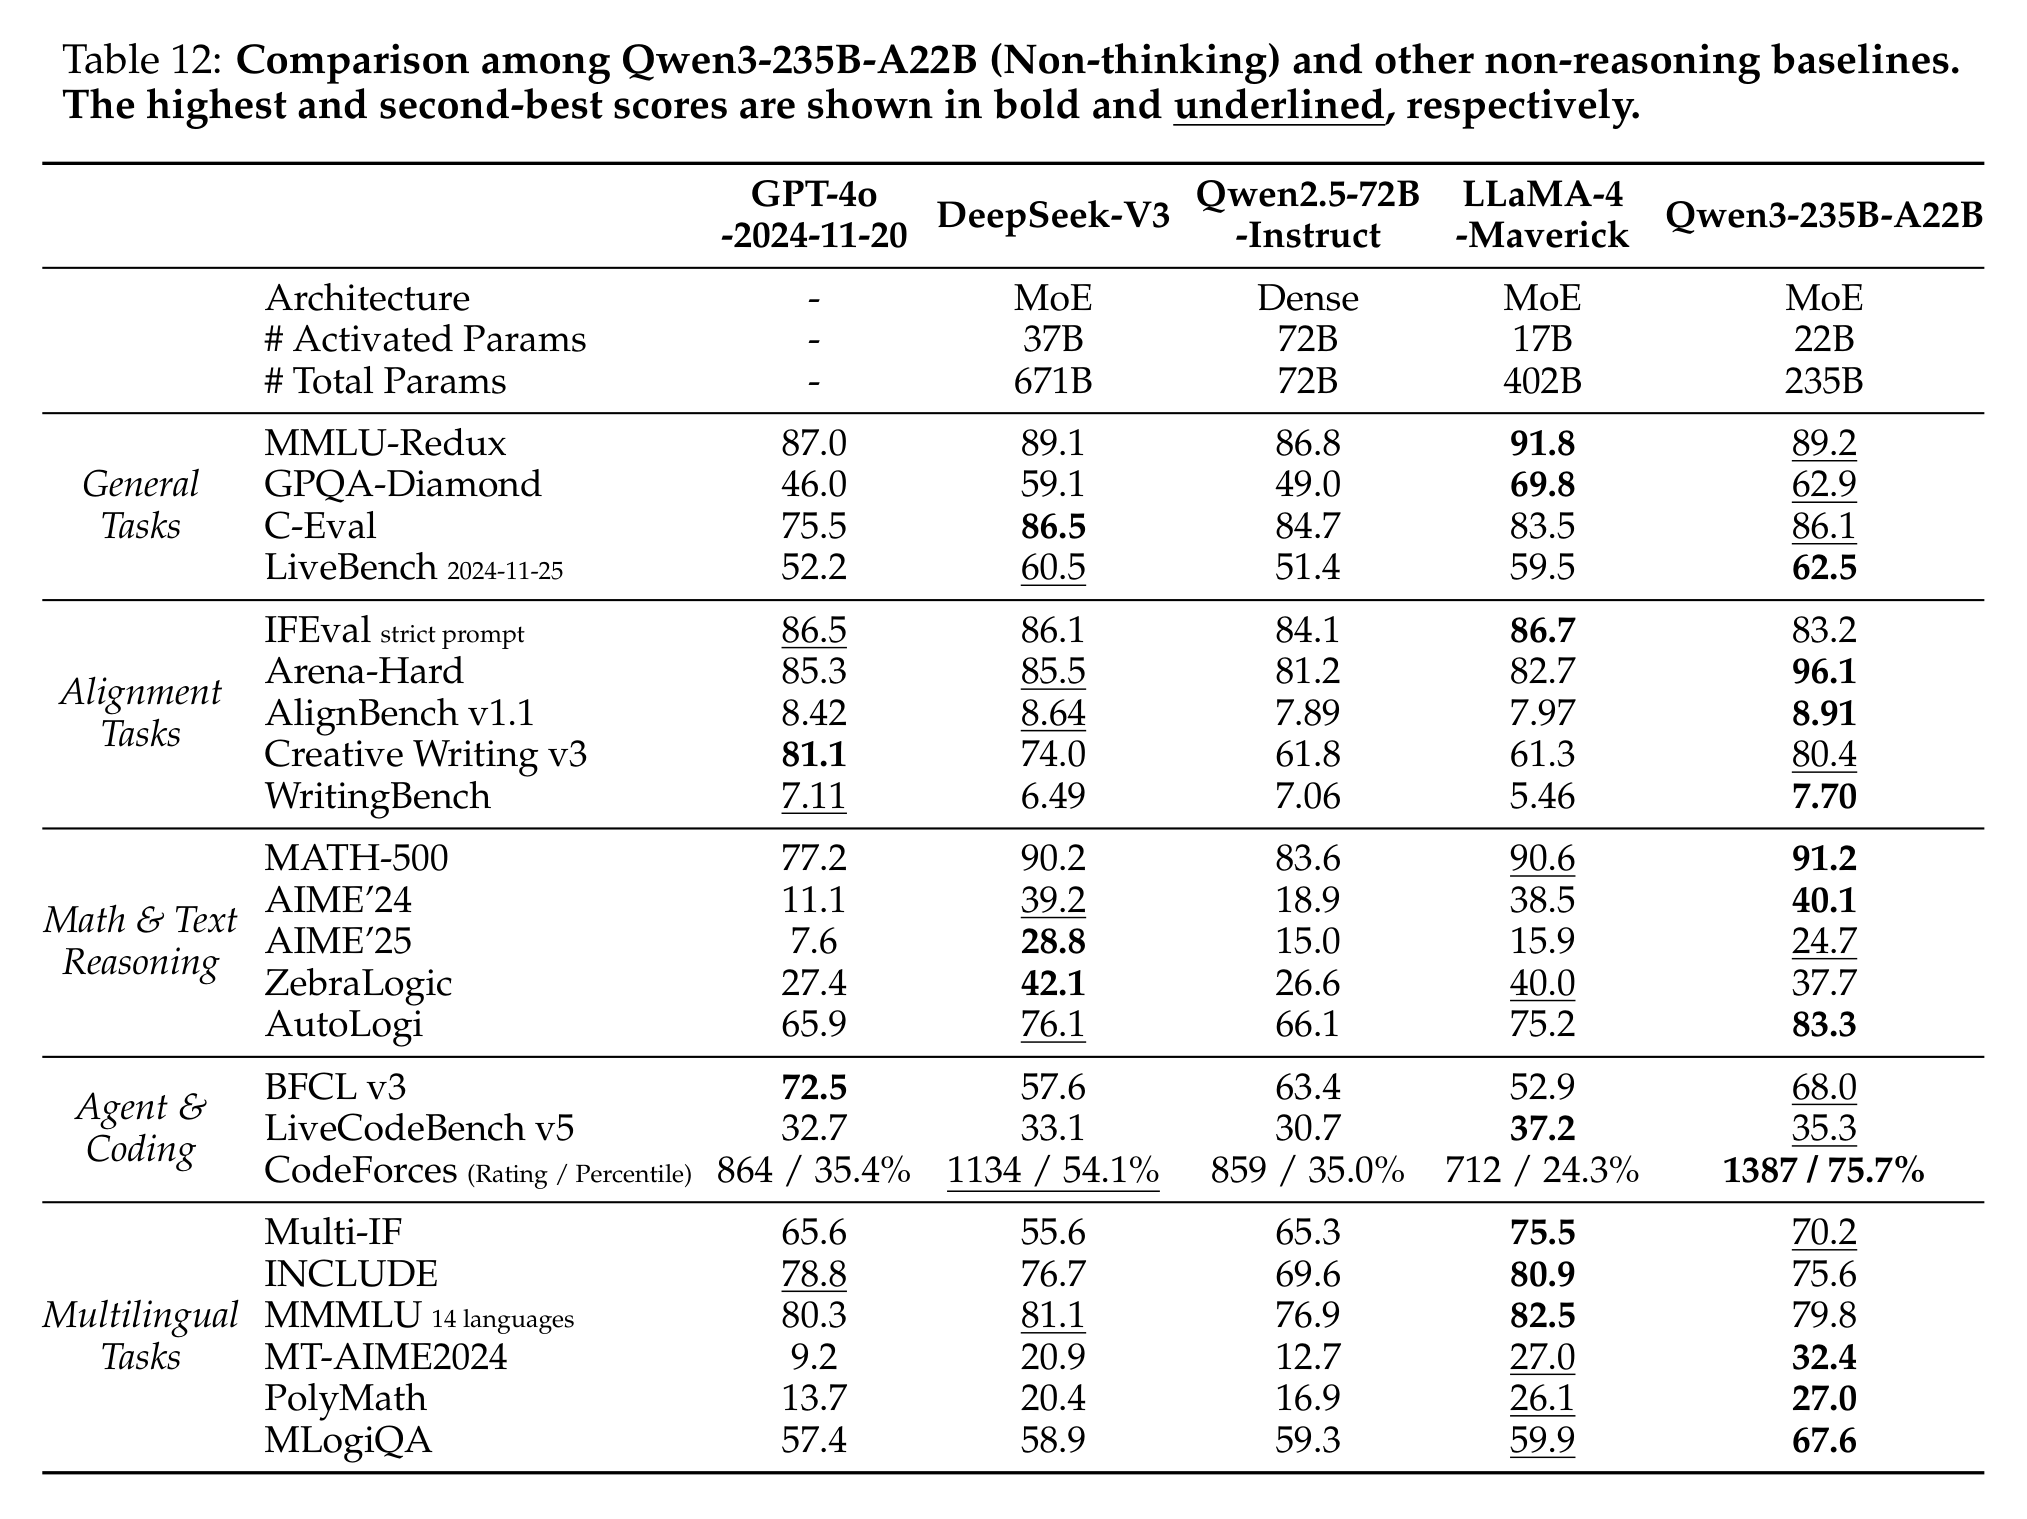
In non-thinking mode (Table 12), it beats DeepSeek-V3, LLaMA-4-Maverick and Qwen2.5-72B-Instruct, and surpasses GPT-4o-2024-11-20 on 18 of 23 benchmarks — notably 96.1 on Arena-Hard and a 1,387 CodeForces rating against GPT-4o's 864.
Further down the family, Qwen3-32B (thinking) beats QwQ-32B on 17 of 23 benchmarks and competes with OpenAI-o3-mini (medium); in non-thinking mode it surpasses Qwen2.5-72B-Instruct. The distilled Qwen3-30B-A3B and 14B are highly competitive with QwQ-32B in thinking mode. Multilingual evaluation spans Multi-IF (8 languages), INCLUDE (44), MMMLU (14), MT-AIME2024 (55), PolyMath (18) and MLogiQA (10), with Qwen3-235B-A22B (thinking) scoring 80.8 on MT-AIME2024 — ahead of Gemini 2.5 Pro's 76.9.
All thinking-mode results use temperature 0.6, top-p 0.95, top-k 20; non-thinking uses temperature 0.7, top-p 0.8, top-k 20 and a presence penalty of 1.5. Max output is 32,768 tokens, extended to 38,912 for AIME.
Key Points
- 1
Thinking mode: AIME'24 85.7, AIME'25 81.5, LiveCodeBench v5 70.7, BFCL v3 70.8, CodeForces 2,056 (98.2%)
- 2
Beats DeepSeek-R1 on 17/23 benchmarks with ~60% of its activated and ~35% of its total parameters
- 3
Non-thinking mode: beats GPT-4o-2024-11-20 on 18/23 benchmarks; Arena-Hard 96.1, CodeForces 1,387 vs 864
- 4
Still behind Gemini 2.5 Pro on several reasoning benchmarks (AIME'24 92.0, GPQA-Diamond 84.0 vs 85.7 and 71.1)
- 5
Qwen3-32B (thinking) beats QwQ-32B on 17/23 benchmarks and is comparable to OpenAI-o3-mini (medium)
- 6
Multilingual: MT-AIME2024 80.8 across 55 languages for the flagship in thinking mode (Gemini 2.5 Pro: 76.9)
- 7
Sampling: thinking T=0.6/top-p 0.95/top-k 20; non-thinking T=0.7/top-p 0.8/top-k 20, presence penalty 1.5; max output 32,768 (38,912 for AIME)
Mathematical Formulation
The Thinking-Mode Dividend (Qwen3-235B-A22B)
AIME’24:40.1→85.7 (+45.6),AIME’25:24.7→81.5 (+56.8),LCB v5:35.3→70.7 (+35.4)
Same weights, different flag: non-thinking (Table 12) vs thinking (Table 11). This is the gap the thinking budget lets users traverse continuously.
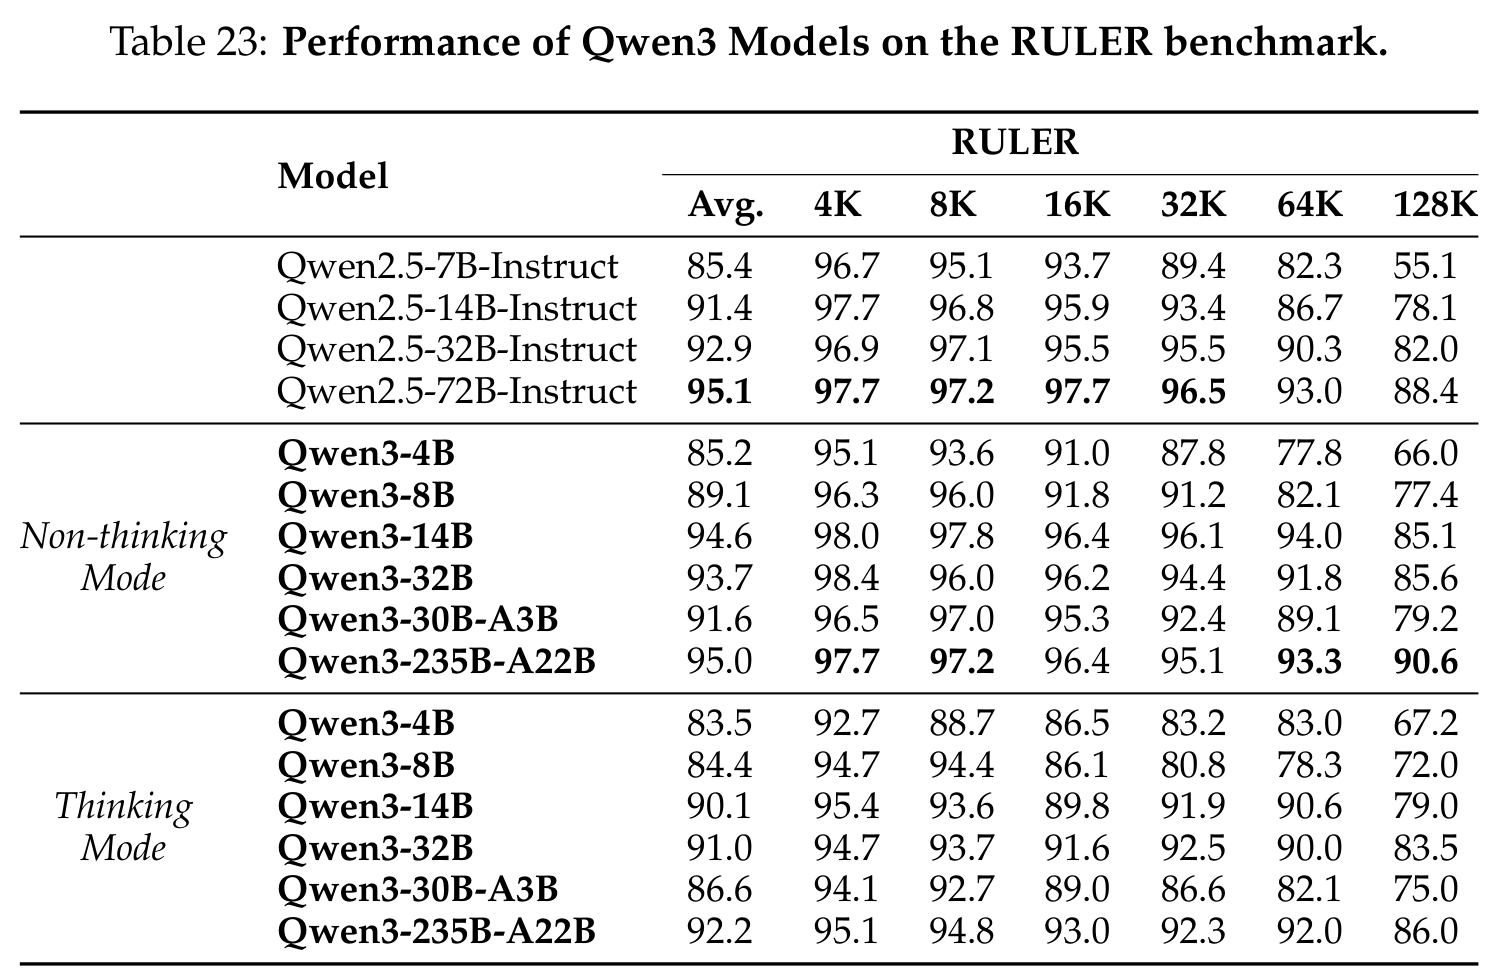
The appendix reports long-context ability on RULER, using YARN with a scaling factor of 4, and here the unified model shows a revealing weakness. In non-thinking mode, Qwen3 outperforms Qwen2.5 models of similar size — Qwen3-235B-A22B averages 95.0 and holds 90.6 at 128K. In thinking mode, with the budget capped at 8,192 tokens, performance slightly degrades: the flagship averages 92.2 and drops to 86.0 at 128K.
The authors' hypothesis is simple: RULER is a retrieval benchmark. Thinking does not help find a needle, and a long reasoning trace may interfere with retrieval. That is a useful corrective to the idea that more test-time compute always helps. Thinking is a tool for tasks that need composition and search; for lookups it can be noise, which is exactly why a mode switch — rather than an always-on reasoner — is worth having.
The report is also open about its other trade-offs. General RL costs a few points of peak thinking-mode reasoning on AIME and LiveCodeBench, an accepted price for versatility. The thinking-budget curves have not saturated at 32K, so the ceiling is still unmeasured. And the non-thinking mode, strong as it is, still trails the thinking mode by tens of points on competition maths.
The stated future directions follow from these: scale pre-training with higher-quality and more diverse data; improve architecture and training for effective compression and extremely long contexts; and increase RL compute, with emphasis on agent-based RL systems that learn from environmental feedback for tasks that need inference-time scaling.
Key Points
- 1
RULER evaluation uses YARN with scaling factor 4; thinking mode uses an 8,192-token budget
- 2
Non-thinking: Qwen3 beats similar-size Qwen2.5 models; Qwen3-235B-A22B averages 95.0, 90.6 at 128K
- 3
Thinking: performance slightly degrades — Qwen3-235B-A22B averages 92.2, 86.0 at 128K
- 4
Hypothesis: retrieval tasks do not benefit from reasoning, and thinking content may interfere with retrieval
- 5
Other acknowledged trade-offs: General RL lowers peak AIME / LiveCodeBench thinking scores; budget curves are unsaturated at 32K
- 6
Future work: better and more diverse pre-training data, compression and extremely long context, and agent-based RL from environmental feedback
Keep reading
Related Papers
Go deeper